Ask a database questions in English. The model writes a typed query plan, never SQL text; the plan is checked against the real schema and the caller's role before any SQL is generated.


https://nadeem4nk-nl2sql-demo.hf.space — the playground on three sample databases, nothing to install.
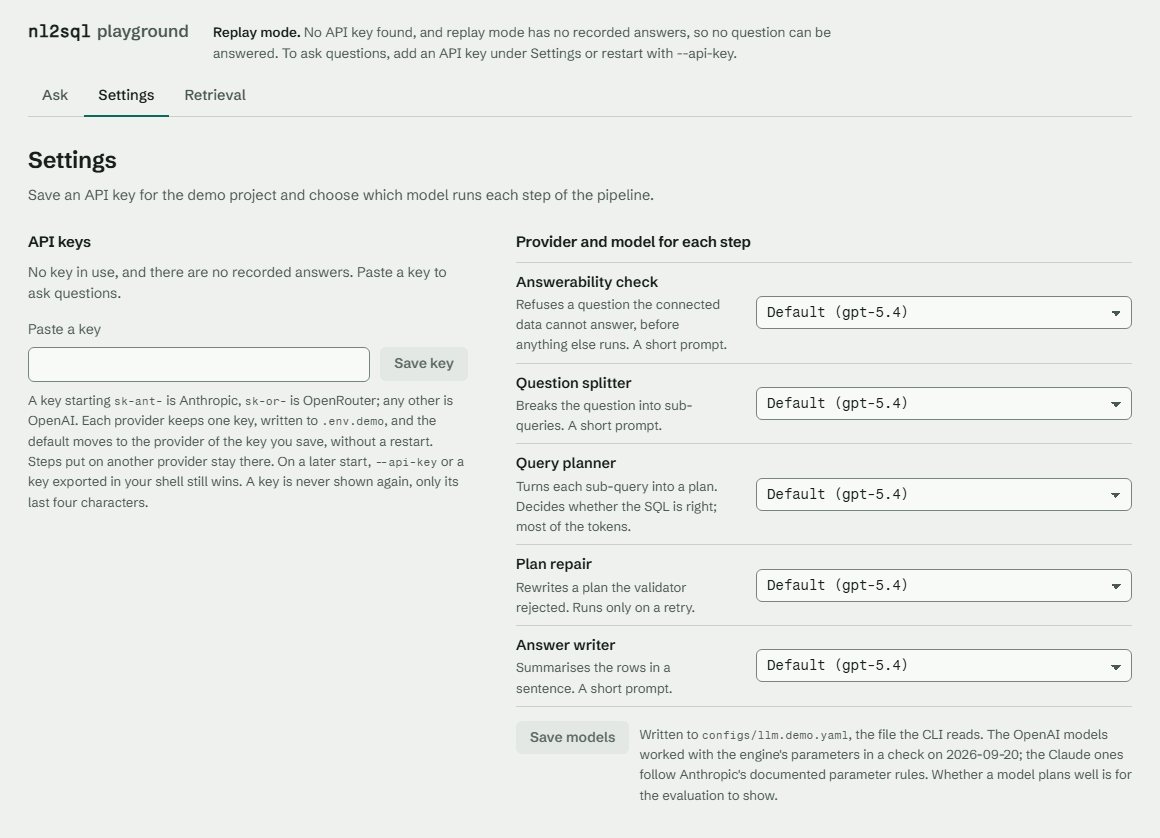
Bring your own key. The server holds none. You paste yours into the page — one per provider — it stays in that browser tab, travels with the question that needs it, is used in memory for that question and dropped: never stored, never logged, never written to a trace. Settings also puts each of the five model-using steps on a provider and model of its own, so the planner can be on Claude while the rest stays on OpenAI. The sample databases are opened read-only, and questions are rate limited per visitor and capped per session. How it is built: Hosted demo.
Prefer it on your own machine? Quickstart.
- Try it in your browser
- How it works
- Latest benchmark results
- Quickstart: run it locally
- Screenshots
- CLI reference
- REST API
- Python SDK
- Configuration
- Security and what is sent to the model
- Evaluation and quality
- Project status, limitations and roadmap
- Contributing and license
- The question is checked for answerability and routed to one of the registered databases, then split into sub-queries; the decomposer also builds the execution DAG that says which sub-queries can run together and how their results combine.
- Each sub-query gets the part of the schema it needs (vector search over an index of tables, columns and relationships, or the whole schema when it is small).
- The model returns a typed plan (a Pydantic
PlanModel: tables, joins, select items, filters), never a SQL string. It may only name a function from an allow-list, and it writes date work portably —DATE_PART/DATE_TRUNCover a fixed set of units — which each adapter renders in its own dialect. - The logical validator resolves every table and column against the schema, checks joins against the declared foreign keys, checks every table against the caller's role (RBAC), and builds the query tree the generator would build, so a plan whose tables cannot be joined is caught here, where the planner can still be asked to fix it. A refused plan never becomes SQL.
- Only a plan that passes reaches the generator, which renders SQL
deterministically with
sqlglot. The executor runs it and the answer writer summarises the rows. - A retryable validation failure goes back to the planner through a refiner, up
to
SQL_AGENT_MAX_RETRIES(default 3). A security refusal is final.
flowchart LR
    Q([Question]) --> R[Resolve datasource<br/>and decompose]
    R --> S[Schema retrieval]
    S --> P[LLM planner<br/>typed plan, no SQL]
    P --> V{Validator<br/>schema, joins, RBAC}
    V -->|retryable| F[Refiner] --> P
    V -->|refused| X([Refusal with reason])
    V -->|passed| G[SQL generator<br/>sqlglot]
    G --> E[Executor] --> A([Answer])
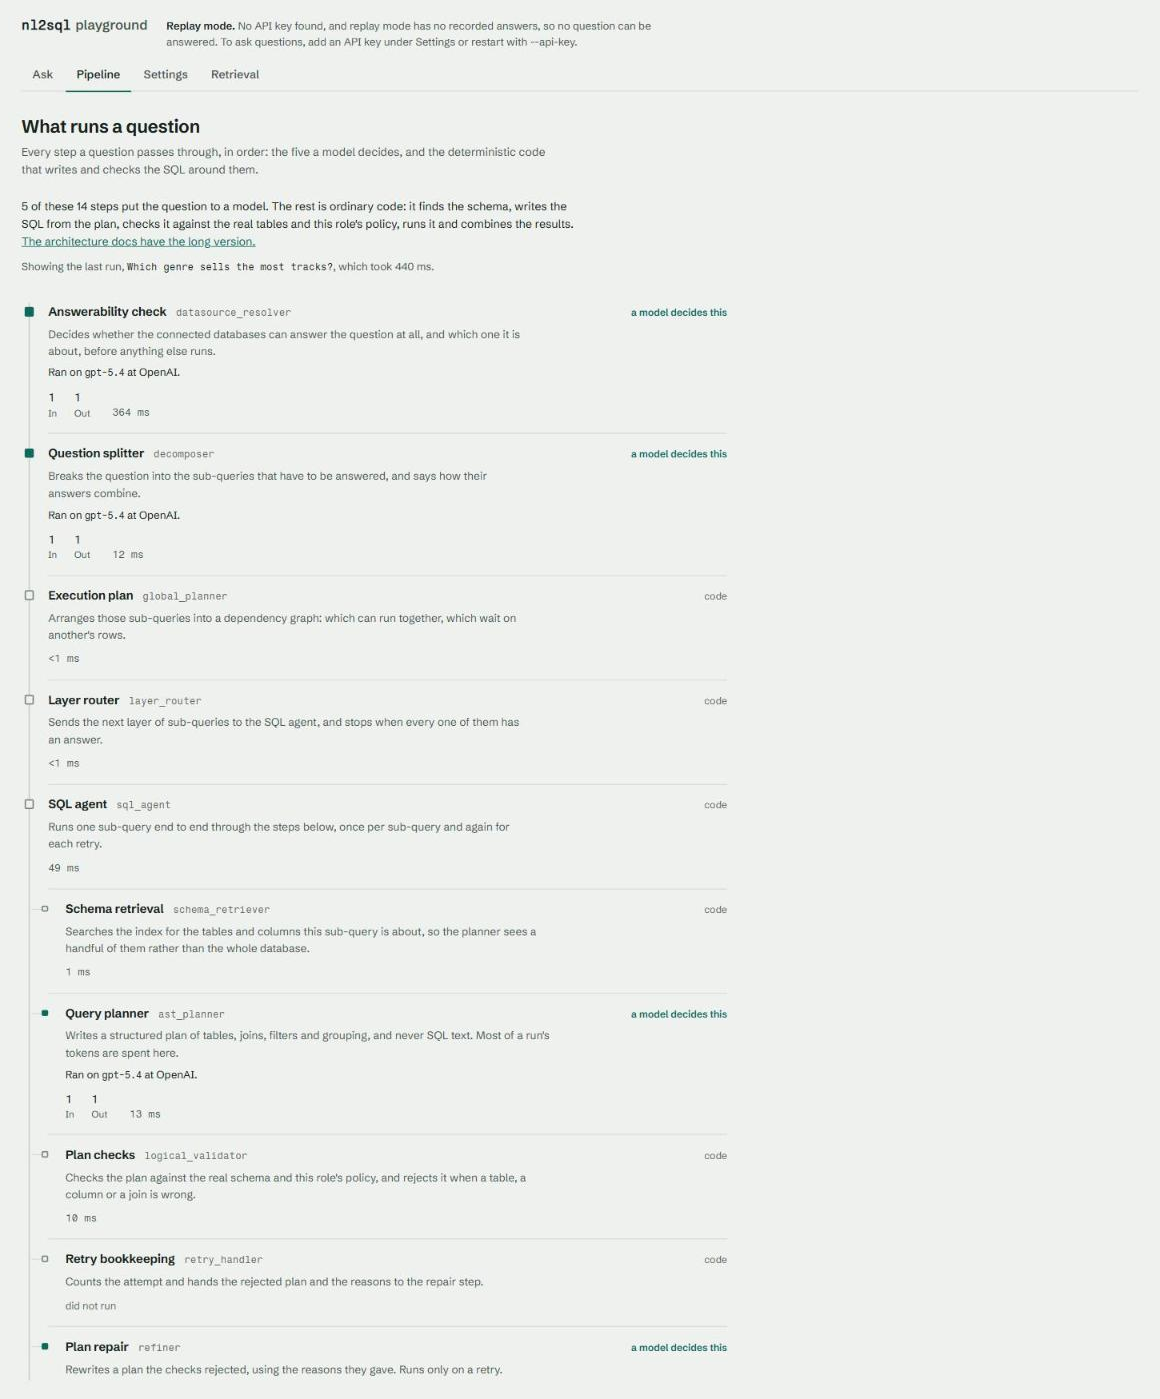
That is the shape of a run; the full pipeline is 13 steps, five of them decided by a model, and the playground's Pipeline page lists them all.
Architecture detail: System Architecture, Pipeline, Agent Nodes, Determinism.
Generated by nl2sql benchmark publish from the records in
benchmarks/. Every run, with models, tokens, latency
and determinism: docs/benchmarks.md.
The real model end to end on the Chinook gold questions. Accuracy is the strict share whose rows match the gold answer exactly, or that are refused where the gold set expects a refusal; lenient allows extra and reordered columns and date labels; faithfulness is the share of written answers whose numbers and names come from the rows.
| Config | Database | Date (UTC) | Commit | Accuracy (strict) | Accuracy (lenient) | Faithfulness | $/question | Δ vs previous |
|---|---|---|---|---|---|---|---|---|
| gpt-5.4 | chinook | 2026-09-23 | de42c40 | 79.1% [64.8-88.6] | 79.1% | 86.8% | $0.0194 | new series (dataset changed) |
The share of each answerable gold question's needed tables and columns that schema retrieval sends the planner, with no LLM involved.
| Database | Date (UTC) | Commit | Table recall | Column recall | Δ vs previous |
|---|---|---|---|---|---|
| chinook | 2026-09-22 | 571cd16 | 98.5% | 72.6% | first run |
Full history: docs/benchmarks.md
Requires Python 3.12 or newer.
pip install "nl2sql-engine[demo]"
nl2sql demo
The
democommand, the[demo]extra and most of what this README describes are onmainand not yet in a PyPI release (the latest is 0.1.2). Until the next release, install from a clone:pip install -e packages/adapter-sdk -e "packages/nl2sql[demo]"(add-e packages/apifor the REST server).
nl2sql demo writes a demo project into ./nl2sql-demo, copies in three
SQLite databases and indexes their schemas on your machine, serves the
playground on http://127.0.0.1:8765/ and opens your browser. The databases
are the Chinook sample database (11 tables, real
foreign keys), support, a help desk (4 tables), and webanalytics, website
traffic (5 tables); the last two are synthetic, generated by this repository
from a fixed seed, and share Chinook's customer identities. All three declare
their foreign keys. Indexing needs no API key; the first run downloads a ~79 MB
ONNX embedding model.
Answering a question needs a model. The demo looks for one in this order:
--api-key KEY(saved to the project's.env.demo, so later runs stay live)OPENAI_API_KEY,OPENROUTER_API_KEYorANTHROPIC_API_KEYin the environment- a key already saved in
.env.demo - an Ollama daemon on
localhost:11434 - replay mode
The provider follows the key's shape: sk-ant-... is Anthropic, sk-or-... is
OpenRouter, anything else is OpenAI. Claude needs the extra:
pip install "nl2sql-engine[demo,anthropic]". You can also start without a key
and paste one into the playground's Settings page, which switches the
running demo to live mode without a restart and picks a model per step.
Without a key, the demo runs in replay mode, which answers only from
recorded model responses. None ship with the engine, so the console and the page
say "replay mode has no recorded answers" and a question gets "No recorded
answer for this question. Add an API key to ask it live." The schema, the index
and the Retrieval inspector still work. nl2sql demo --record (with an OpenAI
or OpenRouter key) records the guided questions into the project's
recordings.json, and later key-free runs of that folder replay them.
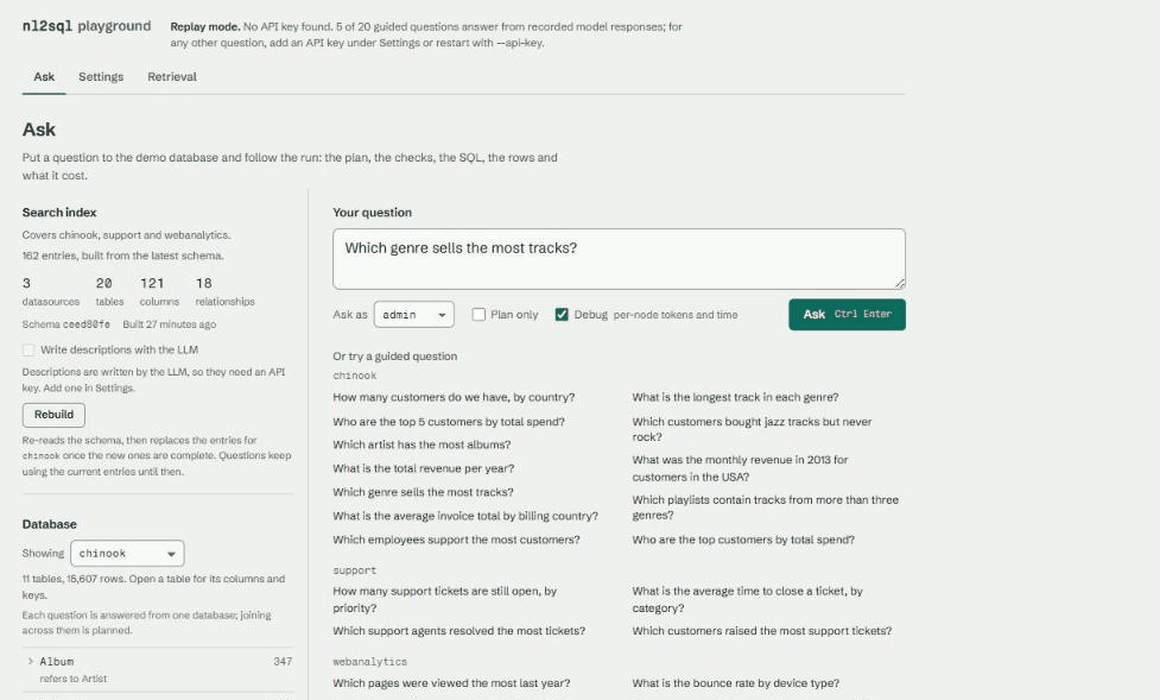
In the playground, pick one of the twenty guided questions -- twelve on
Chinook, four on support, four on webanalytics -- or type one, and choose a
role: admin and analyst can read the customer tables, viewer cannot, so
asking as viewer about customers shows the validator refusing the plan before
any SQL exists. The rail's Showing switcher reads any of the three schemas,
and follows the guided question you click. With three databases registered,
every question is routed first: the resolver picks the one it is about, a step
a single-database demo never reached, and the run says which one answered. A
question that spans two of them is not answerable yet -- each sub-query is
planned against one datasource, so the engine cannot join across databases, and
the shared customer identities are groundwork for when it can.
The playground has no login. It binds to 127.0.0.1 by default; Settings,
Rebuild, the Retrieval inspector and answer ratings are off on any other
address unless you pass --allow-settings. Full guide:
Demo.
nl2sql demo --hosted is a third state: the public demo
above, which you can run yourself. The server holds
no API key, each visitor pastes their own into the page, one per provider, and
the Ask page says so on arrival and keeps the question box closed until a key
is saved, so nobody discovers the requirement by asking. Saving settings,
Rebuild, answer ratings and --record are refused there, and the sample
databases are opened read-only. Two limits keep the pace, both in process and
both best-effort: 6 questions a minute keyed by client address
(NL2SQL_DEMO_QUESTIONS_PER_MINUTE) and 30 a session keyed by a random cookie
(NL2SQL_DEMO_QUESTIONS_PER_SESSION). deploy/huggingface/ is that demo as a
Hugging Face Space, deployed from main by the Publish Space workflow. See
Hosted demo.
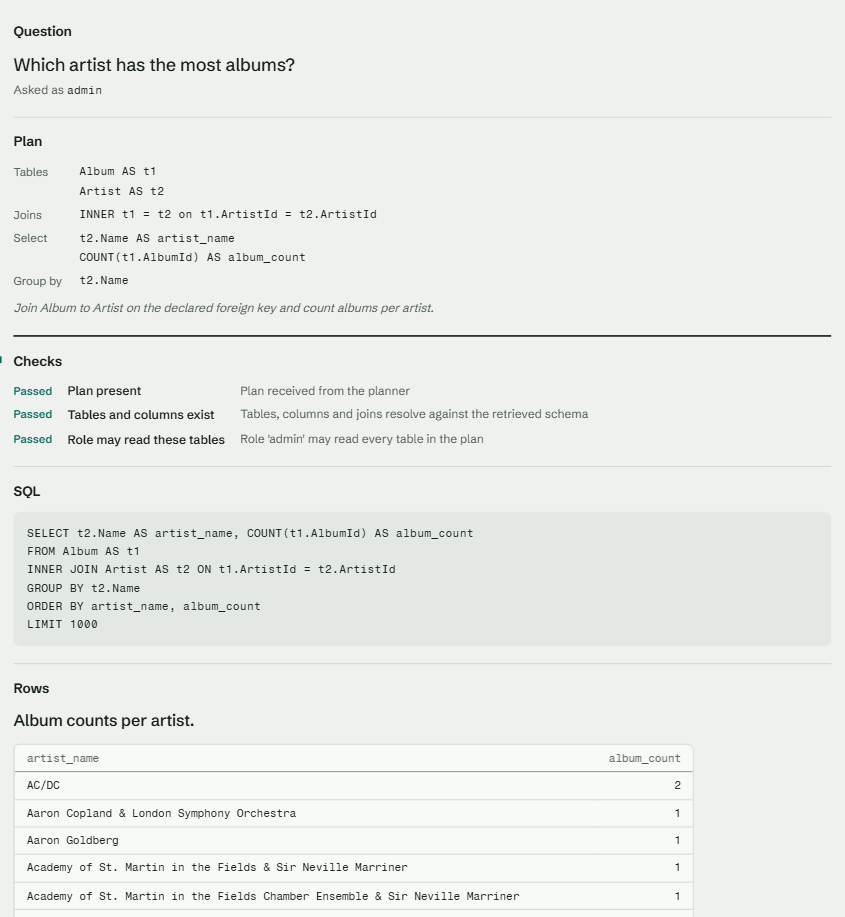
Captured from the playground on the demo project, asking about Chinook, with recorded model responses (so token counts are placeholders).
An answer: the question, the plan the model wrote, the validator's checks, the generated SQL and the rows.
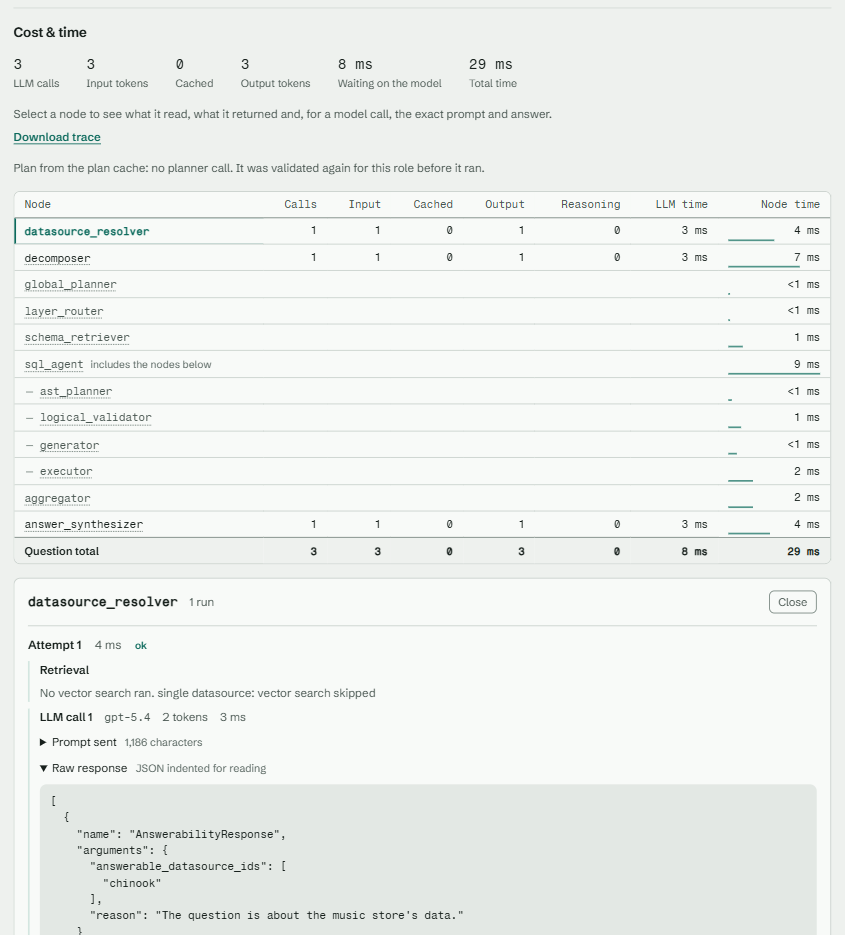
Debug: LLM calls, tokens and time per node in execution order. Open a node to see what it read and returned, the retrieval it ran, and each prompt and raw model response.
Pipeline: every step of a run in order, with the five a model decides marked and the deterministic ones left quiet. Before a question it shows the model each step is set to use; after one, the model that answered, that step's tokens and its time.
Settings: save an API key per provider and choose a provider and model for
each LLM step. Written to the demo project's .env.demo and
configs/llm.demo.yaml.
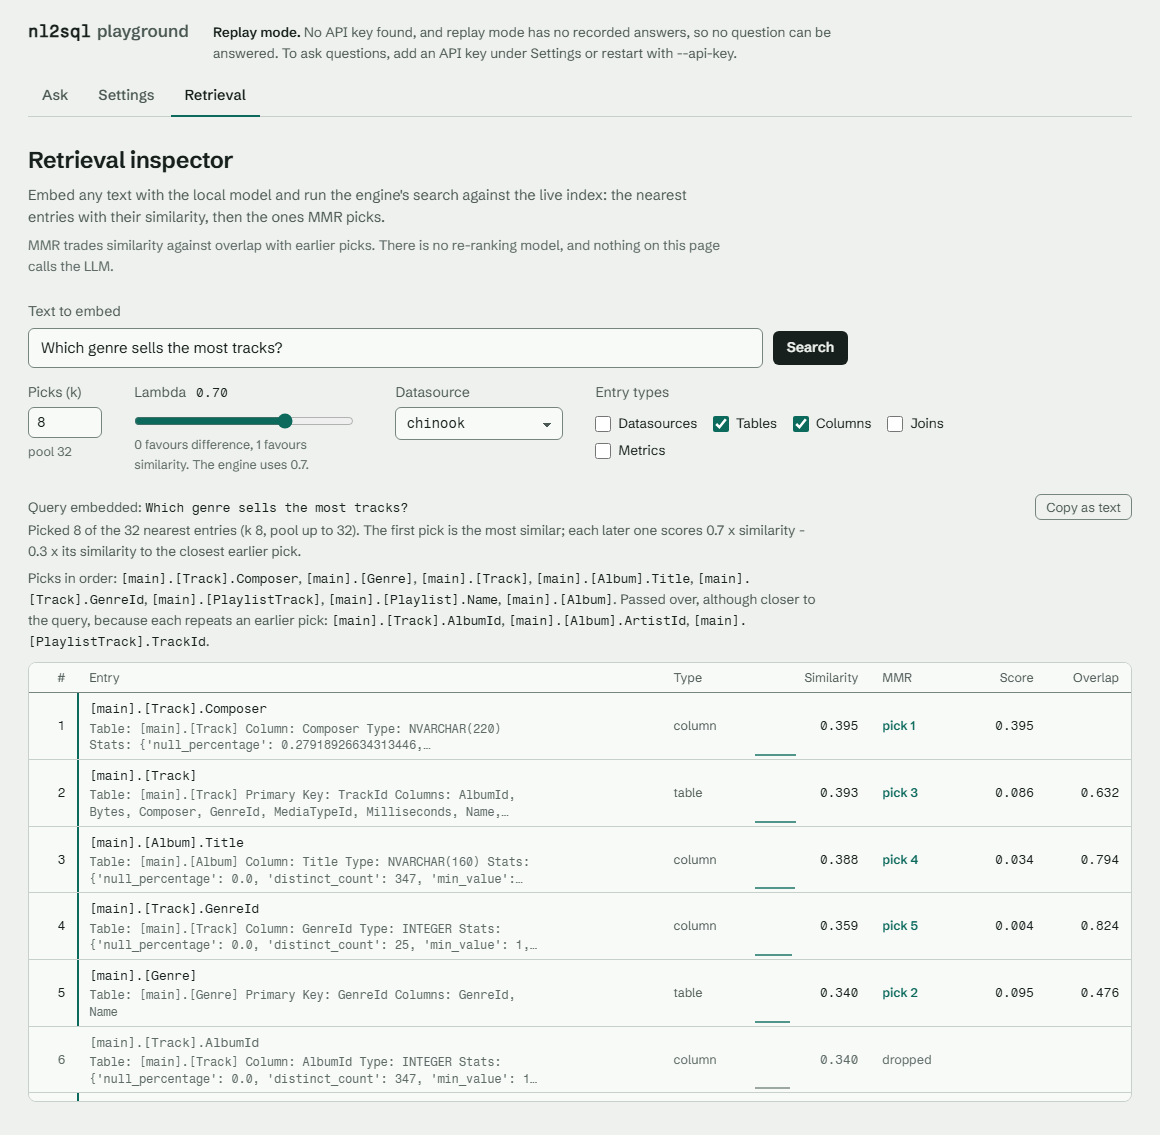
Retrieval inspector: run the engine's vector search for any text against the live index, with k, lambda, entry types and datasource as knobs, and see what MMR picked and what it dropped. No LLM call.
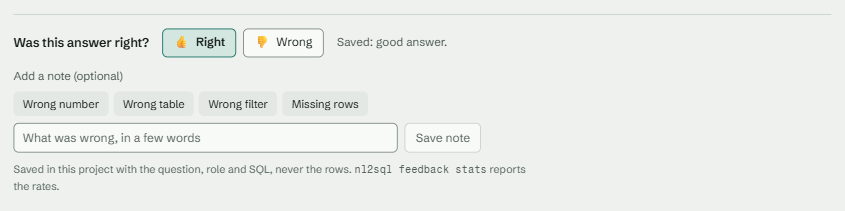
Feedback: rate an answer right or wrong, with an optional note. Stored in the
project with the question, role and SQL, never the rows;
nl2sql feedback stats reports the rates.
Global options: --env NAME loads .env.NAME, --env-file PATH loads that
file instead (and wins over --env), --version prints the installed version.
Variables already exported in your shell win over the file. The demo project's
configs use relative paths, so run --env demo commands from inside the demo
folder (cd nl2sql-demo). Every command has --help.
| Command | Purpose | Key options |
|---|---|---|
nl2sql demo |
Scaffold, index and serve the three-database playground | --dir (default nl2sql-demo), --host (default 127.0.0.1), --port (default 8765), --no-browser, --api-key, --record, --allow-settings, --hosted |
nl2sql setup |
Interactive wizard: writes .env.dev, configs/datasources.yaml, configs/llm.yaml, configs/policies.json, checks connectivity, offers to index |
--demo (write the demo project, all three sample databases, in the current folder and index it, no wizard), --api-key |
nl2sql run "QUESTION" |
Ask a question and print the plan, checks, SQL, rows and answer | --role (default admin), --no-exec (plan and validate only), --ds-id, --verbose/-v, --show-perf, --config, --llm-config, --policies-config, --secrets-config, --vector-store |
nl2sql index |
Index datasource schemas into the vector store, one datasource at a time | --datasource/-d ID (repeatable), --full (rebuild all, needed after changing the embedding model) |
nl2sql doctor |
Check Python, installed drivers, datasource connectivity, the LLM key and the index | |
nl2sql list-adapters |
List the installed datasource adapters | |
nl2sql install NAME |
pip-install the driver extra for an adapter (e.g. postgresql, mysql), after a confirmation |
|
nl2sql policy validate |
Validate policies.json and check it against the configured datasources |
--policies, --config, --secrets |
nl2sql trace show TARGET |
Print a run trace's timeline: nodes, attempts, durations, tokens, errors | a trace file, or a trace id in TRACE_DIR |
nl2sql trace replay TARGET |
Re-run a traced question on its recorded LLM responses, with no model calls | --config, --llm-config, --policies-config, --secrets-config, --vector-store |
nl2sql cache clear |
Empty the plan cache; schema snapshots are kept | |
nl2sql feedback list |
Playground ratings, newest first | --limit (default 50) |
nl2sql feedback stats |
Ratings plus guardrail rates: refusals, refiner retries, validator rejections, errors, plan-cache hits | --json, --traces DIR |
nl2sql feedback export --good |
Write thumbs-up runs as draft gold entries to a separate YAML for review | --out (default feedback_gold_drafts.yaml) |
nl2sql feedback clear |
Delete every rating | --yes |
nl2sql benchmark --tier 1 |
Tier 1: the hand-written gold plans through the validator, generator and executor, with a local fake LLM (no key) | --role (repeatable), --include-ids (repeatable), --export-path |
nl2sql benchmark --tier 2 |
Tier 2: the real model end to end on the gold questions, per config, under a cost cap | --max-cost USD (no default; exits 2 without it), --model (repeatable), --llm PRESET|PATH (repeatable), --passes (default 1), --questions (repeatable), --note, --baseline, --max-regressions (default 2), --max-accuracy-drop (deprecated), --max-cost-increase (default 0.20), --results-dir |
nl2sql benchmark |
Without --tier: the gold questions through the full pipeline with the configured LLM |
--iterations (default 3), --bench-config-path, --role, --include-ids |
nl2sql benchmark retrieval |
Table and column recall of schema retrieval on the gold questions; no key, no LLM | --record, --note, --baseline, --questions, --export-path, --results-dir |
nl2sql benchmark presets |
List the built-in tier 2 LLM configs (gpt-5.4, gpt-5.4-mini-helpers, claude-planner) |
|
nl2sql benchmark publish |
Rebuild docs/benchmarks.md and the README results block from benchmarks/; run from the repo root |
--from DEMO_FOLDER (repeatable: copy that folder's records in first) |
Every benchmark command also takes --dataset (default: the Chinook gold set)
and the same --config/--llm-config/--policies-config/--secrets-config/--vector-store
overrides as run. --llm takes a preset name, a .yaml path or NAME=PATH,
and a unique suffix will do: --llm mini-helpers finds gpt-5.4-mini-helpers.
Examples, from the demo folder:
nl2sql --env demo run "How many customers do we have, by country?"
nl2sql --env demo run --role viewer "Who are the top 5 customers by total spend?"   # refused
nl2sql --env demo run --no-exec "Which artist has the most albums?"                 # plan only
nl2sql --env demo benchmark --tier 2 --model gpt-5.4 --max-cost 5
nl2sql --env demo feedback stats
run exits 1 when the run ends with an ERROR or CRITICAL error (a refusal
included). More: Demo guide,
Debugging a Run,
Feedback and Signals,
Evaluation.
The nl2sql-api package serves the engine over HTTP with FastAPI. It builds one
NL2SQL engine at startup from the same env file and configs as the CLI.
pip install nl2sql-api
cd nl2sql-demo                               # the configs use relative paths
ENV=demo NL2SQL_API_ROLE=admin nl2sql-api --host 127.0.0.1 --port 8000
# or: ENV=demo NL2SQL_API_ROLE=admin uvicorn nl2sql_api.main:app --port 8000
Full interactive docs at http://localhost:8000/docs (Swagger UI), with ReDoc
at /redoc and the schema at /openapi.json. Browser access from other origins
is off unless listed in NL2SQL_API_CORS_ORIGINS.
The API does not authenticate callers itself, and it never takes the RBAC role from the request body. The role comes from one of these settings, first match wins:
| Setting | Role source |
|---|---|
NL2SQL_API_ROLE_HEADER=X-NL2SQL-Role |
A header set by a trusted proxy that authenticates the caller. Comma-separated values are several roles. |
NL2SQL_API_ROLE=admin |
One static role for every request. |
NL2SQL_API_TRUST_BODY_ROLE=true |
Dev only: user_context in the body. Any client can pick any role, so the server logs a warning at startup. |
With none of them, /api/v1/query answers HTTP 401.
| Method | Path | Purpose |
|---|---|---|
POST |
/api/v1/query |
Ask a question; returns the plan, checks, SQL, rows, answer, errors and usage |
GET |
/api/v1/health |
Liveness check |
GET |
/api/v1/ready |
Readiness check (does not yet check datasources, the LLM or the index) |
POST |
/api/v1/datasource |
Register a datasource in the running process |
GET |
/api/v1/datasource |
List registered datasource ids |
GET |
/api/v1/datasource/{datasource_id} |
Check that a datasource is registered |
DELETE |
/api/v1/datasource/{datasource_id} |
Not supported yet: always answers success: false |
POST |
/api/v1/llm |
Configure an LLM in the running process |
GET |
/api/v1/llm |
List configured LLMs |
GET |
/api/v1/llm/{llm_name} |
Get one configured LLM |
POST |
/api/v1/index/{datasource_id} |
Index one datasource's schema |
POST |
/api/v1/index-all |
Index every registered datasource |
DELETE |
/api/v1/index |
Clear the vector store |
GET |
/api/v1/index/status |
Index health: status, entries by type, embedding model and problems per datasource |
curl -X POST http://localhost:8000/api/v1/query \
  -H "Content-Type: application/json" \
  -d '{"natural_language": "How many customers are there?"}'
The response has status, sub_queries, final_answer, errors, warnings,
reasoning, timings, usage, artifact_refs, trace_id and trace_path.
Each sub-query carries id, intent, datasource_id, schema_version,
plan, validation, sql, rows, status, retry_count and plan_source.
rows is a capped sample with the true total; the full result set lives in
artifact storage, addressed by artifact_refs. A pipeline failure, a refusal
included, comes back as HTTP 200 with status: "error" and the reason in
errors. Reference: REST API.
from nl2sql import NL2SQL, UserContext

engine = NL2SQL(env="demo")          # loads .env.demo from the working directory
result = engine.run_query(
    "How many customers are there?",
    user_context=UserContext(roles=["admin"]),
)

print(result.status)                  # "success", "error", "plan_only", or "" if nothing ran
for sq in result.sub_queries:
    print(sq.sql)
    print([c.name for c in sq.validation if c.passed])
    print(sq.rows.rows[:5] if sq.rows else "plan only")
print(result.final_answer["summary"] if result.final_answer else result.errors)
Run it from the demo folder. run_query also takes datasource_id and
execute=False (plan and validate only). Pass a user_context with a role: with
none the call currently raises a validation error, and a role the policy does
not know is refused. QueryResult carries per sub-query the plan, checks, SQL,
a capped row sample with the true total, status and retry count, and per run
the status, errors, warnings, per-node timings, usage (LLM calls and tokens,
and cost when LLM_PRICES is set) and trace_path. Asking the same question
again reuses the validated plan from the plan cache (sq.plan_source == "cache"),
still validated for the caller's role.
NL2SQL also exposes engine.query, engine.datasource, engine.llm,
engine.indexing, engine.auth, engine.policy, engine.settings
and engine.benchmark, plus engine.get_schema(), engine.index_health(),
engine.inspect_retrieval() and engine.rebuild_index() — what the playground
runs on. Feedback is not on the facade; it is read through the CLI. See
the public facade and
examples/.
| File | What it holds |
|---|---|
configs/datasources.yaml |
Datasources and connections: PostgreSQL, MySQL, SQL Server, SQLite, DuckDB (Datasources) |
configs/llm.yaml |
A default agent and optional per-node agents (LLM) |
configs/policies.json |
Roles: allowed datasources and datasource.table entries (Policies) |
configs/secrets.yaml |
Secret providers for ${provider:key} references (Secrets) |
LLM providers. openai (default model gpt-5.4), anthropic (Claude,
pip install "nl2sql-engine[anthropic]", claude-opus-5 with
temperature: null), openrouter (OpenAI-compatible gateway, default
anthropic/claude-sonnet-4.5) and ollama (local; small models often cannot
fill the recursive plan schema). Those defaults are what nl2sql setup and
nl2sql demo write. Each of the five model-using steps can have its own
provider and model under agents: datasourceresolver, decomposer,
astplanner, refiner and answersynthesizer, plus indexing_enrichment
for optional schema descriptions during indexing.
Key environment variables (System configuration):
| Variable | Default | Purpose |
|---|---|---|
OPENAI_API_KEY, ANTHROPIC_API_KEY, OPENROUTER_API_KEY |
unset | Provider keys |
ENV (or APP_ENV) |
unset | Loads .env.<name>; what --env and NL2SQL(env=...) set |
ENV_FILE_PATH |
unset | Load this env file instead; wins over ENV |
DATASOURCE_CONFIG, LLM_CONFIG, POLICIES_CONFIG, SECRETS_CONFIG |
configs/... |
Config file paths |
VECTOR_STORE |
./chroma_db |
Vector store directory |
EMBEDDING_PROVIDER |
openai |
local runs an ONNX embedder with no key (the demo sets it) |
EMBEDDING_MODEL |
text-embedding-3-small |
Embedding model; changing it needs nl2sql index --full |
SCHEMA_STORE_PATH |
data/schema_store.db |
Schema snapshots, the plan cache and the feedback table |
RESULT_ARTIFACT_BACKEND, RESULT_ARTIFACT_BASE_URI |
local, ./artifacts |
Where the full result set goes |
GLOBAL_TIMEOUT_SEC |
60 | How long the caller waits for a run (the demo sets 300) |
SQL_AGENT_MAX_RETRIES |
3 | Refiner retries per sub-query |
SCHEMA_RETRIEVAL_FULL_SNAPSHOT_MAX_TABLES |
15 | Send the whole schema, skipping vector search, up to this many tables |
PLAN_CACHE_ENABLED |
true |
Reuse validated plans for repeated questions |
TRACE_MODE, TRACE_DIR |
on_failure, traces |
Run traces: every node's inputs, outputs, prompts and responses |
RBAC_REFUSAL_NAMES_TABLES |
false |
Name the denied table in the refusal message |
LLM_PRICES |
unset | Per-model prices, so usage reports cost |
FEEDBACK_ENABLED |
true |
Accept playground ratings |
- What reaches the LLM provider: the question; the schema the planner needs
(table and column names, types, keys, relationships, descriptions); sample
column values for tables the role may read; and the result rows, which
the answer writer summarises. With
TRACE_MODEon, run traces store prompts, responses and sample rows on disk. - RBAC is strict. A plan that touches a table the role may not read is refused before any SQL exists, never answered from the tables the role can see. Sample values and statistics of forbidden tables are stripped from the prompt and the trace. An unknown role grants nothing. There is no column masking and no row-level security.
- Read-only is a database setting, not something the executor checks. The
plan type only allows
SELECTand the generator only builds one, but the executor does not inspect the SQL. A SQLite datasource can be opened read-only at the driver level withoptions.read_only: true(SQLite'smode=roURI), and all three sample databases are; the write is then refused by SQLite itself. No other dialect opens read-only, so on PostgreSQL, MySQL, SQL Server or DuckDB, give the engine a read-only database user. - No authentication in the CLI, playground or REST API. The CLI and playground take the role from the caller. The REST API takes it from a trusted proxy header or a static setting, never from the body unless a dev flag is on; put your own auth in the proxy and derive the role from it.
GLOBAL_TIMEOUT_SECbounds how long the caller waits, not how long the work runs; the graph runs in-process with no sandbox.
Details: Security Model, Execution Isolation.
- Gold set: 43 Chinook questions (39 answerable, 4 deliberately not) with
expected results per role, including refusals. A question may carry reviewed
alt_gold_sqlalternatives, so a second correct way to answer it scores as correct; gold data is never edited to make a run pass. - Tier 1 (no key, runs in CI): the hand-written gold plans through the validator, generator and executor with a fake LLM, so a failure is a bug in code, not the model.
- Tier 2 (real model, costs money): end to end per config, with accuracy,
answerability precision and recall, cost, latency, determinism and answer
faithfulness (a deterministic check, no second model, that every number and
name in the written answer comes from the rows). Accuracy is scored twice:
strict, where the rows must match the gold answer exactly, and
lenient, which allows extra and reordered columns and date labels. Each
is published with a 95% Wilson interval, because 43 questions cannot separate
small differences. Stops before spend could pass
--max-cost.--baselinepairs each run's questions with the baseline's and fails when more than--max-regressions(default 2) flip from pass to fail, or when a smaller drop is significant by McNemar's exact test; the old flat-threshold--max-accuracy-dropgate still works if passed explicitly, but is deprecated in favor of--max-regressions. - Retrieval recall (no key): the share of each question's needed tables and columns that schema retrieval sends the planner.
- Feedback: playground ratings and guardrail rates via
nl2sql feedback stats;feedback export --gooddrafts new gold entries for review.
Recorded runs are published with nl2sql benchmark publish to the block above
and docs/benchmarks.md. Details:
Evaluation,
Feedback and Signals.
The engine is at 0.1.x. nl2sql-adapter-sdk, nl2sql-engine and
nl2sql-api share one version and are released together
(Releasing). Unreleased changes are on main;
see the changelog for what is released.
Known limitations:
- Every question needs an LLM; only indexing is key-free. The key-free demo answers nothing until you record answers or add a key.
- Small local models often fail to produce a valid plan.
- A question cannot span two databases: every sub-query is planned against one datasource, so the demo's three cannot be joined, however much their data lines up.
- There is no conversation: each question is answered on its own, with no memory of the last one, so "and by country?" is not a follow-up.
- Read-only is enforced by SQLite when a datasource asks for it, and by nothing
else (see above), so a database user that can only read is still the real
control.
max_bytesis not enforced;row_limitis, in the generated SQL. - The hosted demo's rate limits are best-effort: they live in one process, and the per-session cap hangs on a cookie the visitor can clear.
- The model's output is not reproducible; determinism is structural (fixed topology, validation before generation, plan cache) (Determinism).
- The S3 and ADLS result backends have not been verified against a real service.
- No distributed tracing: OpenTelemetry metrics only, off by default. Audit events are emitted only by the CLI.
- The REST API does not authenticate callers: it takes the role from a trusted
proxy header or a static setting.
run_querywithout auser_contextraises instead of refusing.
Roadmap: using the engine on your own database (bring-your-own-database setup
beyond the bundled demo databases) is planned. The setup wizard and the
adapters exist, but that path is not yet documented or supported end to end.
See CONTRIBUTING.md for local setup and test markers
(pytest -m "not integration" runs without a database or key).
CLAUDE.md is the short form of the rules a change has to keep —
package boundaries, no dialect outside an adapter, validation before
generation — and most of them are enforced, not just written down:
packages/nl2sql/tests/architecture/test_boundaries.py parses the tree and
fails with the rule's own name. The reasoning behind each is in
Invariants.
Repository layout: packages/nl2sql (engine, CLI, adapters),
packages/api (REST API), packages/adapter-sdk (adapter contract),
web/playground (the playground's React source), docs/ (MkDocs site),
benchmarks/ (recorded benchmark runs), examples/.
MIT licensed (LICENSE). The Chinook sample database and other third-party material: THIRD_PARTY_NOTICES.md.