


Probability calibration that doesn't flatten your scores.
Your classifier's probabilities are usually wrong — a model that says "80%" may be right 60% of the time. Isotonic regression is the standard fix, and it works, but it can pool distinct scores into the same fitted probability. Its prediction map interpolates between fitted knots but retains flat regions.
On the 2,000-point held-out set in the example below, isotonic regression turns 2,000 distinct scores into 82. Everything inside a step becomes indistinguishable — which matters as soon as you rank, threshold, or bucket the output.
calibre gives you calibration methods that retain much more of that ordering while correcting the probabilities.
pip install calibre           # core
pip install 'calibre[plots]'  # adds matplotlib for calibre.plots
Python 3.12+. Depends on numpy, scipy and scikit-learn. matplotlib is
optional and imported only when you use calibre.plots.
import numpy as np
from sklearn.model_selection import train_test_split

from calibre import CenteredIsotonicCalibrator, IsotonicCalibrator

# An overconfident model: true log-odds z, but the model reports 1.8 * z.
rng = np.random.default_rng(0)
z = rng.normal(0, 2, 4000)
y = (rng.random(4000) < 1 / (1 + np.exp(-z))).astype(float)
scores = 1 / (1 + np.exp(-1.8 * z))

# Always fit the calibrator on data the model did not train on.
s_fit, s_test, y_fit, y_test = train_test_split(
    scores, y, test_size=0.5, random_state=0
)

isotonic = IsotonicCalibrator().fit(s_fit, y_fit)
centered = CenteredIsotonicCalibrator().fit(s_fit, y_fit)

print("distinct values, isotonic:", len(np.unique(isotonic.transform(s_test))))
print("distinct values, calibre: ", len(np.unique(centered.transform(s_test))))
# > distinct values, isotonic: 82
# > distinct values, calibre:  1863
This example measures prediction granularity, not calibration quality or risk discrimination. More distinct values need not be more informative; compare proper scores and ranking on labels that neither fit has seen.
If you don't want to think about it: CenteredIsotonicCalibrator. It is
non-parametric, has nothing to tune, and preserves score ordering between pooled
isotonic blocks.
| You want | Use | Notes |
|---|---|---|
| A drop-in isotonic replacement, no tuning | CenteredIsotonicCalibrator |
Collapses isotonic's flat steps to points and interpolates. Linear-time after sorting. |
| A smooth curve, and you can afford cross-validation | SplineCalibrator |
Monotone spline; picks its own smoothing using the loss appropriate for its link. |
| A smooth curve with smoothing you control | SplineCalibrator |
Set alpha; also set n_knots to skip cross-validation. |
| Exactly scikit-learn's isotonic behavior | IsotonicCalibrator |
Thin wrapper, plus optional plateau diagnostics. |
| A fitted-value change bound you control | RelaxedPAVACalibrator |
Negative permits bounded drops; positive forces a step before clipping. |
| To allow small ranking violations if they fit better | NearlyIsotonicCalibrator |
lam trades monotonicity against fit. Not the one to reach for if you want resolution — see its docstring. |
| Experimental constraints near decision thresholds | CDIIsotonicCalibrator |
Research-grade; requires thresholds on the same probability-score scale and can permit bounded drops away from them. Validate proper scores and decision utility. |
Every calibrator follows the scikit-learn transformer API: .fit(scores, labels) and
.transform(scores), plus sample_weight where it is meaningful.
Every number below comes from the
benchmarks/
directory, whose results are
committed — python -m benchmarks.run reproduces them. This is the
overconfident design (a model reporting 1.8 * z for true log-odds z), thirty
seeds, scored on a held-out 40% that nothing was tuned on. Lower Brier is better;
ΔBrier is the improvement over leaving the model uncalibrated.
| Method | Brier | ΔBrier | smECE | Distinct values | Beats isotonic |
|---|---|---|---|---|---|
| Uncalibrated | 0.1604 | — | 0.0835 | 1594 | — |
IsotonicCalibrator |
0.1530 | +0.0073 | 0.0270 | 49 | baseline |
NearlyIsotonicCalibrator |
0.1531 | +0.0073 | 0.0270 | 52 | 7/30 |
CenteredIsotonicCalibrator |
0.1527 | +0.0076 | 0.0284 | 1514 | 25/30 |
SplineCalibrator |
0.1524 | +0.0080 | 0.0263 | 1595 | 28/30 |
| Logistic recalibration of log-odds | 0.1521 | +0.0082 | 0.0251 | 1599 | 26/30 |
| Temperature scaling (scalar optimization) | 0.1522 | +0.0082 | 0.0251 | 1599 | 26/30 |
Read three things off it honestly.
The Brier gains over isotonic are small. Centered isotonic and the spline keep around 1,500 distinct values instead of 49, at a Brier difference in the fourth decimal. Relaxed PAVA is not in this defaults-only table because its increment bound is deliberately required.
The parametric comparators have the lowest mean Brier scores in this design.
The harness fits logistic regression to log-odds and optimizes a scalar
log-temperature directly; it does not call CalibratedClassifierCV. Temperature
scaling also has the smallest error against the known probabilities. Here the
distortion is a pure temperature change, so the parametric family contains its
inverse. Include simple parametric alternatives when evaluating flexible methods.
smECE barely separates the methods, because it is a calibration measure and
resolution is not miscalibration. That is a reason to look at more than one number,
which is what calibration_report below is for.
The cost is computation: isotonic fits one model, while SplineCalibrator and
NearlyIsotonicCalibrator cross-validate multiple candidates. Runtime depends on calibration-set size, fold
count, and hardware; the benchmark records timings for its own runs.
nonmonotone is in the grid because monotone methods should lose there. They
don't: SplineCalibrator scores 0.2156 against Platt's 0.2224,
because the parametric methods cannot follow the dip either and give up more. And
on breast_cancer/logreg, not calibrating at all beats isotonic by 0.0013 with a
bootstrap interval clear of zero — the model was already close to calibrated and
the test sample is small, so pooling costs more than it buys.
This is the mistake that quietly ruins calibration. A model's scores on its own training data are already too good, so a calibrator fitted there learns the wrong correction. Use a held-out split, or out-of-fold predictions:
import numpy as np
from sklearn.datasets import make_classification
from sklearn.linear_model import LogisticRegression
from sklearn.model_selection import cross_val_predict, train_test_split

from calibre import CenteredIsotonicCalibrator

X, y = make_classification(n_samples=2000, n_features=10, random_state=0)
X_train, X_test, y_train, y_test = train_test_split(X, y, random_state=0)

model = LogisticRegression().fit(X_train, y_train)

# Out-of-fold predictions: every score comes from a model that did not see that row.
oof = cross_val_predict(
    LogisticRegression(), X_train, y_train, cv=5, method="predict_proba"
)[:, 1]

calibrator = CenteredIsotonicCalibrator().fit(oof, y_train)
calibrated = calibrator.transform(model.predict_proba(X_test)[:, 1])
print(
    f"{len(calibrated)} calibrated probabilities in "
    f"[{calibrated.min():.3f}, {calibrated.max():.3f}]"
)
# > 500 calibrated probabilities in [0.000, 1.000]RelaxedPAVACalibrator exposes the lower bound in its optimization problem as one
required signed parameter. Zero is ordinary isotonic regression, a negative value
permits bounded decreases, and a positive value requires adjacent fitted values to
differ. The package does not invent a default bound; choose it using held-out data
and a proper score.
Disable clipping when you need a positive bound to hold at the output boundaries:
import numpy as np

from calibre import RelaxedPAVACalibrator

rng = np.random.default_rng(0)
scores = np.sort(rng.random(500))
labels = (rng.random(500) < scores).astype(float)

cal = RelaxedPAVACalibrator(min_increment=1e-4, clip_output=False)
fitted = cal.fit_transform(scores, labels)

steps = np.diff(fitted)
print("strictly increasing:", bool(np.all(steps > 0)))
print("smallest step:      ", round(float(steps.min()), 6))
print(
    "range:              ",
    (round(float(fitted.min()), 4), round(float(fitted.max()), 4)),
)
# > strictly increasing: True
# > smallest step:       0.0001
# > range:               (-0.0011, 1.002)
Note clip_output=False. Forcing 500 points apart by 1e-4 needs at least 0.05 of
range, so the fit runs slightly outside [0, 1] at the ends. Leaving the default
clip_output=True would clamp those tails and flatten them back together — 31 of the
499 steps become exactly zero — which defeats the point. Either turn clipping off, as
here, or pick a min_increment small enough that the fit stays inside the unit
interval. Set min_increment=-0.02 to permit drops of at most two percentage points
between adjacent unique calibration scores; this can improve fit by reordering some
pairs, so validate it on held-out data.
import numpy as np

from calibre import CenteredIsotonicCalibrator

rng = np.random.default_rng(0)
scores = rng.random(300)
labels = (rng.random(300) < scores).astype(float)
weights = rng.uniform(0.5, 2.0, 300)  # e.g. inverse sampling probabilities

calibrator = CenteredIsotonicCalibrator().fit(scores, labels, sample_weight=weights)
print("weighted fit:", calibrator.transform(np.array([0.25, 0.75])).round(3))
# > weighted fit: [0.149 0.671]import numpy as np
from calibre.metrics import (
brier_score,
expected_calibration_error,
mean_calibration_error,
)
y_true = np.array([0, 0, 1, 1, 1, 0, 1, 1])
y_pred = np.array([0.1, 0.3, 0.6, 0.7, 0.9, 0.2, 0.8, 0.75])
print(f"Brier {brier_score(y_true, y_pred):.4f}") # lower is better
print(f"ECE {expected_calibration_error(y_true, y_pred):.4f}")
print(f"bias {mean_calibration_error(y_true, y_pred):.4f}")
# > Brier 0.0628
# > ECE 0.2313
# > bias 0.0813brier_score is a proper scoring rule and the one to optimize.
expected_calibration_error is the familiar binned ECE — useful, but sensitive to the
bin count and blind to resolution. mean_calibration_error is calibration in the
large, |mean(prediction) − base rate|, and accepts sample_weight for a weighted
evaluation population. Opposing errors can cancel, so it is not a standalone
calibration verdict.
Binned ECE is also biased upward: part of each bin's gap is sampling noise in the label mean rather than miscalibration, and the bias grows with the bin count — precisely when you wanted a finer picture. These estimators address the correction and bin-count problems separately:
import numpy as np

from calibre import debiased_calibration_error, sweep_calibration_error
from calibre.metrics import expected_calibration_error

rng = np.random.default_rng(0)
p = rng.uniform(0, 1, 4000)
y = rng.binomial(1, p).astype(float)  # calibrated by construction: true error is 0

print(f"plugin ECE  {expected_calibration_error(y, p, n_bins=15):.4f}")
print(f"debiased    {debiased_calibration_error(y, p, n_bins=15):.4f}")
print(f"sweep       {sweep_calibration_error(y, p):.4f}")
# > plugin ECE  0.0163
# > debiased    0.0000
# > sweep       0.0200
The true error here is zero, so the plugin's 0.0163 is entirely bias. Debiasing removes it. The sweep estimator does not, on this sample — it targets the bin-count problem rather than the within-bin bias, and the two are worth reaching for separately.
debiased_calibration_error subtracts the per-bin Bernoulli variance (Bröcker 2012;
Kumar et al. 2019) — verified against Kumar's reference implementation, exact on 18 of
24 cases. sweep_calibration_error chooses the bin count instead of fixing it, adding
bins while the calibration curve stays monotone and stopping when it doesn't (Roelofs
et al. 2022). Both use equal-mass bins, and neither ever splits a group of tied
predictions across a bin boundary.
Also available: maximum_calibration_error, root_mean_squared_calibration_error,
calibration_curve, correlation_metrics, unique_value_counts,
and tie_preservation_score.
calibration_report runs the whole battery and prints it, so you do not pick the
one metric that flatters the model:
import numpy as np

from calibre import calibration_report

rng = np.random.default_rng(0)
p = rng.uniform(0, 1, 2000)
y = rng.binomial(1, np.clip(p * 1.2, 0, 1)).astype(float)

print(calibration_report(y, p))
# > CalibrationReport  n=2,000  base rate 0.5760
# >
# >   Brier            0.1480
# >     = MCB          0.0110   (recalibration recovers this)
# >     - DSC          0.1072   (earned by the forecasts)
# >     + UNC          0.2442   (irreducible)
# >
# >   mean cal. error  0.0771   (mean forecast 0.4989)
# >   smECE            0.0769   (bandwidth 0.0771, chosen)
# >   debiased ECE     0.0873   (15 bins)
# >   plugin ECE       0.0931   (15 bins, uncorrected)
# >   sweep ECE        0.0904   (10 bins; assumes a monotone calibration curve)
# >
# >   prediction granularity  2,000 of 2,000 values unique (100.0%)
smooth_calibration_error is smECE, from Jarosław Błasiok and Preetum Nakkiran
(2024). It is the one
to reach for if you want a single number: unlike binned ECE it is consistent —
it goes to zero if and only if the forecaster is calibrated — and it has no bin
count for you to choose, which means no bin count for you to choose badly. calibre
pins it against their Apple relplot reference implementation across ten regimes
within a tight floating-point tolerance.
Every field is also available under its full name
(report.brier_score, report.smooth_calibration_error, …) rather than only
as text. Sweep ECE relies on a monotone population calibration curve; the report
labels that assumption because a strongly nonmonotone model can violate it.
Keep the existing fitting and probability diagnostics, then compare what acting on the predictions earns. Declare costs or capacity and evaluate aligned, held-out outcomes. This four-case illustration shows the payoff from retaining a score that separates cases tied by calibration:
from calibre import DecisionPolicy, DecisionTask, decision_report

result = decision_report(
    [0, 1, 0, 1],
    {"calibrated": [0.2, 0.8, 0.8, 0.8], "original": [0.1, 0.9, 0.5, 0.9]},
    task=DecisionTask(capacity=1),
    policies={
        "pooled": DecisionPolicy(prediction="calibrated", rule="rank"),
        "retained": DecisionPolicy(
            prediction="calibrated", rule="rank", tie_breaker="original"
        ),
    },
    reference="pooled",
    n_resamples=0,
)
print(round(result.differences["retained"], 4))
# > 0.0833
The difference is payoff per eligible case, averaged over boundary tie lotteries.
It is positive in this illustration; retaining an original score need not help
on new data. For known costs, use DecisionTask(benefit=1, cost=0.3) with
threshold policies and explicit act-all/none comparators.
select_decision_policy chooses on validation predictions;
evaluate_decision_policy evaluates that frozen choice on disjoint test cases.
The default paired bootstrap conditions on fitting and selection and assumes
independent cases. These additions do not change select_by_cv or
calibration_report. See the decision evaluation guide and its complete four-sample example in the
documentation for the data split,
tie rules, capacity convention, and uncertainty assumptions.
An evaluation metric computed on 2,000 rows is an estimate, and estimates deserve intervals when their sampling assumptions support them:
import numpy as np

from calibre import bootstrap_ci
from calibre.metrics import brier_score

rng = np.random.default_rng(0)
p = rng.uniform(0, 1, 2000)
y = rng.binomial(1, p).astype(float)  # calibrated by construction

ci = bootstrap_ci(brier_score, y, p, n_resamples=400, random_state=0)
print(f"Brier {ci['estimate']:.4f}  [{ci['lower']:.4f}, {ci['upper']:.4f}]")
# > Brier 0.1604  [0.1516, 0.1686]
bootstrap_ci uses SciPy's paired bootstrap and defaults to BCa; percentile and
basic intervals are also available. Use it on independent, held-out evaluation
rows and regular statistics such as a mean proper score. Ordinary row-bootstrap
intervals are not generally valid for calibration-error metrics at perfect
calibration, so
calibration_report(..., include_brier_interval=True) reports an interval only
for the Brier score.
Scoring a calibrator on the data it was fit to does not merely flatter it. For any isotonic-family calibrator it reports perfect calibration by construction, because the calibrator and the diagnostic are the same PAV projection and PAV is idempotent. The number is zero no matter how badly the model generalizes:
import numpy as np

from calibre import IsotonicCalibrator, cross_val_calibrate, score_decomposition

rng = np.random.default_rng(0)
scores = rng.uniform(0, 1, 1500)
labels = rng.binomial(1, scores).astype(float)

in_sample = IsotonicCalibrator().fit(scores, labels).transform(scores)
out_of_fold = cross_val_calibrate(IsotonicCalibrator(), scores, labels, cv=5)

print(
    f"MCB in-sample    {score_decomposition(labels, in_sample)['miscalibration']:.4f}"
)
print(
    f"MCB out-of-fold  {score_decomposition(labels, out_of_fold)['miscalibration']:.4f}"
)
# > MCB in-sample    0.0000
# > MCB out-of-fold  0.0030
cross_val_calibrate returns out-of-fold probabilities: each one comes from a model
that never saw that observation. Use those for any number you intend to believe.
Its shuffled folds assume independent, exchangeable observations; grouped,
repeated-measures, spatial, and temporal data require a design-aware workflow.
score_decomposition splits a proper score into the three things you actually want to
know, following the CORP approach of Dimitriadis, Gneiting & Jordan (2021). It uses
isotonic regression to find the bins, so there is no bin count to choose and none to
tune in your favor:
import numpy as np

from calibre import score_decomposition

rng = np.random.default_rng(0)
scores = rng.uniform(0, 1, 3000)
labels = rng.binomial(1, scores).astype(float)
overconfident = np.clip(1.6 * (scores - 0.5) + 0.5, 0, 1)

for name, x in (("honest", scores), ("overconfident", overconfident)):
    d = score_decomposition(labels, x)
    print(
        f"{name:14s} Brier {d['mean_score']:.4f} = "
        f"MCB {d['miscalibration']:.4f} - "
        f"DSC {d['discrimination']:.4f} + UNC {d['uncertainty']:.4f}"
    )
# > honest         Brier 0.1670 = MCB 0.0030 - DSC 0.0859 + UNC 0.2500
# > overconfident  Brier 0.1799 = MCB 0.0141 - DSC 0.0841 + UNC 0.2500
MCB is what recalibration would save you, DSC is what your scores buy over always
predicting the base rate, and UNC is the difficulty of the problem, which no
forecaster can change.
The split earns its keep here. Overconfidence cost 0.0129 of Brier score, and the
decomposition says where it went: MCB rose by 0.0111 — recoverable, just recalibrate —
while DSC fell by 0.0018, which is not recoverable. That small drop is the clipping at
0 and 1 collapsing 3000 distinct scores to 1841 and destroying ranking information with
them. A plain Brier score tells you the model got worse; this tells you which part you
can fix.
mean_score = MCB - DSC + UNC holds exactly, and both MCB and DSC are non-negative
by construction.
These numbers match R's reliabilitydiag across five regimes within a tight
floating-point tolerance in the test suite.
consistency_bands and confidence_bands add resampling-based uncertainty.
import numpy as np

from calibre import IsotonicCalibrator, run_plateau_diagnostics

rng = np.random.default_rng(0)
scores = np.sort(rng.random(400))
labels = (rng.random(400) < scores).astype(float)

calibrator = IsotonicCalibrator().fit(scores, labels)
report = run_plateau_diagnostics(scores, calibrator.transform(scores))

print(f"{report['n_plateaus']} plateaus")
for plateau in report["plateaus"][:3]:
    low, high = plateau["input_score_range"]
    print(
        f"  [{low:.3f}, {high:.3f}] -> {plateau['calibrated_value']:.3f} "
        f"({plateau['n_observations']} observations, {plateau['support']})"
    )
# > 16 plateaus
# >   [0.000, 0.006] -> 0.000 (3 observations, very_sparse)
# >   [0.010, 0.163] -> 0.017 (58 observations, adequate)
# >   [0.163, 0.280] -> 0.103 (39 observations, adequate)
Plateaus flagged very_sparse rest on few observations. report["warnings"] collects
those as readable messages.
There is no single best multiclass calibration method. There are two regimes with different winners, and picking wrong costs you roughly a factor of six. Measured against known true probabilities, 12 seeds, 5 classes:
| miscalibration | uncalibrated | temperature | per-class (CIR) |
|---|---|---|---|
| global | 0.0821 | 0.0025 | 0.0165 |
| class-dependent | 0.1043 | 0.0849 | 0.0173 |
Temperature scaling applies one parameter to every class, so when the distortion really is global it is exactly right — and when it differs by class it barely helps at all (0.1043 → 0.0849). So measure before you choose:
import numpy as np

from calibre import miscalibration_profile

rng = np.random.default_rng(0)
truth = rng.dirichlet(np.ones(5) * 0.7, size=4000)
labels = np.array([rng.choice(5, p=t) for t in truth])

# Each class distorted by a different exponent.
skewed = truth ** np.linspace(0.6, 2.4, 5)
scores = skewed / skewed.sum(axis=1, keepdims=True)

profile = miscalibration_profile(labels, scores)
print(f"spread {profile['relative_miscalibration_spread']:.2f}")
print(profile["interpretation"])
# > spread 0.96
# > Miscalibration is concentrated in classes 0, 4, 3 (spread 0.96). A one-parameter method applies the same correction to every class and cannot express this; per-class calibration is likely to help.
A spread near 0.13 means the miscalibration is even across classes and
TemperatureScaler will likely capture it; 0.4 and above means it is concentrated and a
one-parameter method cannot express the fix.
Also available: classwise_decomposition (the MCB/DSC/UNC split per class),
classwise_ece, top_label_ece, and classwise_reliability.
One cost worth knowing, because no standard metric shows it: TemperatureScaler never
changes the predicted class — accuracy is exactly preserved — but it does reorder
people within a class, at 49.6% of adjacent pairs in our measurements. If you rank
individuals by their probability of a given class, that reordering is real.
pip install 'calibre[plots]'matplotlib is an optional extra. Importing calibre pulls in nothing new without it, and a subprocess test enforces that.
The collapse barcode. One thin tick per distinct output value, one strip per method, drawn over the input range. The number of ticks is the number of distinct values, so the loss is not asserted — it is visible.
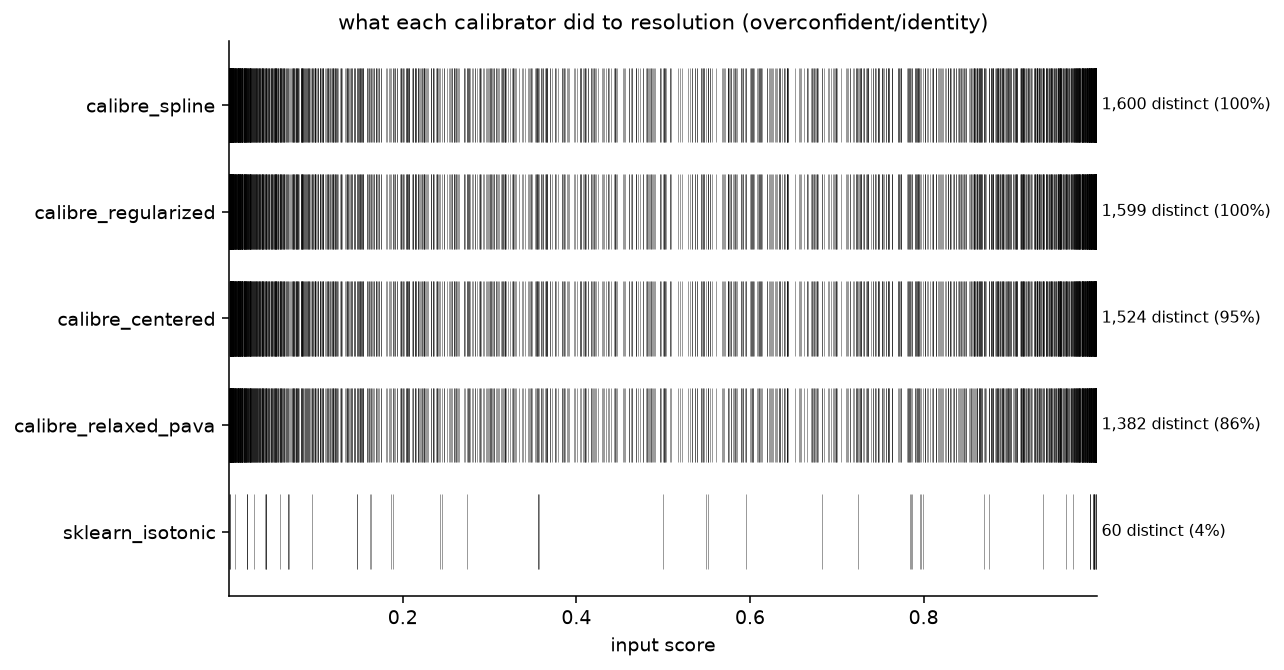
scikit-learn's isotonic strip is sparse enough to count by eye. The calibre strips are solid ink. Same data, same held-out Brier to the fourth decimal.
The frontier. The obvious objection to the barcode is that the extra values might be noise. If they were, the methods keeping them would sit higher on the score axis:
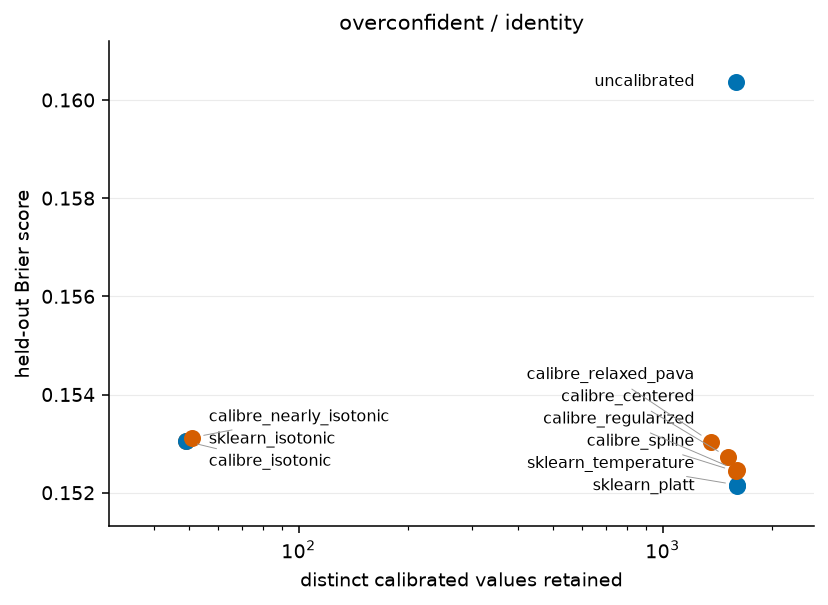
They do not. The frontier is flat: two clusters four decades apart in resolution, at the same height.
import matplotlib

matplotlib.use("Agg")  # not needed interactively
import numpy as np

from calibre import CenteredIsotonicCalibrator, IsotonicCalibrator
from calibre.plots import plot_resolution_loss

rng = np.random.default_rng(0)
scores = rng.uniform(0, 1, 2000)
labels = rng.binomial(1, scores).astype(float)

ax = plot_resolution_loss(
    {
        "isotonic": IsotonicCalibrator().fit_transform(scores, labels),
        "centered": CenteredIsotonicCalibrator().fit_transform(scores, labels),
    },
    input_scores=scores,
)
print("strips:", [t.get_text() for t in ax.get_yticklabels()])
# > strips: ['isotonic', 'centered']
Nine functions in all: plot_reliability_diagram (the CORP diagram, with
consistency or confidence bands), plot_score_decomposition, plot_mcb_dsc_plane,
plot_resolution_loss, plot_resolution_frontier, plot_calibrator_comparison,
plot_ece_bin_sensitivity, plot_miscalibration_profile and
plot_classwise_reliability.
Every one returns the Axes or Figure, so you keep full control of titles,
limits and saving. The palette is Okabe-Ito, which stays legible with any common
form of color blindness.
git clone https://github.com/finite-sample/calibre.git
cd calibre
uv sync --all-groups
uv run pytest
The monotone and isotonic estimators are checked against reference implementations in
R — isotone::gpava, Iso::pava, cir::cirPAVA, neariso and scam — via committed
fixtures in tests/fixtures/r/. See experiments/r_reference/gen_fixtures.R for how
those were produced. Issues and pull requests welcome; please open an issue first for
anything large.
MIT — see LICENSE.
The manuscript
describes the implemented methods, benchmark, and limitations. Run make paper
to build it; reproduction instructions are in ms/README.md.
@software{calibre,
  title  = {Calibre: Probability Calibration and Evaluation in Python},
  author = {Sood, Gaurav},
  url    = {https://github.com/finite-sample/calibre}
}- Oron & Flournoy (2017), "Centered Isotonic Regression: Point and Interval Estimation for Dose–Response Studies", Statistics in Biopharmaceutical Research 9(3).
- Tibshirani, Höfling & Tibshirani (2011), "Nearly-Isotonic Regression", Technometrics 53(1), 54–61.
- Ramsay (1988), "Monotone Regression Splines in Action", Statistical Science 3(4), 425–441.
- Pya & Wood (2015), "Shape constrained additive models", Statistics and Computing 25(3), 543–559.
- Eilers & Marx (1996), "Flexible smoothing with B-splines and penalties", Statistical Science 11(2), 89–121.
- Probability calibration in scikit-learn
- finite-sample/streamcal — Always‑On Probability Calibration via Multiplicative‑Weights. Comparison to Batch Platt & Isotonic
- finite-sample/optimal-classification-cutoffs — Cutoffs for max. multiclass F1-score, etc.
- finite-sample/rank-preserving-calibration — Rank preserving calibration of multiclass prob.
Powered by Adjacent