
SwarmBots is a GPU-vectorized multi-agent reinforcement-learning benchmark for simulated self-assembling modular robots. Policies control movement and physical connections: identical robots can move independently, join into load-bearing structures, and separate again during an episode.
SwarmBots supports studies of cooperative locomotion, exploration under partial observability, and payload transport with custom learners or the included training presets.
| Wall traversal | Finding a hidden opening |
|---|---|
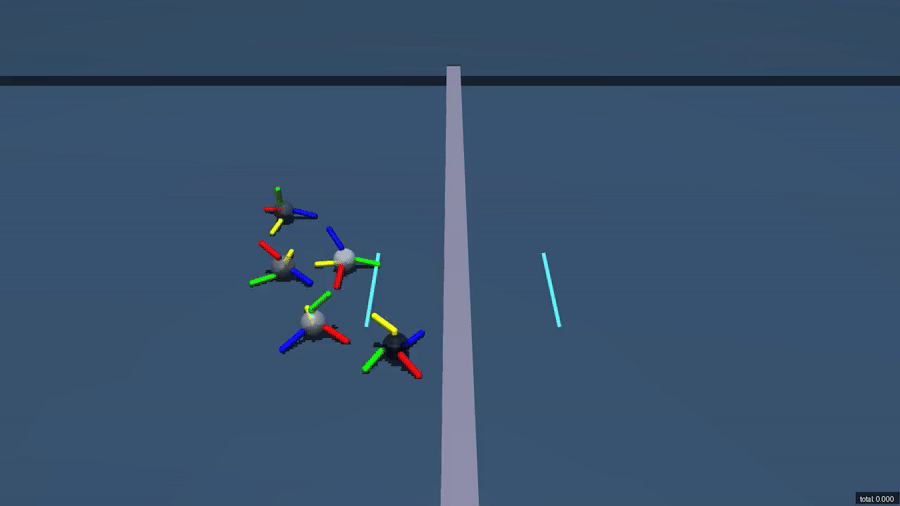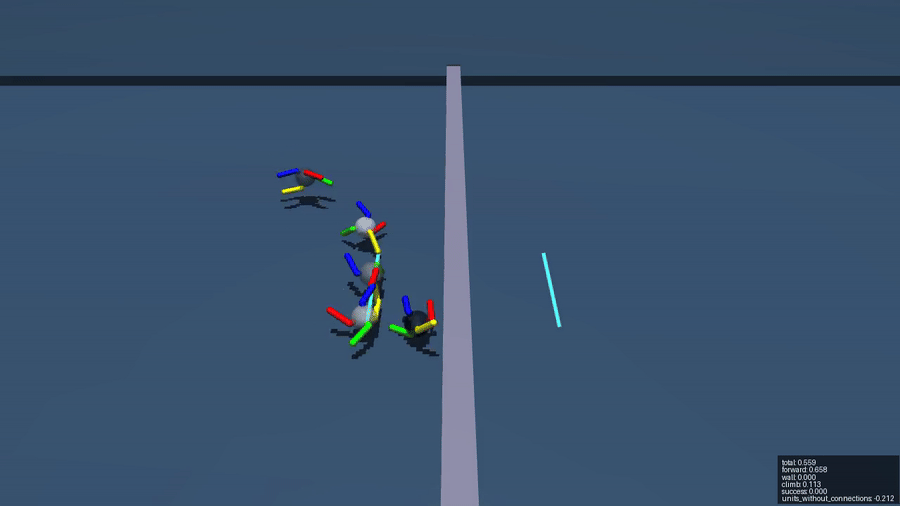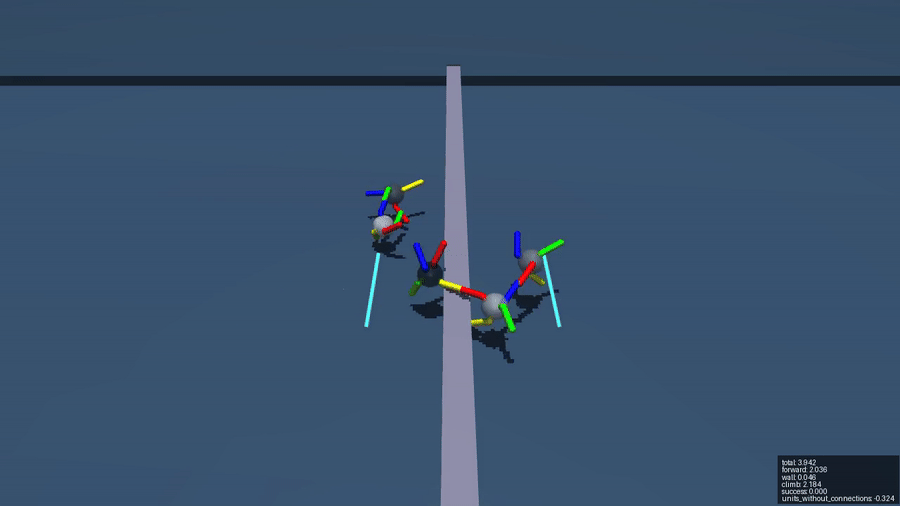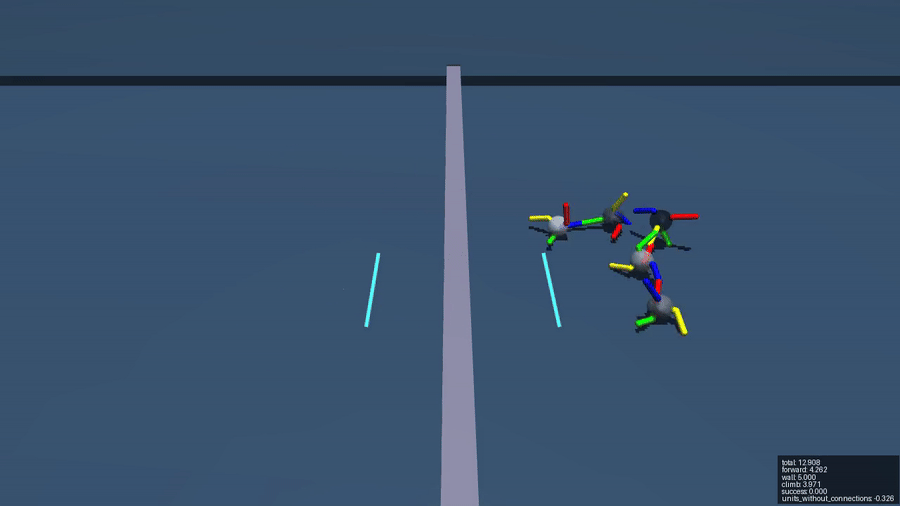 |
 |
SwarmBots is alpha and under active development. Task difficulty, rewards, and success conditions may change. Wall, PO-wall, and FindOpening scenarios are beta after extensive internal testing; other scenarios are alpha. Scenario maturity and versioning explains testing confidence and comparability across versions.
Python 3.11 or newer is required. An NVIDIA GPU with CUDA is strongly recommended for training and evaluation. CPU execution is available for small development runs.
For the runnable examples, install a source checkout with uv:
git clone https://github.com/brn-dev/swarm-bots.git
cd swarm-bots
uv sync --locked
On Windows and Linux, the checkout selects CUDA PyTorch and matching Triton dependencies. CUDA training and evaluation require the driver and compiler configuration described in GPU setup, because environments compile tensor operations by default. Policy compilation is a separate option.
To add the published alpha release to an existing project instead:
uv add "swarmbots==0.1.0a3"The guides here describe the current source checkout. The published 0.1.0a3 release differs in available presets and tools; its versioned documentation describes that release.
On Windows, the PyPI installation selects CPU-only PyTorch by default. Configure the application project's CUDA dependencies using published-package GPU setup. The checkout's CUDA configuration does not carry over to other projects.
From the repository root, list the tasks and check that simulation works:
.venv/bin/swarmbots list
.venv/bin/swarmbots smoke SwarmBots-WallEasy-v0 --device cuda --num-envs 2
On Windows:
.\.venv\Scripts\swarmbots.exe list
.\.venv\Scripts\swarmbots.exe smoke SwarmBots-WallEasy-v0 --device cuda --num-envs 2
A successful smoke test prints a JSON summary after stepping the environment. For a CPU check, use --device cpu. Add --compiled to check compiler setup too; the first compiled run can take longer.
The checkout includes a script that trains a policy, evaluates it, and records videos:
.venv/bin/python examples/train_policy.py SwarmBots-WallEasy-v0 --variant mappo__deepset_critic --run-dir runs/first-mappoOn Windows, replace .venv/bin/python with .\.venv\Scripts\python.exe.
By default, this trains on CUDA for one million environment transitions using 1,024 parallel worlds, evaluates one seed, and records two episodes. This is a workflow example; the training budget is not a claim of a solved task. Reduce --num-envs for training and --eval-envs for evaluation if GPU memory is tight, or change --total-timesteps to set the training budget.
This example saves to runs/first-mappo/, which must not already exist. Without --run-dir, each invocation creates a separate directory under runs/. Outputs include:
| Output | What it is for |
|---|---|
log.csv or its compressed counterpart |
Training progress and metrics |
run_metadata_*.json |
Configuration and runtime information |
models/*.pt |
Saved checkpoints for continuation or recording |
evaluation.json |
Evaluation episodes and summary scores |
videos/*.mp4 |
Qualitative inspection of the trained policy |
The runnable examples cover other presets and command options. The learning guide covers Python training and checkpoint continuation, while log plotting covers learning curves.
There are 15 registered tasks, with eight forming the core evaluation suite. Names below expand to SwarmBots-<name>-v0.
| Task family | Names | Challenge |
|---|---|---|
| Wall traversal | WallEasy, WallMedium, WallHard |
Whole-swarm traversal over a fixed wall |
| Partially observed walls | POWallEasy, POWallMedium, POWallHard |
Traversal over a randomized hidden wall |
| Exploration | FindOpening |
Hidden-passage discovery and traversal |
| Bridge traversal | Bridge |
Crossing a narrow movable bridge |
| Climbing and navigation | Climb, VerticalReach, MoveToGoal |
Reaching platform, elevated, or planar goals |
| Payload transport | PayloadPlane, PayloadStep, DualPayloadPlane, MultiPayloadGoal |
Cooperative object transport and delivery |
The scenario catalog lists exact IDs, observations, and success criteria. swarmbots describe <benchmark-id> prints a task summary.
Create a vector environment and apply a batch of actions:
import torch
from swarmbots import make_env

env = make_env("SwarmBots-WallEasy-v0", num_envs=2, device="cuda", seed=42)
try:
    observations, info = env.reset(seed=42)
    actions = {
        key: torch.zeros(space.shape, device=env.device)
        for key, space in env.action_space.items()
    }
    observations, rewards, terminations, truncations, info = env.step(actions)
finally:
    env.close()
Observations and actions are batched PyTorch tensors on the simulation device. Policies receive robot observations, public task information, and an active-agent mask. Actors may combine public observations across agents; privileged fields are reserved for training critics and diagnostics.
SwarmBots uses Gymnasium spaces and step conventions, with immediate autoreset when an episode ends. Libraries and wrappers expecting NumPy arrays need an adapter. The Python API guide explains tensor fields and episode handling. The standalone PPO example provides a complete PyTorch training loop independent of the included learning framework.
The evaluator accepts a callable policy(observations, episode_starts) returning actuators and connectors tensors. as_benchmark_policy(trainer) adapts an included learner to that interface:
from swarmbots import evaluate_policy
from swarmbots.learn import as_benchmark_policy

result = evaluate_policy(
    as_benchmark_policy(trainer, deterministic=True),
    "SwarmBots-WallEasy-v0",
    num_envs=256,
    num_episodes=256,
    seed=1000,
    device="cuda",
    action_mode="deterministic",
)
print(result.mean_return, result.success_rate)
This assumes trainer is the result of training from Python. Create a fresh adapter for each evaluation. For custom policies, configure evaluation mode, deterministic actions, and frozen normalization before evaluation; action_mode only records that configuration.
Protocol 0.1 defines comparable scores using unmodified tasks, seeds 1000–1004, and 256 first episodes per seed, for 1,280 episodes per task. Reports contain per-task return and success where defined, mean and standard deviation across seed-level results, and the package version, Git commit, checkpoint, and training budget. Evaluation samples the registered morphology pool; it does not test unseen morphologies.
swarmbots record <benchmark-id> --checkpoint <path> --variant <variant> records a saved checkpoint. The recording guide covers complete commands and video options.
The documentation guide links setup, training, custom-policy integration, evaluation, recording, and plotting workflows. The online diagram viewer shows model architectures without a local installation. Command-line tools also inspect policy sizes and generate architecture diagrams.
GitHub issues and email to Dominik Baron at dominik.b4ron@gmail.com are the channels for bug reports and task-design feedback. Reports are most useful with the task ID, version or commit, command, seed, and observed behavior.
Software citation metadata for the version used in an experiment is available in CITATION.cff.
The benchmark and policy designs are described in Dominik Baron (2026), SwarmBots: a GPU-accelerated multi-agent continuous control benchmark with transformer baselines, master's thesis, Johannes Kepler University Linz (published thesis, source and supplementary material).
The included learners adapt the original algorithms to a shared team objective. The method differences affect comparisons with original implementations. References and attribution maps learners to their papers and credits the scientific software. Reusable entries are available in references.bib.
SwarmBots is released under the Apache License 2.0.