+ This notebook demonstrates how to use a W&B Run's `config` property to save your training configuration:
""")
return
@@ -63,7 +52,7 @@ def _():
mo.md(r"""
## Authentication
- Enter your [W&B API key](https://wandb.ai/authorize) and, if needed, your team or entity. You can leave the key blank when this environment already has W&B credentials.
+ Run the following cell and privde your [Forge API key](https://wandb.ai/authorize) and your team name. Then select **Connect to W&B**.
""")
return
@@ -72,12 +61,12 @@ def _():
def _():
_api_key_input = mo.ui.text(
kind="password",
- label="W&B API key (optional)",
+ label="Forge API key (optional)",
placeholder="Paste a key or use cached credentials",
full_width=True,
)
_entity_input = mo.ui.text(
- label="W&B entity or team (optional)",
+ label="Forge team entity",
placeholder="Leave blank to use your default entity",
full_width=True,
)
@@ -133,168 +122,61 @@ def _():
mo.md(r"""
## What's a `config` for?
- Set [`wandb.config`](https://docs.wandb.ai/guides/track/config)
- once at the beginning of your script to save your training configuration: hyperparameters, input settings like dataset name or model type, and include any other independent variables or metadata for your experiments.
- """)
- return
-
+ Use [`wandb.Run.config`](https://docs.wandb.ai/guides/track/config) property
+ once at the beginning of your script to save your training configuration:
+ - hyperparameters
+ - input settings like dataset name or model type
+ - other independent variables or metadata for your experiments
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Why does that matter?
-
- This is useful for analyzing your experiments and reproducing your work in the future. You'll be able to group by `config` values in our web interface, comparing the settings of different runs and seeing how these affect the output.
-
- > Note that output metrics or dependent variables (like loss and accuracy) should be saved with `wandb.log` instead.
- """)
- return
+ This is useful for analyzing your experiments and reproducing your work in the future. You can [group](https://docs.coreweave.com/products/wandb/runs/grouping), [filter](https://docs.coreweave.com/products/wandb/runs/filter-runs), by `config` values using the W&B App or programmatically.
+ > Note that output metrics or dependent variables (like loss and accuracy) should be saved with [`wandb.Run.log()`](https://docs.coreweave.com/products/wandb/ref/python/experiments/run) instead.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
## How do I set up a `config`?
- """)
- return
+ Pass a dictionary of key-value pairs to the `config` paramater when you call [`wandb.init()`](https://docs.coreweave.com/products/wandb/ref/python/functions/init).
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Your `config` should be set just once at the beginning of your training experiment.
-
- But workflows differ, so we offer a number of ways to set up your config.
+ > Configurations are typically defined in the beginning of a training script. Machine learning workflows may vary, however, so you are not required to define a configuration at the beginning of your training script.
- Let's look at all the ways you can create and send the config dictionary to the Dashboard!
- """)
- return
+ ## Example: Define config when you initialize a run
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Setting the `config` at `init`ialization
-
- The best time to set the `config` values is when you call [`wandb.init`](https://docs.wandb.ai/guides/track/launch),
- by passing a dictionary as the `config` keyword argument.
+ The following cell passes an. configuration at the beginning of their experiment. It contains two to key-value pairs: `dataset:CelebA` and `type:baseline`.
""")
return
-@app.cell(hide_code=True)
-def _():
- create_config_run = mo.ui.run_button(
- label="Create the W&B config example run"
- )
- mo.vstack(
- [
- mo.md(
- "This creates one run in the `config_example` project. Use the "
- "controls below to apply each config update separately."
- ),
- create_config_run,
- ]
- )
- return (create_config_run,)
-
-
@app.cell
-def _(create_config_run, wandb_settings):
- mo.stop(
- not create_config_run.value,
- mo.callout(
- mo.md("Click the button above when you're ready to create the example run."),
- kind="info",
- ),
- )
+def _(wandb_settings):
+ config = {
+ "dataset": "CelebA",
+ "type": "baseline",
+ }
- if wandb.run is not None:
- wandb.finish()
- config_run = wandb.init(
+ with wandb.init(
project=wandb_settings["project"],
entity=wandb_settings["entity"],
- config={"dataset": "CelebA", "type": "baseline"},
- )
- config_run_url = config_run.url
- mo.callout(
- mo.md(f"Run created: [open it in W&B]({config_run_url})."),
- kind="success",
- )
- return (config_run,)
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Open the Run page from the link shown above and head to the [Overview tab](https://docs.wandb.ai/ref/app/pages/run-page#overview-tab)
- (top of the list of panels on the left-most side of the screen).
- You'll see a "Config" section that looks like this:
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
-
- """)
+ config=config,
+ ) as config_run:
+ config_run_url = config_run.url
return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- You give us a (possibly nested) dictionary as your `config`, and we'll flatten the names using dots in our backend.
+ The previous cell returns a link to [run's](https://docs.coreweave.com/products/wandb/runs) **Overview** page in the W&B App UI.
- > _Side Note_: We recommend that you avoid using dots in your config variable names, and use a dash or underscore instead. Once you've created your `config` dictionary, if your script accesses `wandb.config` keys below the root, use the dictionary access syntax, `["key"]["foo"]`, instead of the attribute access syntax, `config.key.foo`.
+ Select the link and navigate to the **Config** section. If you ran the previous cell as is, it should look similar to the following:
""")
return
-@app.cell(hide_code=True)
-def _():
- add_config_parameters = mo.ui.run_button(
- label="Add parameters to the W&B config"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Adding to the `config` by hand
- You can add more parameters to the `config` later if you want:
- """),
- add_config_parameters,
- ]
- )
- return (add_config_parameters,)
-
-
-@app.cell
-def _(add_config_parameters, config_run):
- mo.stop(
- not add_config_parameters.value,
- mo.callout(
- mo.md(
- "Click the button above to add `epochs` and `batch_size` to "
- "this run's config."
- ),
- kind="info",
- ),
- )
-
- config_run.config.epochs = 4
- config_run.config["batch_size"] = 32
-
- manual_config_update = True
- dict(config_run.config)
- return
-
-
@app.cell(hide_code=True)
def _():
mo.md(r"""
- Now, your Config section on the dashboard has been updated:
+
""")
return
@@ -302,218 +184,56 @@ def _():
@app.cell(hide_code=True)
def _():
mo.md(r"""
-
+ > Use dashes (-) or underscores (_) instead of periods (.) in your config variable names. For more information, see [Configure experiments](https://docs.coreweave.com/products/wandb/track/config).
""")
return
@app.cell(hide_code=True)
def _():
- add_argparse_parameters = mo.ui.run_button(
- label="Add argparse parameters to the W&B config"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Adding to the `config` with `argparse`
-
- `config` is a dictionary-like object, and it can be built from lots of dictionary-like objects.
-
- For example, you can pass in the arguments object produced by `argparse`.
- [`argparse`](https://docs.python.org/3/library/argparse.html), short for `arg`ument `parse`r, is a standard library module in Python 3.2 and above that makes it easy to write scripts that take advantage of all the flexibility and power of command line arguments. And it's Pythonic!
-
- This is especially convenient for tracking results from scripts that are launched from the command line.
- """),
- add_argparse_parameters,
- ]
- )
- return (add_argparse_parameters,)
+ mo.md(r"""
+ ## Example: Update an existing config
+ Use the [W&B Public API](https://docs.coreweave.com/products/wandb/ref/python/public-api) to update a completed run’s config.
+ You must provide the API with your team entity, the name of the project the run was logged to, and the [run’s ID](https://docs.coreweave.com/products/wandb/runs/run-identifiers#run-id).
-@app.cell
-def _(add_argparse_parameters, config_run):
- mo.stop(
- not add_argparse_parameters.value,
- mo.callout(
- mo.md("Click the button above to add the parsed arguments to this run's config."),
- kind="info",
- ),
- )
- parser = argparse.ArgumentParser()
- parser.add_argument('-b', '--batch_per_gpu', type=int, default=8,
- help='input batch size for training (default: 8)')
- parser.add_argument('-wd', '--weight_decay', type=float, default=0.1,
- help='weight decay (default: 0.1)')
+ ```
+ wandb: setting up run
+ ```
- args = parser.parse_args(args=[])
- config_run.config.update(args)
- return
+ This is the run's ID. Copy it and replace "run_id" in the following cell.
+ > You can also find a [run's ID programmatically or with the W&B App](https://docs.coreweave.com/products/wandb/runs/run-identifiers#find-a-run%E2%80%99s-id).
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Here's the updated Config panel:
+ The following cell adds a new config value (`bar`) to your existing run object.
""")
return
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
-
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- update_config_with_api = mo.ui.run_button(
- label="Update the W&B config with the Public API"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Updating the `config` with the API
-
- What if your run has finished, but you realized you forgot to log something?
-
- Never fear, you can always use the
- [public API](https://docs.wandb.ai/ref/python/public-api)
- to update your `config`
- (or anything else about your run!)
- at any time. You just need to know the details of the `run` you want to update.
- """),
- update_config_with_api,
- ]
- )
- return (update_config_with_api,)
-
-
@app.cell
-def _(config_run, update_config_with_api):
- mo.stop(
- not update_config_with_api.value,
- mo.callout(
- mo.md("Click the button above to add `bar` through the W&B Public API."),
- kind="info",
- ),
- )
+def _(wandb_settings):
+ run_id = "iomdo1ui" # replace with the run ID you want to update
api = wandb.Api()
+ api_run = api.run(f"{wandb_settings["entity"]}/{wandb_settings["project"]}/{run_id}")
- # pulling the relevant info automatically from the run object
- # this can also be found on the website
- username = config_run.entity
- project = config_run.project
- run_id = config_run.id
- api_run = api.run(f"{username}/{project}/{run_id}")
- api_run.config["bar"] = 32
+ api_run.config["epochs"] = 4
+ api_run.config['batch_size'] = 32
api_run.update()
return
-@app.cell
-def _():
- mo.md(r"""
- Here's what the final Config panel looks like:
- """)
- return
-
-
@app.cell(hide_code=True)
def _():
mo.md(r"""
-
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Using `config` for great good!
- The `config` parameters are useful for performing grouping, filtering, and aggregating on your experiments and their results.
-
- ### The examples below come from the project [here](https://wandb.ai/wandb/DistHyperOpt).
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Filtering Runs
- Filter tab allows you to display the runs that quality one or more conditions. These conditions can be formed by applying relational operators to any of the parameters logged in the `config` file.
-
- [Our example project](https://wandb.ai/wandb/DistHyperOpt) compares various hyper-parameter tuning methods and has more than 80 runs. Each run has a "Job Type" logged in the `config` which corresponds
-
- Let's say you want to visualize only the ones that are generated by a particular tuning algorithm, like Population Based Traing (`pbt`). You can do that by applying a filter on "Job Type".
-
- Run the cell below to see this in action!
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.Html(r"""
-
-
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Grouping Runs
- You can group your experiments in the dashboard of your project based on a particular column from `config`. A common use case for this would be grouping sub-experiments within a larger project.
-
- Our runs are grouped based on "Job Type". The Group tab is located next to the Filter Tab. You can group your runs by any parameter present in the config.
-
- 
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Parallel Coordinates Chart
-
- Often, the main thing we want to do with a group of Runs is make comparisons.
-
- The W&B Dashboard includes a Chart type for exactly this purpose:
- the Parallel Coordinates chart.
+ ## Next steps:
- A Parallel Coordinates chart represents each Run in the group as a line.
- This line passes through as many of the `config` values
- or logged metrics as you like,
- and is colored by its value on a single metric.
- This lets you take in, at a glance,
- which hyperparameter configurations were most and least successful.
- See the example below.
+ There are more ways to create, update, and mange config values for your experiments. Read the [Configure experiments documentation](https://docs.coreweave.com/products/wandb/track/config) to learn more.
- Head to a [group of Runs in this project](https://wandb.ai/wandb/DistHyperOpt/groups/dcgan_train)
- and build a Parallel Coordinates chart like the one pictured below
- by
- 1. clicking the + sign in the top-right corner, aligned with "Charts",
- 2. selecting "Parallel Coordinates" from the available Charts, and
- 3. adding the columns in the image, in order.
- 
+ For a live demo, explore this example [CoreWeave Project](https://wandb.ai/wandb/DistHyperOpt) to experiment with.
""")
return
From ccc971e53716e9e21b35277d1aa7f015428ddbd8 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Fri, 2 Oct 2026 16:55:24 -0700
Subject: [PATCH 02/48] update hugging face example
---
.../huggingface-wandb/huggingface_wandb.py | 233 +++++++-----------
1 file changed, 91 insertions(+), 142 deletions(-)
diff --git a/marimo/convert/huggingface-wandb/huggingface_wandb.py b/marimo/convert/huggingface-wandb/huggingface_wandb.py
index 7c13e88c..47facd69 100644
--- a/marimo/convert/huggingface-wandb/huggingface_wandb.py
+++ b/marimo/convert/huggingface-wandb/huggingface_wandb.py
@@ -4,6 +4,10 @@
# "datasets",
# "evaluate",
# "fsspec[http]==2026.6.0",
+# "marimo",
+# "scikit-learn==1.9.1",
+# "scipy==1.18.1",
+# "torch==2.14.1",
# "transformers @ git+https://github.com/huggingface/transformers",
# "wandb==0.29.0",
# ]
@@ -11,7 +15,7 @@
import marimo
-__generated_with = "0.24.0"
+__generated_with = "0.25.1"
app = marimo.App(auto_download=["html"])
with app.setup:
@@ -24,6 +28,8 @@
import torch
import wandb
import fsspec
+ import sklearn
+ import scipy
# Optional: log both gradients and parameters
os.environ['WANDB_WATCH'] = 'all'
@@ -32,95 +38,27 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
- # Hugging Face + W&B
+ # Hugging Face + Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/huggingface-wandb/huggingface_wandb.py/server)
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Visualize your [Hugging Face](https://github.com/huggingface/transformers) model's performance quickly with a seamless [W&B](https://wandb.ai/site) integration.
-
- Compare hyperparameters, output metrics, and system stats like GPU utilization across your models.
-
-
- """)
- return
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
-
- ## Why should I use W&B?
-
- Use [Weights & Biases](https://wandb.com) for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-
-
- - **Unified dashboard**: Central repository for all your model metrics and predictions
- - **Lightweight**: No code changes required to integrate with Hugging Face
- - **Accessible**: Free for individuals and academic teams
- - **Secure**: All projects are private by default
- - **Trusted**: Used by machine learning teams at OpenAI, Toyota, Lyft and more
-
- Think of W&B like GitHub for machine learning models— save machine learning experiments to your private, hosted dashboard. Experiment quickly with the confidence that all the versions of your models are saved for you, no matter where you're running your scripts.
-
- W&B lightweight integrations works with any Python script, and all you need to do is sign up for a free W&B account to start tracking and visualizing your models.
- """)
- return
+ Fine-tune a BERT model for sentence-pair classification and use the W&B integration for Hugging Face Transformers to track the experiment.
+ This tutorial uses the Microsoft Research Paraphrase Corpus (MRPC), which contains pairs of sentences labeled according to whether they have the same meaning. MRPC is one of the tasks in the General Language Understanding Evaluation (GLUE) benchmark.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Getting started
+ The tutorial uses:
- In this tutorial, we work with the Hugging Face and Weights & Biases libraries, and the GLUE dataset and training script.
- [Hugging Face Transformers](https://github.com/huggingface/transformers): Natural language models and datasets
- [Weights & Biases](https://docs.wandb.com/): Experiment tracking and visualization
- - [GLUE dataset](https://gluebenchmark.com/): A language understanding benchmark dataset
- - [GLUE script](https://github.com/huggingface/transformers/blob/master/examples/run_glue.py): Model training script for sequence classification
- """)
- return
-
-
-@app.cell
-def _():
- run_glue_url = (
- "https://raw.githubusercontent.com/huggingface/transformers/"
- "refs/heads/main/examples/pytorch/text-classification/run_glue.py"
- )
- run_glue_path = "run_glue.py"
-
- with fsspec.open(run_glue_url, "rb") as _source:
- with open(run_glue_path, "wb") as _destination:
- _destination.write(_source.read())
- return (run_glue_path,)
+ - [GLUE](https://gluebenchmark.com/): A benchmark for evaluating language-understanding models
+ - [`run_glue.py`](https://github.com/huggingface/transformers/blob/main/examples/pytorch/text-classification/run_glue.py): A Hugging Face script for training sequence-classification models
+
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- In the Hugging Face Transformers repo, we've instrumented the Trainer to automatically log training and evaluation metrics to W&B at each logging step.
-
- Here's an in depth look at how the integration works: [Hugging Face + W&B Report](https://app.wandb.ai/jxmorris12/huggingface-demo/reports/Train-a-model-with-Hugging-Face-and-Weights-%26-Biases--VmlldzoxMDE2MTU).
+ See the accompanying [Hugging Face + W&B Report](https://app.wandb.ai/jxmorris12/huggingface-demo/reports/Train-a-model-with-Hugging-Face-and-Weights-%26-Biases--VmlldzoxMDE2MTU).
""")
return
@@ -130,7 +68,7 @@ def _():
mo.md(r"""
## Authentication
- Enter your [W&B API key](https://wandb.ai/authorize) and, if needed, your team or entity. You can leave the key blank when this environment already has W&B credentials.
+ Connect the notebook to W&B so the Hugging Face Trainer can record the experiment. Enter your [Forge API key](https://wandb.ai/authorize) and optional team name, then select **Connect to Weights & Biases**. If you omit the team, W&B uses your default entity.
""")
return
@@ -139,19 +77,19 @@ def _():
def _():
_api_key_input = mo.ui.text(
kind="password",
- label="W&B API key (optional)",
+ label="Forge API key",
placeholder="Paste a key or use cached credentials",
full_width=True,
)
_entity_input = mo.ui.text(
- label="W&B entity or team (optional)",
+ label="Forge team name",
placeholder="Leave blank to use your default entity",
full_width=True,
)
wandb_login_form = (
mo.md("{api_key}\n\n{entity}")
.batch(api_key=_api_key_input, entity=_entity_input)
- .form(submit_button_label="Connect to W&B", bordered=True)
+ .form(submit_button_label="Connect to Weights & Biases", bordered=True)
)
wandb_login_form
return (wandb_login_form,)
@@ -201,16 +139,33 @@ def _(wandb_login_form):
@app.cell(hide_code=True)
def _():
mo.md(r"""
- Optionally, we can set environment variables to customize W&B logging. See [documentation](https://docs.wandb.com/library/integrations/huggingface).
+ ## Download script
+
+ Download Hugging Face's `run_glue.py` script to the notebook environment. The script loads a GLUE task, fine-tunes a sequence-classification model, and evaluates the trained model.
""")
return
+@app.cell
+def _():
+ run_glue_url = (
+ "https://raw.githubusercontent.com/huggingface/transformers/"
+ "refs/heads/main/examples/pytorch/text-classification/run_glue.py"
+ )
+ run_glue_path = "run_glue.py"
+
+ with fsspec.open(run_glue_url, "rb") as _source:
+ with open(run_glue_path, "wb") as _destination:
+ _destination.write(_source.read())
+ return (run_glue_path,)
+
+
@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train the model
- Next, call the downloaded training script [run_glue.py](https://huggingface.co/transformers/examples.html#glue) and see training automatically get tracked to the Weights & Biases dashboard. This script fine-tunes BERT on the Microsoft Research Paraphrase Corpus— pairs of sentences with human annotations indicating whether they are semantically equivalent.
+
+ Fine-tune `bert-base-uncased` to determine whether two sentences have the same meaning. Before starting the training process, the notebook checks for a GPU and prepares the W&B run configuration.
""")
return
@@ -242,6 +197,18 @@ def _():
return (gpu_available,)
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ### Configure the training run
+
+ The notebook runs `run_glue.py` as a separate Python process. Because that process cannot access this notebook's Python variables directly, the following cell passes the W&B project, team, and run ID through environment variables.
+
+ The cell also selects MRPC as the GLUE task and constructs the run URL. It prepares the run configuration but does not create the W&B run. The Hugging Face Trainer creates the run when logging begins.
+ """)
+ return
+
+
@app.cell
def _(wandb_settings):
task_name = "MRPC"
@@ -266,35 +233,46 @@ def _(wandb_settings):
return run_environment, task_name, wandb_run_url
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ### Start training
+
+ Launch the downloaded training script with the model, task, and training options shown below.
+
+ The `--report_to wandb` option enables the Trainer's built-in W&B integration. The command waits for training and evaluation to finish, saves the model output in temporary notebook storage, and reports an error if the script fails.
+ """)
+ return
+
+
@app.cell
def _(gpu_available, run_environment, run_glue_path, task_name):
mo.stop(not gpu_available)
+ training_command = [
+ sys.executable,
+ run_glue_path,
+
+ # Model and task
+ "--model_name_or_path", "bert-base-uncased",
+ "--task_name", task_name,
+ "--do_train",
+ "--do_eval",
+
+ # Training configuration
+ "--max_seq_length", "256",
+ "--per_device_train_batch_size", "32",
+ "--learning_rate", "2e-4",
+ "--num_train_epochs", "3",
+ "--logging_steps", "50",
+
+ # Output and experiment tracking
+ "--output_dir", f"/tmp/{task_name}/",
+ "--report_to", "wandb",
+ ]
+
subprocess.run(
- [
- sys.executable,
- run_glue_path,
- "--model_name_or_path",
- "bert-base-uncased",
- "--task_name",
- task_name,
- "--do_train",
- "--do_eval",
- "--max_seq_length",
- "256",
- "--per_device_train_batch_size",
- "32",
- "--learning_rate",
- "2e-4",
- "--num_train_epochs",
- "3",
- "--output_dir",
- f"/tmp/{task_name}/",
- "--report_to",
- "wandb",
- "--logging_steps",
- "50",
- ],
+ training_command,
env=run_environment,
check=True,
)
@@ -304,44 +282,15 @@ def _(gpu_available, run_environment, run_glue_path, task_name):
@app.cell(hide_code=True)
def _(wandb_run_url):
mo.md(f"""
- ## Visualize results in dashboard
-
- [**Open this training run in W&B**]({wandb_run_url})
-
- Click the link above, or go to [wandb.ai](https://app.wandb.ai) to see your results stream in live. The link to see your run in the browser will appear after all the dependencies are loaded — look for the following output: "**wandb**: View run at [URL to your unique run]"
+ ## View the results
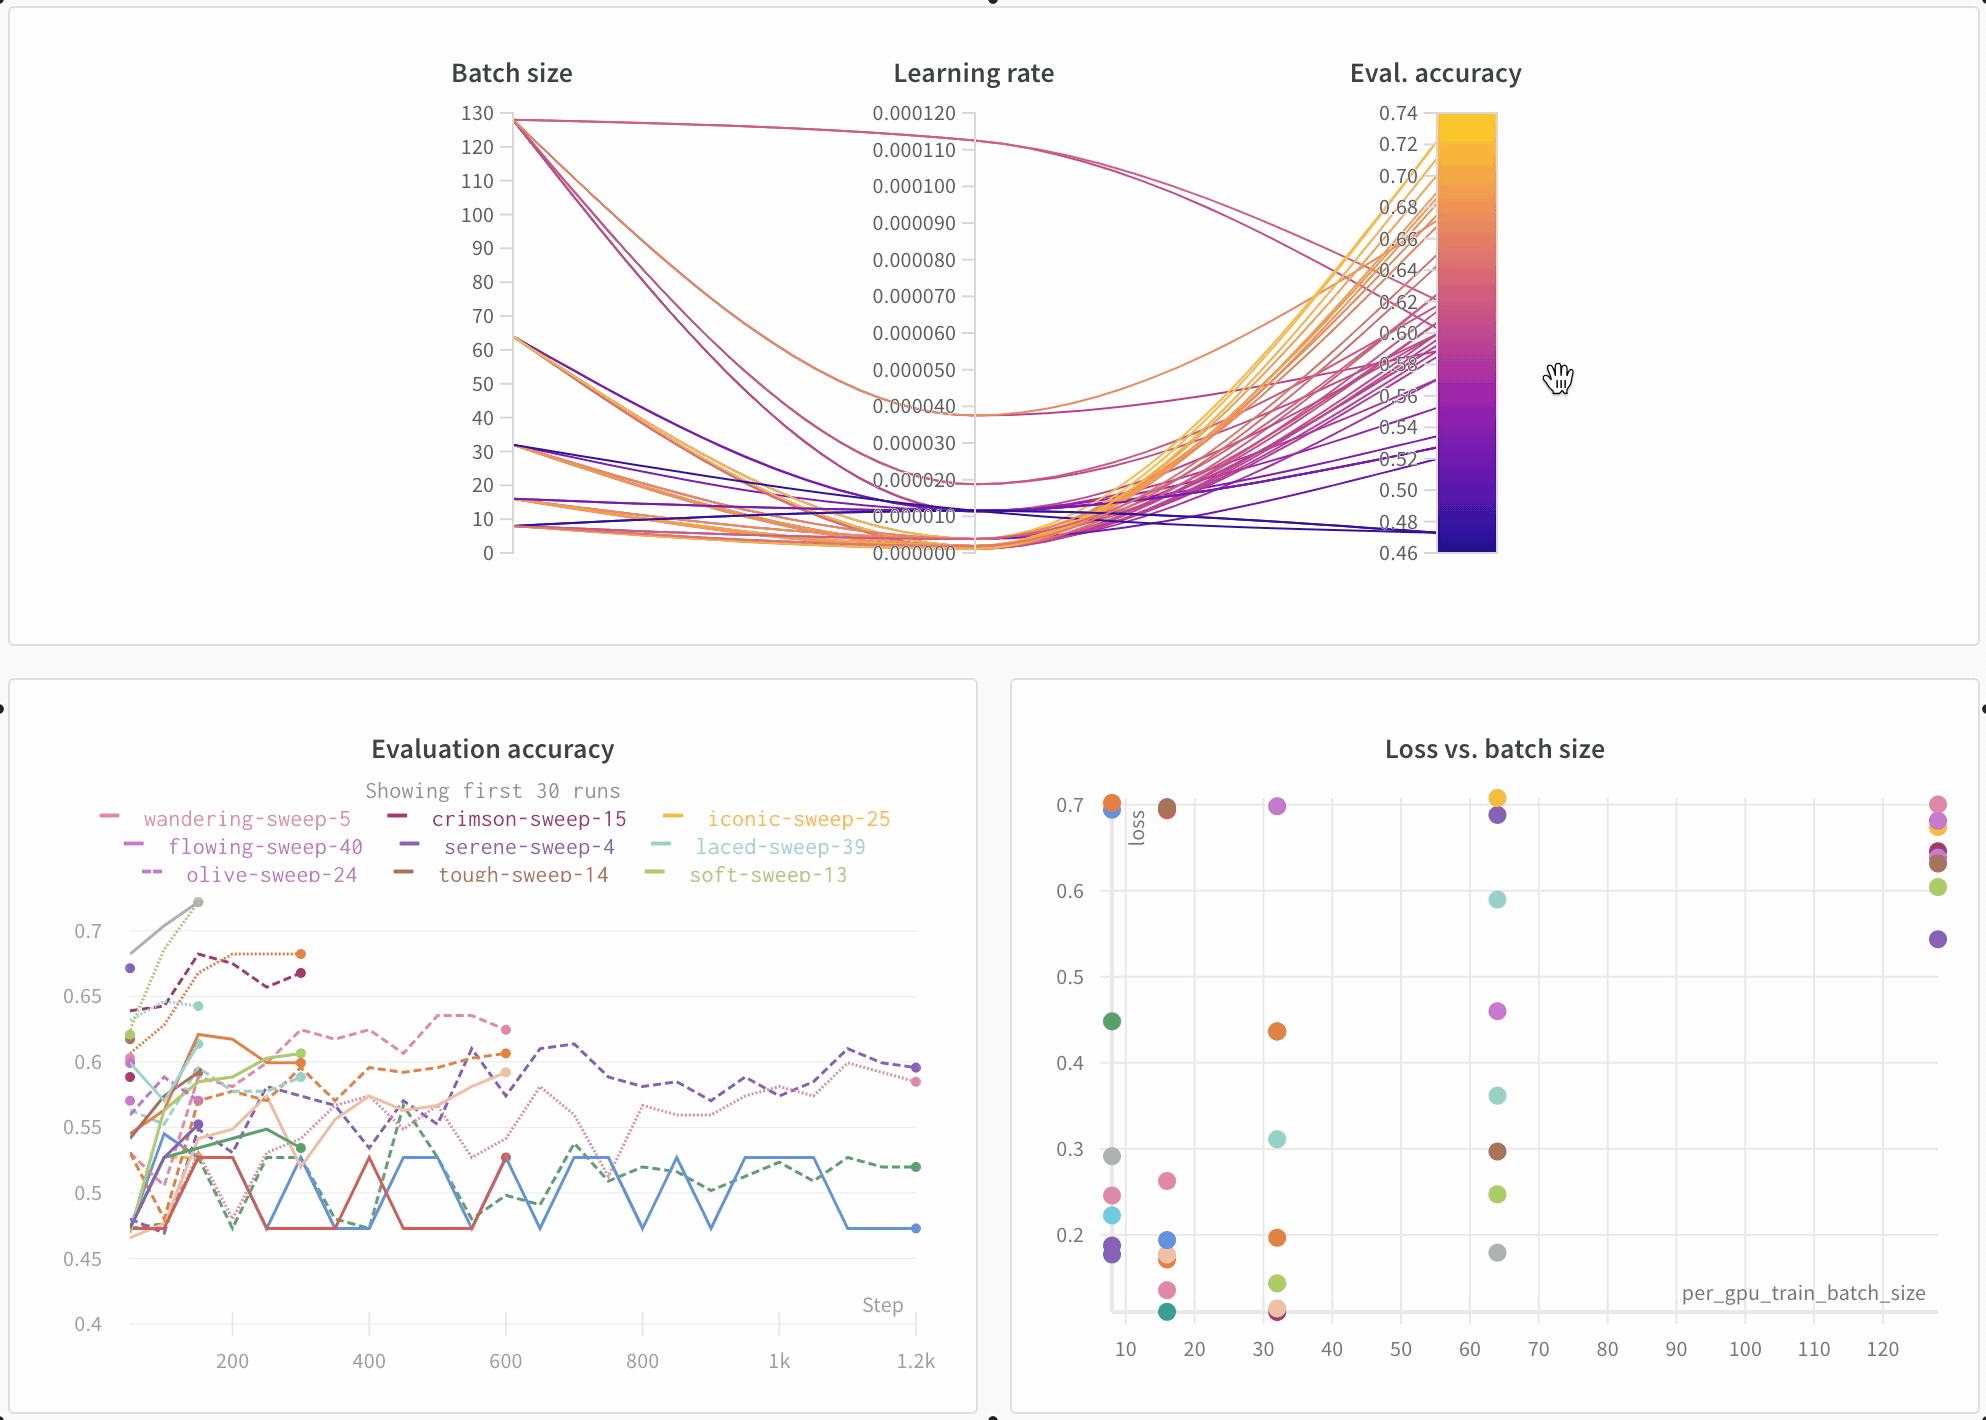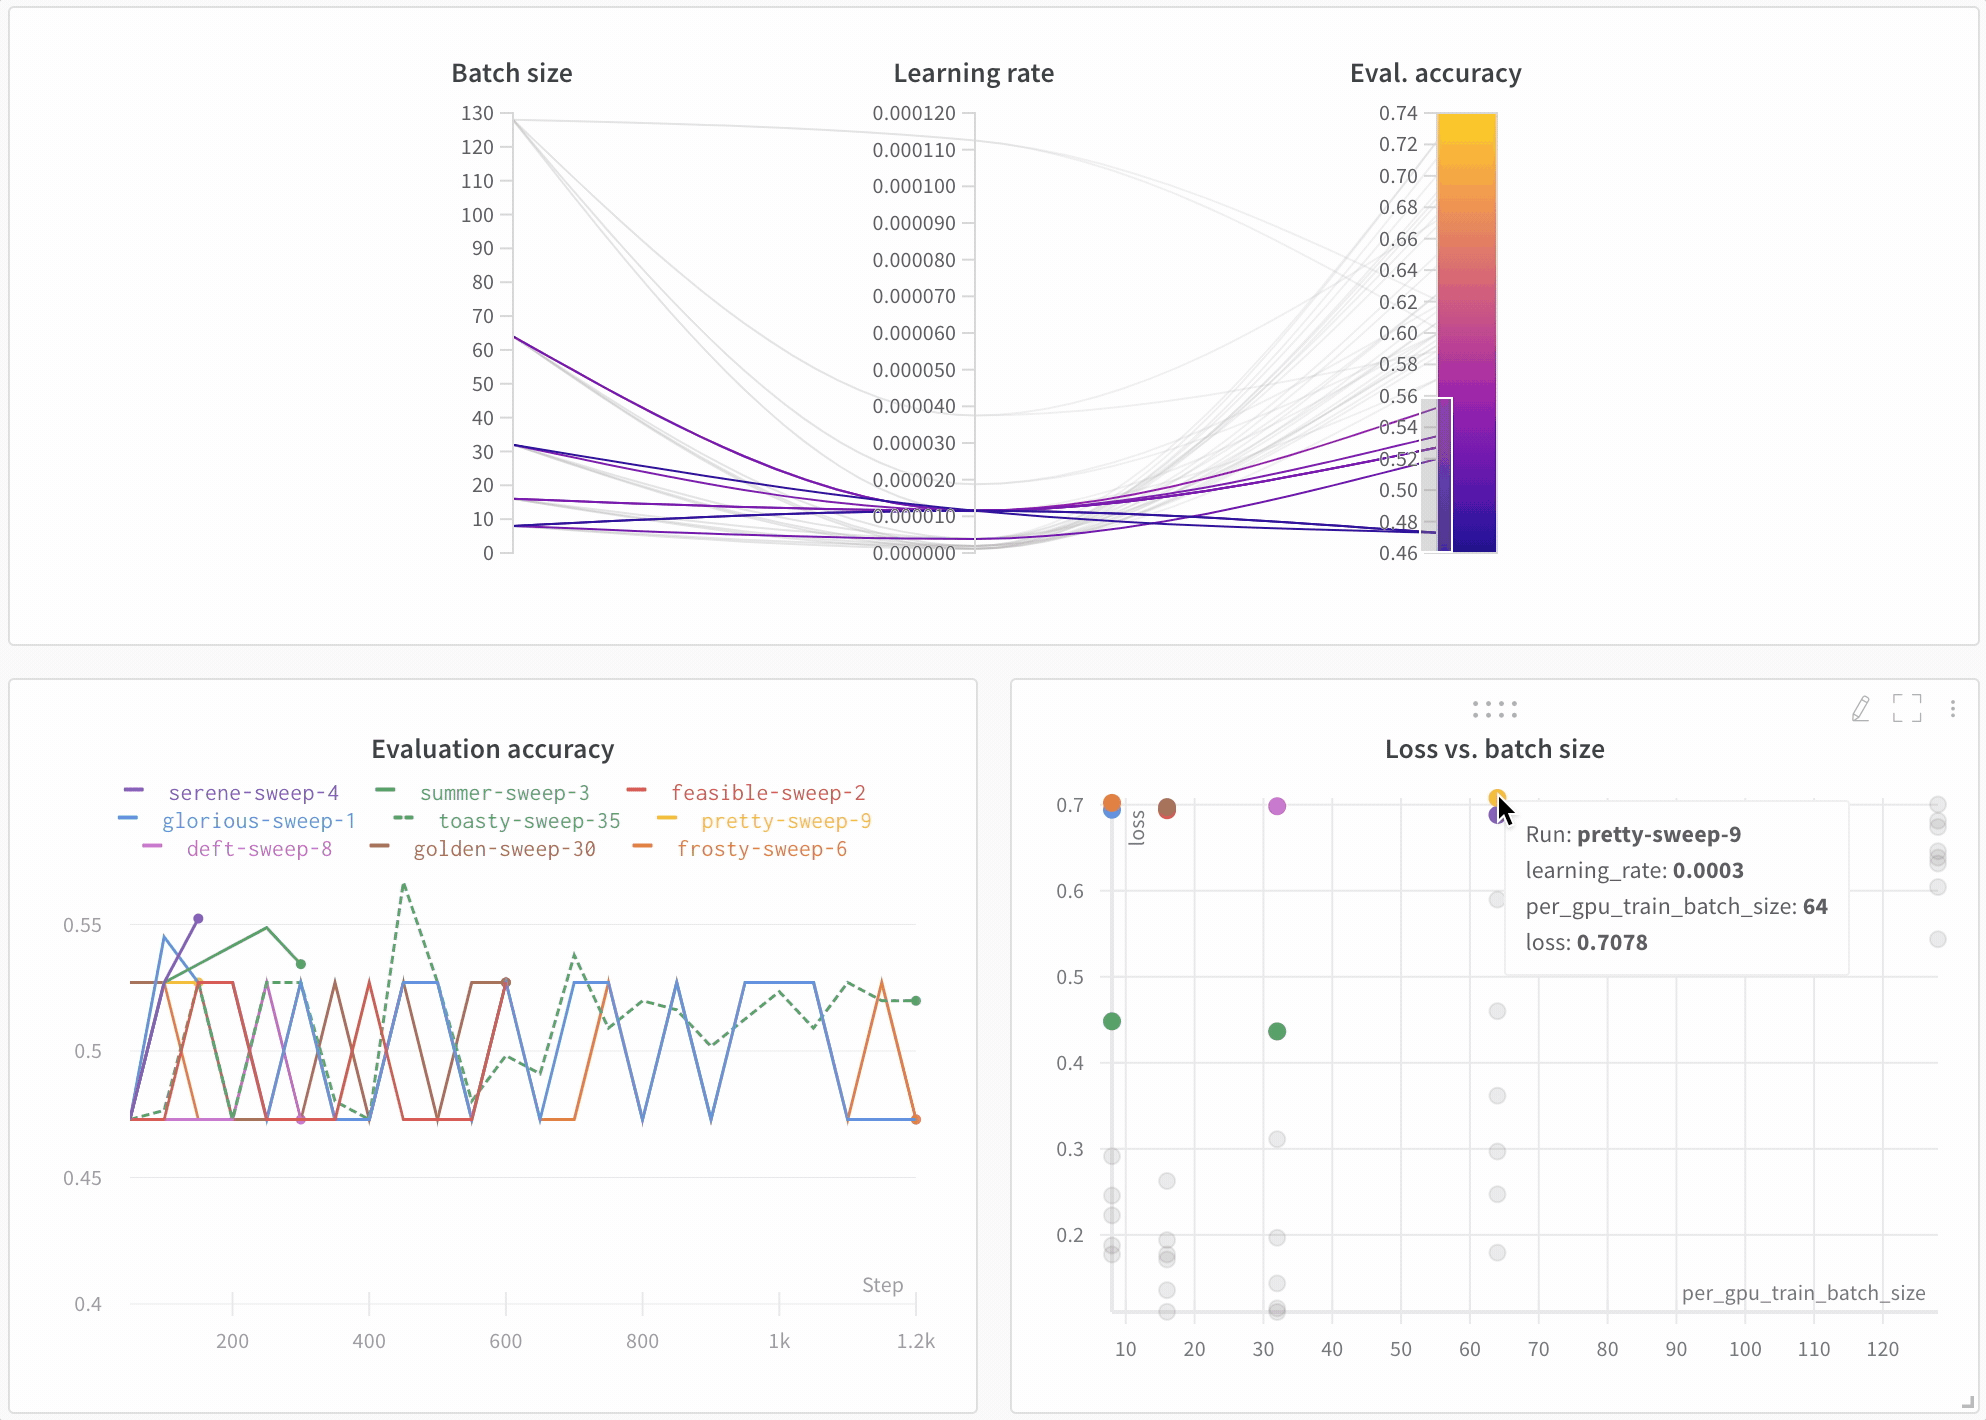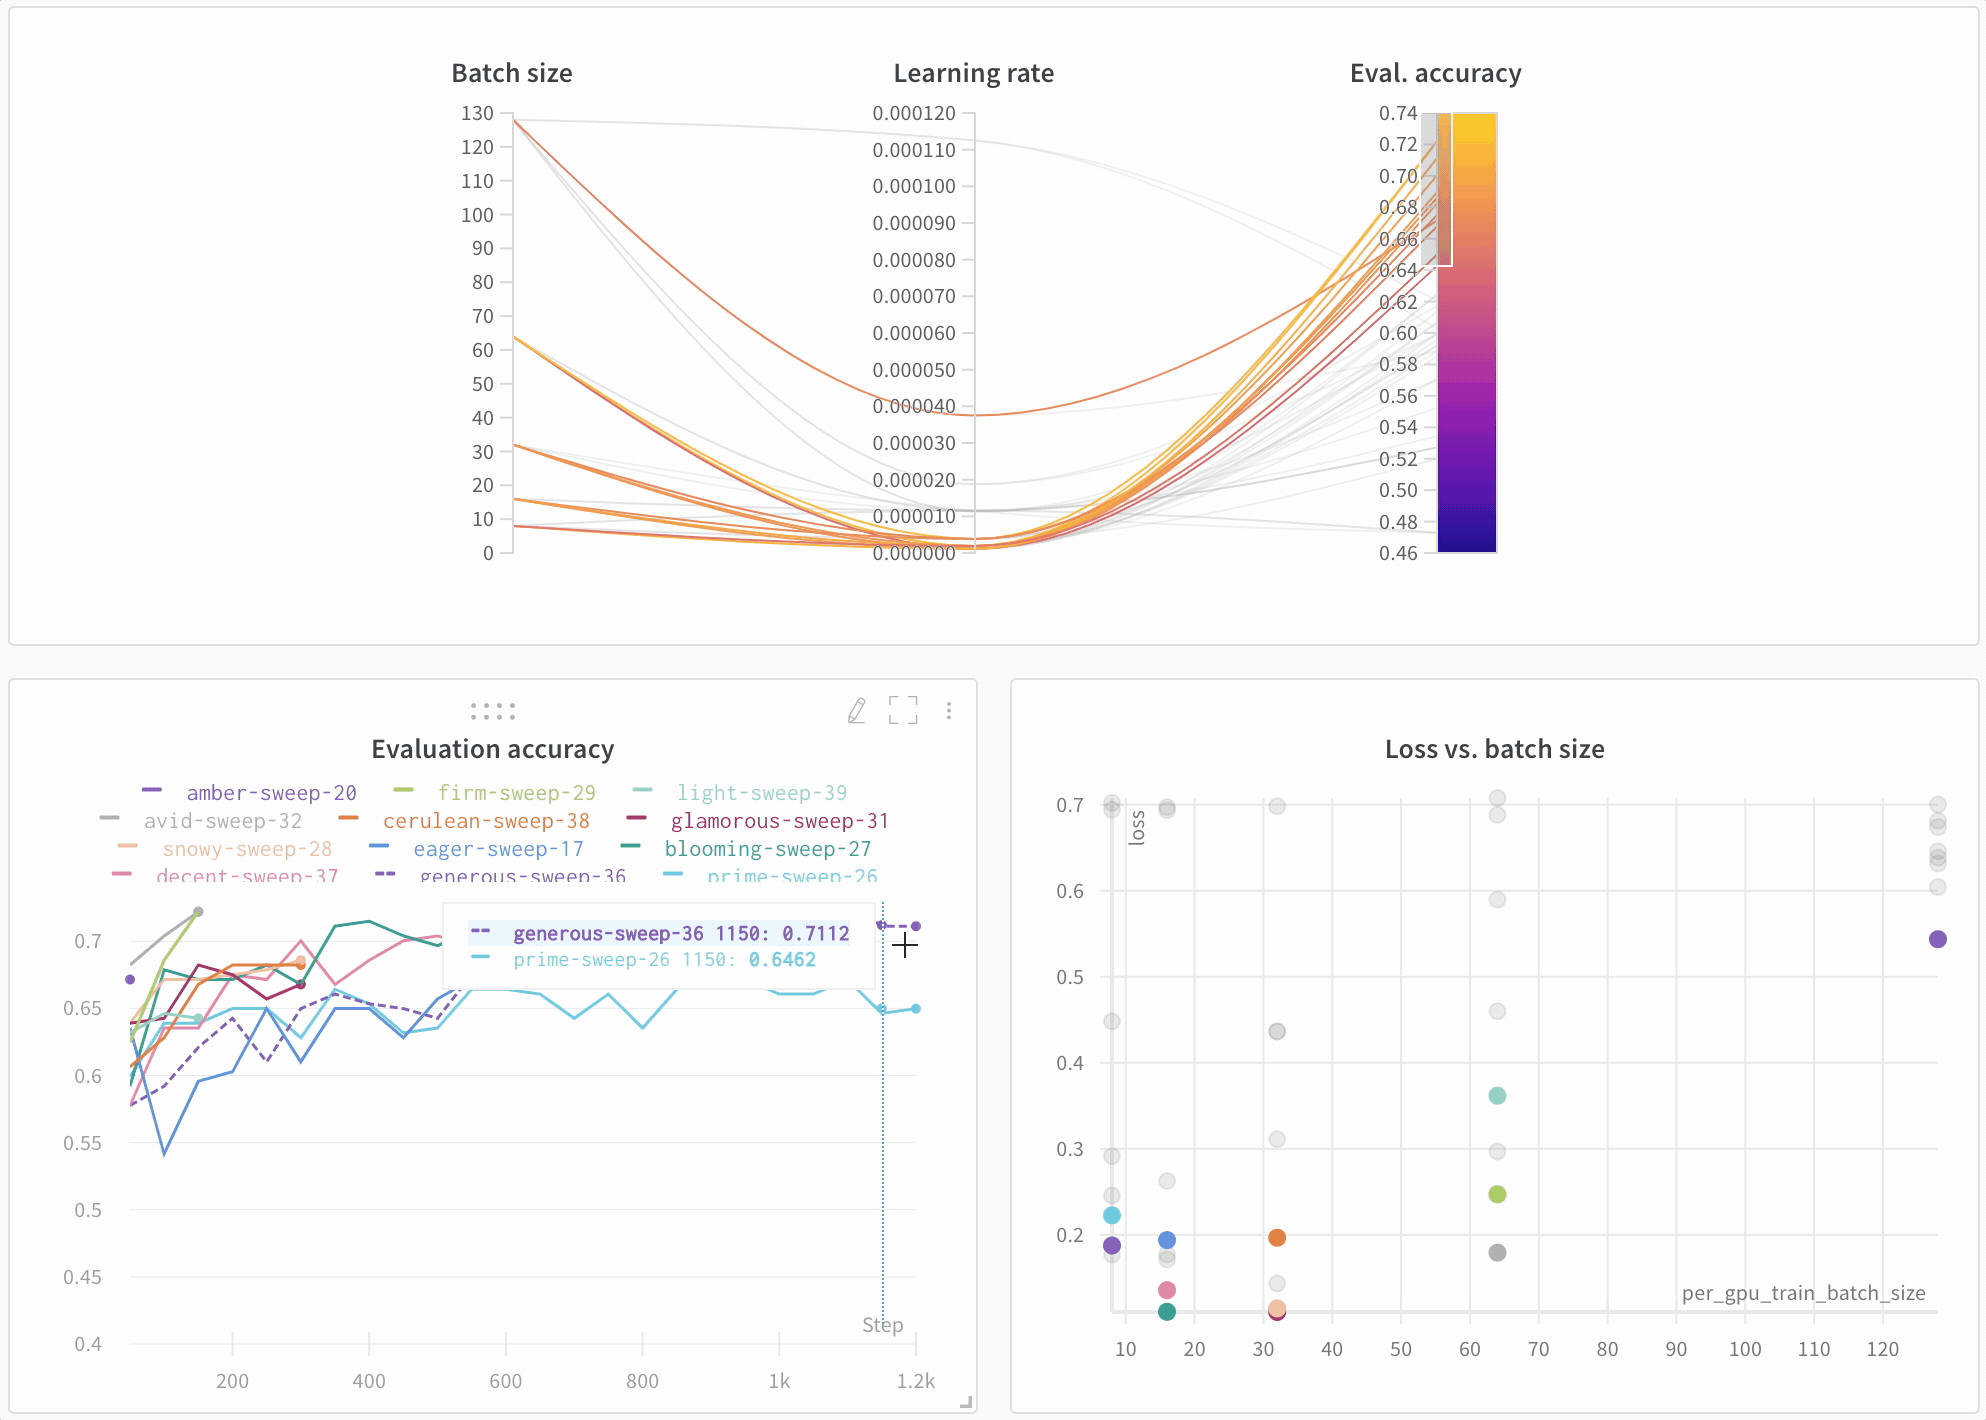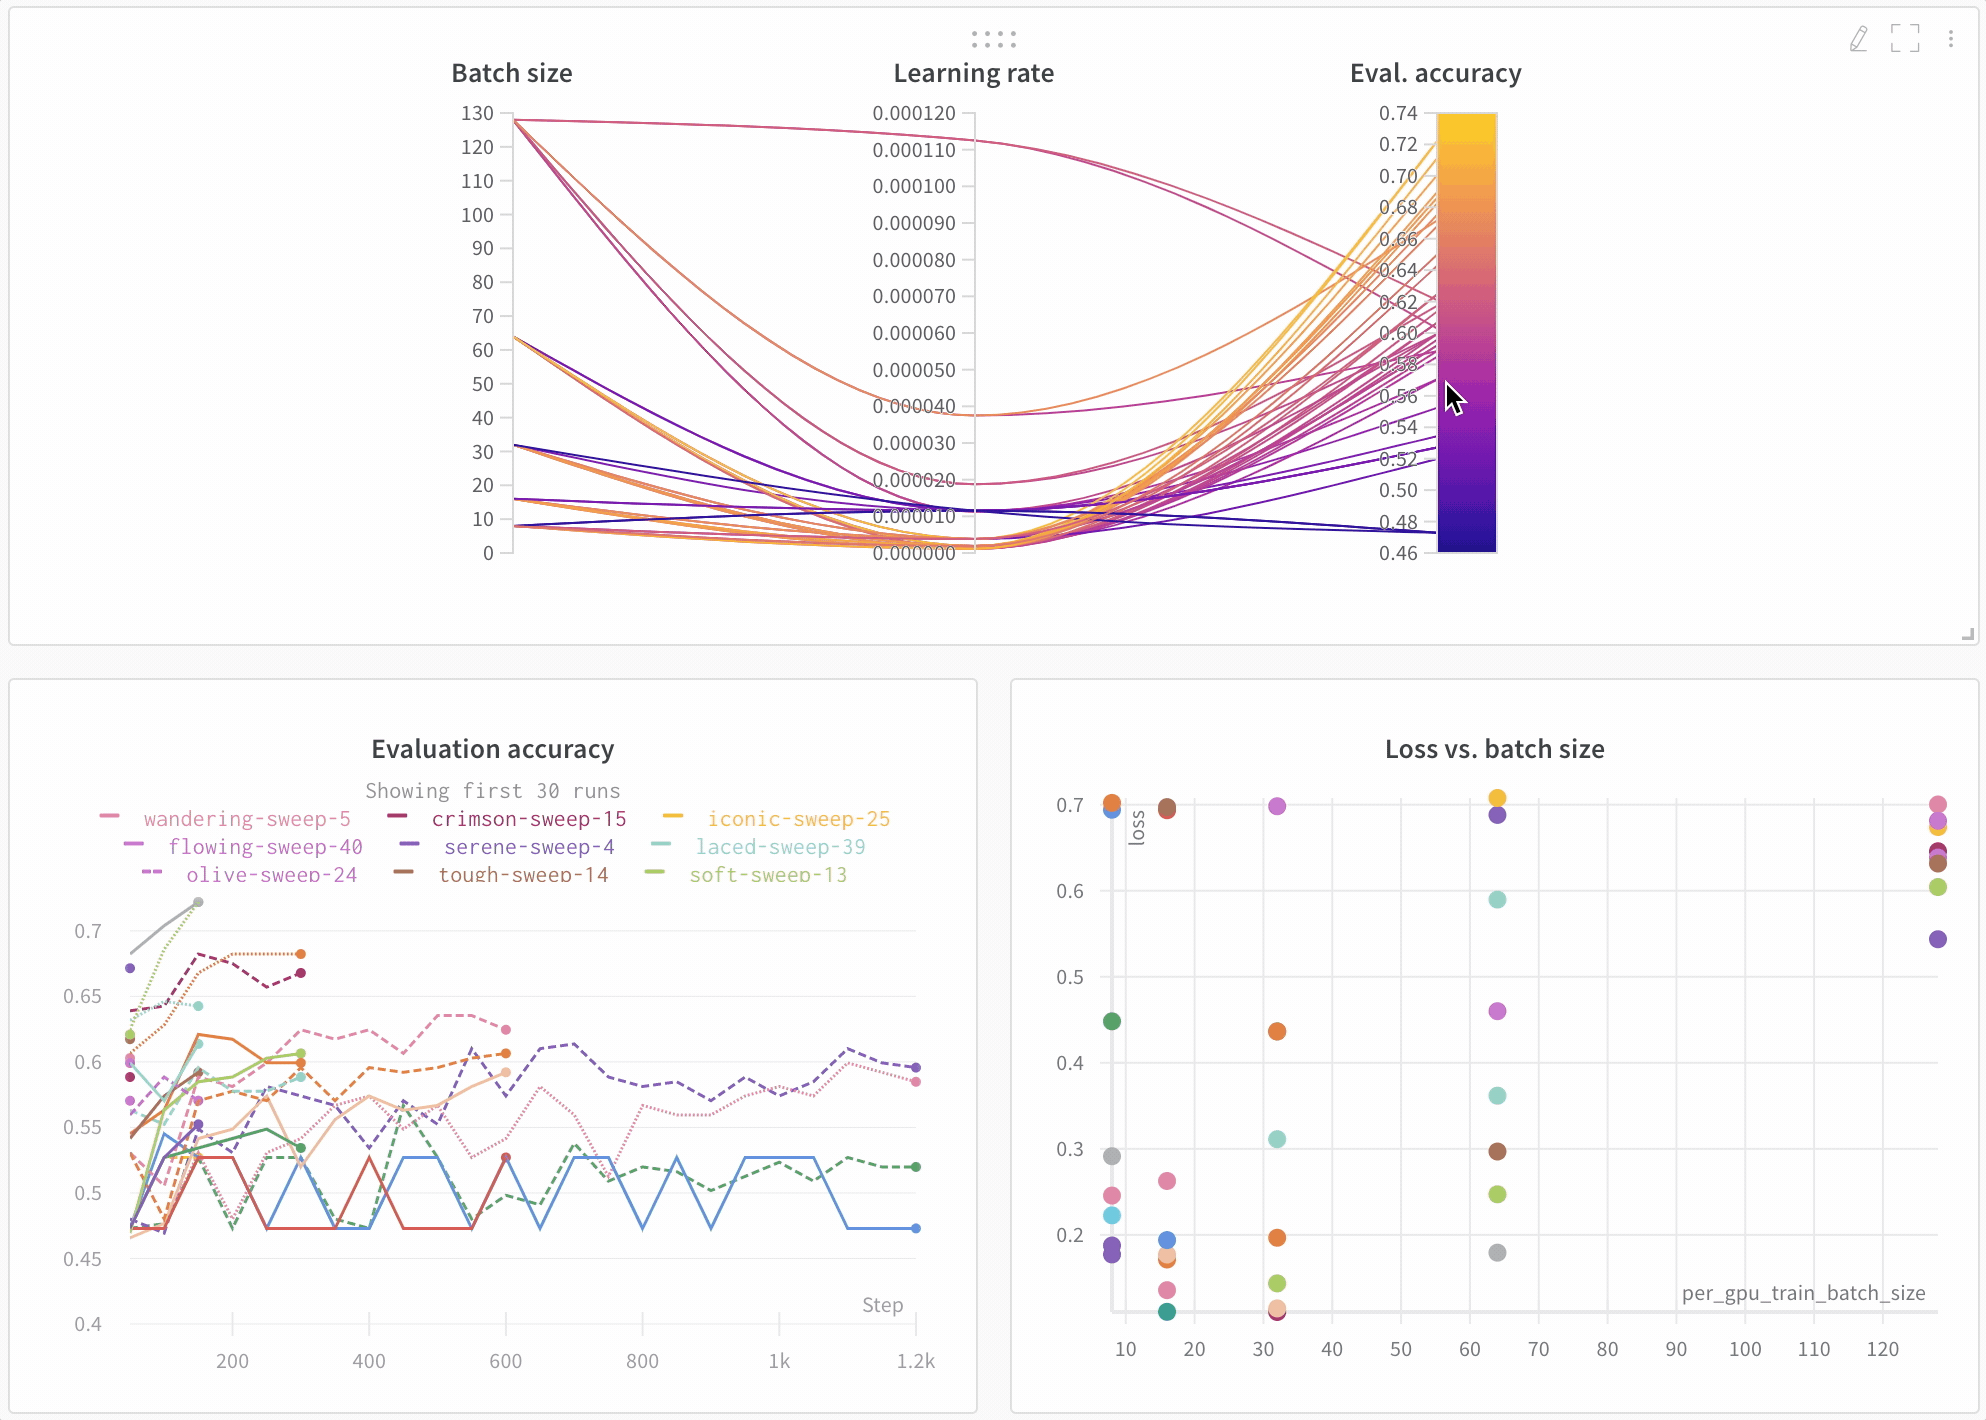
- **Visualize Model Performance**
- It's easy to look across dozens of experiments, zoom in on interesting findings, and visualize highly dimensional data.
+ Open the completed run to review its training and evaluation metrics, inspect system metrics, and compare it with other experiments:
- 
+ [**View the training run in W&B**]({wandb_run_url})
- **Compare Architectures**
- Here's an example comparing [BERT vs DistilBERT](https://app.wandb.ai/jack-morris/david-vs-goliath/reports/Does-model-size-matter%3F-Comparing-BERT-and-DistilBERT-using-Sweeps--VmlldzoxMDUxNzU) — it's easy to see how different architectures effect the evaluation accuracy throughout training with automatic line plot visualizations.
- 
- """)
- return
+ ## Next step: Compare architectures
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Track key information effortlessly by default
- Weights & Biases saves a new run for each experiment. Here's the information that gets saved by default:
- - **Hyperparameters**: Settings for your model are saved in Config
- - **Model Metrics**: Time series data of metrics streaming in are saved in Log
- - **Terminal Logs**: Command line outputs are saved and available in a tab
- - **System Metrics**: GPU and CPU utilization, memory, temperature etc.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Learn more!
- - [Documentation](https://docs.wandb.ai/tutorials/huggingface/): docs on the Weights & Biases and Hugging Face integration
- - [Videos](http://wandb.me/youtube): tutorials, interviews with practitioners, and more on our YouTube channel
- - Contact: Message us at contact@wandb.com with questions
+ Explore a W&B report that [compares BERT and DistilBERT](https://app.wandb.ai/jack-morris/david-vs-goliath/reports/Does-model-size-matter%3F-Comparing-BERT-and-DistilBERT-using-Sweeps--VmlldzoxMDUxNzU) to see how model architecture affects evaluation accuracy during training.
""")
return
From e8d2261df7bc8ef1999d5dd68456b8bb562eaa3c Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Tue, 13 Oct 2026 08:22:08 -0700
Subject: [PATCH 03/48] sweeps
---
...mization_in_tensorflow_using_w_b_sweeps.py | 364 +++++-------------
1 file changed, 92 insertions(+), 272 deletions(-)
diff --git a/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py b/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py
index 81c40dc8..56992bd9 100644
--- a/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py
+++ b/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py
@@ -11,9 +11,11 @@
import marimo
-__generated_with = "0.24.2"
-app = marimo.App(width="medium", app_title="TensorFlow hyperparameter sweeps with W&B")
-
+__generated_with = "0.25.1"
+app = marimo.App(
+ width="medium",
+ app_title="TensorFlow hyperparameter sweeps with W&B",
+)
with app.setup:
import marimo as mo
@@ -33,16 +35,11 @@ def _():
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py/server)
- """)
- return
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Use Weights & Biases for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-
+ This notebook shows the smallest practical loop for tuning TensorFlow
+ hyperparameters with Weights & Biases Sweeps: define a search space, turn one
+ training run into a reusable function, launch an agent, and inspect the
+ results in W&B.
""")
return
@@ -50,7 +47,12 @@ def _():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- Use Weights & Biases Sweeps to automate hyperparameter optimization and explore the space of possible models, complete with interactive dashboards like this:
+ A sweep is a coordinated set of experiment runs. W&B chooses hyperparameter
+ values, starts runs through your training function, logs metrics from each
+ trial, and builds dashboards for comparing the results.
+
+ By the end of the notebook, your sweep dashboard will look conceptually like
+ this example:

""")
@@ -60,22 +62,21 @@ def _():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Why Should I Use Sweeps?
-
- * **Quick setup**: With just a few lines of code you can run W&B sweeps.
- * **Transparent**: We cite all the algorithms we're using, and [our code is open source](https://github.com/wandb/wandb).
- * **Powerful**: Our sweeps are completely customizable and configurable. You can launch a sweep across dozens of machines, and it's just as easy as starting a sweep on your laptop.
-
- **[Check out the official documentation $\rightarrow$](https://docs.wandb.ai/models/sweeps/)**
+ [Weights & Biases Sweeps](https://docs.coreweave.com/products/wandb/sweeps)
+ automate hyperparameter search and visualize rich, interactive experiment
+ tracking. They support search methods such as random search, grid search, and
+ Bayesian optimization, and they can scale from this single-notebook example to
+ agents running on many machines.
## What this notebook covers
- * Simple steps to get started with W&B Sweeps and TensorFlow.
- * Use Keras' current `WandbMetricsLogger` callback to track each training run.
- * Find the best hyperparameters for an image classification task.
+ The cells below walk through the core W&B Sweeps pattern:
- **Note**: Sections starting with _Step_ are all you need to perform a hyperparameter sweep in existing code.
- The rest of the code is there to set up a simple example.
+ * Authenticate with W&B.
+ * Prepare a small TensorFlow image-classification problem.
+ * Log training and validation metrics from Keras.
+ * Define a sweep configuration for batch size and learning rate.
+ * Launch a W&B agent that runs multiple trials and reports results.
""")
return
@@ -83,24 +84,13 @@ def _():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Setup and Authentication
-
- ### Step 1: Import W&B and log in
-
- The setup cell imports TensorFlow, NumPy, W&B, and the dedicated
- `WandbMetricsLogger` callback. W&B's former all-in-one `WandbCallback` is
- [legacy](https://docs.wandb.ai/models/integrations/keras); new Keras
- workflows should use the dedicated metrics, checkpoint, or evaluation
- callbacks for the behavior they need. This tutorial only needs metrics.
+ ## Step 1: Import W&B and log in
- Enter your [W&B API key](https://wandb.ai/authorize), or leave it blank to
- use `WANDB_API_KEY` from the molab Secrets panel or credentials already
- stored in this runtime. A fresh molab session does not inherit your local
- login. If needed, [create a free W&B account](https://wandb.ai/signup).
+ The next two cells collect your W&B credentials and call `wandb.login()`.
+ W&B needs an authenticated session before it can create a sweep or sync
+ training metrics.
- The entity is the team name in your W&B project URL:
- `wandb.ai//`. Leave it blank to use your default entity.
- Changing either field does nothing until you submit the form.
+ Run the following cell and provide your [Forge API key](https://wandb.ai/authorize) and the name of your team. Then click **Connect to Weights & Biases**.
""")
return
@@ -112,17 +102,17 @@ def _():
.batch(
api_key=mo.ui.text(
kind="password",
- label="W&B API key (optional)",
+ label="Forge API key (optional)",
placeholder="Paste a key or use configured credentials",
full_width=True,
),
entity=mo.ui.text(
- label="W&B entity or team (optional)",
+ label="Forge team name (optional)",
placeholder="Leave blank to use your default entity",
full_width=True,
),
)
- .form(submit_button_label="Connect to W&B", bordered=True)
+ .form(submit_button_label="Connect to Weights & Biases", bordered=True)
)
wandb_login_form
return (wandb_login_form,)
@@ -156,19 +146,22 @@ def _(wandb_login_form):
),
)
- wandb_connection = {"entity": _submitted["entity"].strip() or None}
mo.callout(mo.md("Connected to W&B."), kind="success")
- return (wandb_connection,)
+ return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Prepare Dataset
+ ## Step 2: Prepare the Dataset
+
+ The following function loads MNIST, normalizes pixel values, flattens each
+ image into a 784-feature vector, and returns `tf.data.Dataset` objects for
+ training and validation.
- MNIST is downloaded and converted into shuffled training batches and stable
- validation batches only after you explicitly start the sweep agent. Opening
- this notebook does not download data or start training.
+ The function accepts `batch_size` because the sweep will tune that value. Each
+ W&B trial can therefore build datasets that match the hyperparameters chosen
+ for that run.
""")
return
@@ -199,9 +192,11 @@ def prepare_datasets(batch_size):
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Define the Model and Training Workflow
+ ## Step 3: Define the Model and Training Workflow
- ### Build a Simple Classifier MLP
+ The next function builds the TensorFlow model that every sweep trial will
+ train. We keep the architecture fixed so the sweep can focus on two
+ hyperparameters: batch size and learning rate.
""")
return
@@ -219,14 +214,15 @@ def Model():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ### Write a Training Workflow
+ ## Step 4: Log metrics with `WandbMetricsLogger`
- #### Step 3: Log metrics with `WandbMetricsLogger`
+ The next function wraps `model.fit()` and attaches W&B's Keras metrics
+ logger. `WandbMetricsLogger` receives the training and validation metrics
+ produced by Keras and sends them to the active W&B run.
- `WandbMetricsLogger` receives the training and validation metrics produced by
- `model.fit`. With `log_freq=20`, it logs batch metrics every 20 batches and
- epoch metrics at the end of each epoch. The callback is constructed only
- inside an active W&B run.
+ With `log_freq=20`, it logs batch metrics every 20 batches and epoch metrics
+ at the end of each epoch. Those logged values are what the sweep dashboard
+ uses to compare trials.
""")
return
@@ -252,16 +248,17 @@ def train(
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 4: Configure the Sweep
+ ## Step 5: Configure the Sweep
- This is where you will:
+ The next cell defines the sweep configuration dictionary. This is the contract
+ between your training code and W&B: it tells W&B which hyperparameters to try,
+ how to sample them, which metric to optimize, and when to stop weaker runs
+ early.
* Define the hyperparameters you're sweeping over.
- * Provide your hyperparameter optimization method. W&B supports `random`, `grid`, and `bayes` methods.
- * Provide an objective and a `metric` if using `bayes`; here we minimize `epoch/val_loss`, the validation-loss key logged by `WandbMetricsLogger`.
+ * Choose a hyperparameter search method. W&B supports `random`, `grid`, and `bayes`.
+ * Provide an objective metric; here we minimize `epoch/val_loss`, the validation-loss key logged by `WandbMetricsLogger`.
* Use `hyperband` for early termination of poorly-performing runs.
-
- ### [Check out more on Sweep configurations $\rightarrow$](https://docs.wandb.ai/models/sweeps/define-sweep-configuration)
""")
return
@@ -294,11 +291,16 @@ def _():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 5: Wrap the Training Workflow
+ ## Step 6: Wrap the Training Workflow
+
+ A W&B agent needs a zero-argument training function. The next function,
+ `sweep_train`, is one complete trial: it starts a W&B run, reads the
+ hyperparameters selected for that run from `run.config`, prepares data,
+ builds and compiles the model, trains it, and lets W&B collect metrics.
- You'll need a zero-argument function, like `sweep_train` below, that calls
- `wandb.init()` and uses the resulting run configuration before training.
- A context manager finishes every run before the agent starts its next trial.
+ The defaults passed to `wandb.init()` make the function runnable on its own,
+ while sweep-selected values override `batch_size` and `learning_rate` during
+ agent runs.
""")
return
@@ -351,183 +353,27 @@ def sweep_train():
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 6: Initialize the Sweep and Run an Agent
+ ## Step 7: Initialize the Sweep and Run an Agent
- Creating a sweep registers a new object in W&B. Enter a project and submit
- the form when you are ready; changing the unsubmitted field is inert.
+ The next cell registers the sweep with W&B and stores the returned
+ `sweep_id`. The cell after that starts a local sweep agent.
+
+ The agent asks W&B for hyperparameter values, calls `sweep_train` for each
+ trial, and repeats until it reaches `count=10`. You can lower `count` while
+ experimenting if you want a faster run.
""")
return
-@app.cell(hide_code=True)
-def _(sweep_config, wandb_connection):
- _entity_note = (
- f"The sweep will belong to entity `{wandb_connection['entity']}`."
- if wandb_connection["entity"]
- else "The sweep will use your default W&B entity."
- )
- _parameter_note = ", ".join(f"`{name}`" for name in sweep_config["parameters"])
- sweep_creation_form = (
- mo.md("{project}")
- .batch(
- project=mo.ui.text(
- value="sweeps-tensorflow",
- label="W&B project",
- full_width=True,
- )
- )
- .form(submit_button_label="Create W&B sweep", bordered=True)
- )
- mo.vstack(
- [
- mo.md(f"{_entity_note} This configuration searches {_parameter_note}."),
- sweep_creation_form,
- ]
- )
- return (sweep_creation_form,)
-
-
-@app.cell(hide_code=True)
-def _(sweep_config, sweep_creation_form, wandb_connection):
- mo.stop(
- sweep_creation_form.value is None,
- mo.callout(
- mo.md("Submit the form above when you are ready to create the sweep."),
- kind="info",
- ),
- )
- _project = sweep_creation_form.value["project"].strip()
- mo.stop(
- not _project,
- mo.callout(
- mo.md("Enter a W&B project name and submit again."),
- kind="danger",
- ),
- )
- sweep_request = {
- "config": sweep_config.copy(),
- "entity": wandb_connection["entity"],
- "project": _project,
- }
- return (sweep_request,)
-
-
@app.cell
-def _(mo, sweep_request):
- sweep_entity = sweep_request["entity"] or wandb.Api().default_entity
- mo.stop(
- not sweep_entity,
- mo.callout(
- mo.md(
- "W&B did not return a default entity. Enter a team entity in "
- "the authentication form and reconnect before creating the sweep."
- ),
- kind="danger",
- ),
- )
- sweep_id = wandb.sweep(
- sweep=sweep_request["config"],
- entity=sweep_entity,
- project=sweep_request["project"],
- )
- sweep_result = {
- "id": sweep_id,
- "entity": sweep_entity,
- "project": sweep_request["project"],
- "url": (
- f"https://wandb.ai/{sweep_entity}/{sweep_request['project']}"
- f"/sweeps/{sweep_id}"
- ),
- }
- return (sweep_result,)
-
-
-@app.cell(hide_code=True)
-def _(sweep_result):
- mo.callout(
- mo.md(
- f"Created sweep `{sweep_result['id']}`. "
- f"[Open the live Sweep dashboard]({sweep_result['url']})."
- ),
- kind="success",
- )
- return
-
-
-@app.cell(hide_code=True)
-def _(sweep_result, sweep_train):
- _training_function = sweep_train.__name__
- sweep_agent_form = (
- mo.md(
- f"Run an agent for sweep `{sweep_result['id']}`. The original "
- "tutorial uses 10 trials; lower the count for a quicker test."
- f" Each trial calls `{_training_function}`.\n\n{{count}}"
- )
- .batch(
- count=mo.ui.number(
- start=1,
- stop=10,
- step=1,
- value=10,
- label="Maximum sweep trials",
- )
- )
- .form(submit_button_label="Start sweep agent and training", bordered=True)
- )
- sweep_agent_form
- return (sweep_agent_form,)
-
-
-@app.cell(hide_code=True)
-def _(sweep_agent_form, sweep_result, sweep_train):
- mo.stop(
- sweep_agent_form.value is None,
- mo.callout(
- mo.md(
- "Submit the form above to download MNIST and start the requested "
- "number of W&B training runs."
- ),
- kind="info",
- ),
- )
- agent_request = {
- "count": int(sweep_agent_form.value["count"]),
- "function": sweep_train,
- "sweep": sweep_result.copy(),
- }
- return (agent_request,)
+def _(sweep_config):
+ sweep_id = wandb.sweep(sweep_config, project="sweeps-tensorflow")
+ return (sweep_id,)
@app.cell
-def _(agent_request):
- if wandb.run is not None:
- wandb.run.finish()
-
- _sweep = agent_request["sweep"]
- wandb.agent(
- _sweep["id"],
- function=agent_request["function"],
- entity=_sweep["entity"],
- project=_sweep["project"],
- count=agent_request["count"],
- )
- agent_result = {
- "count": agent_request["count"],
- "url": _sweep["url"],
- }
- return (agent_result,)
-
-
-@app.cell(hide_code=True)
-def _(agent_result):
- mo.callout(
- mo.md(
- f"The agent completed up to {agent_result['count']} trials. "
- f"[Open the Sweep dashboard]({agent_result['url']}) to compare "
- "`epoch/val_loss`, batch size, and learning rate across runs."
- ),
- kind="success",
- )
+def _(sweep_id):
+ wandb.agent(sweep_id, function=sweep_train, count=10)
return
@@ -536,45 +382,19 @@ def _():
mo.md(r"""
## Visualize Results
- After creating the sweep, open the **Sweep dashboard** link above to see
- results arrive live. Compare parallel coordinates, parameter importance,
- and the `epoch/val_loss` chart to understand which configurations work best.
- """)
- return
-
+ After the sweep starts, W&B prints links to the project and sweep dashboards
+ in the notebook output. Open those links to watch trials arrive live and
+ compare their metrics.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Example Gallery
-
- See examples of projects tracked and visualized with W&B in our [Gallery →](https://wandb.ai/gallery).
- """)
- return
+ ```
+ View project at:
+ ```
+ In the W&B UI, compare parallel coordinates, parameter importance, and the
+ `epoch/val_loss` chart to understand which batch sizes and learning rates
+ worked best.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Best Practices
-
- 1. **Projects**: Log multiple runs to a project to compare them. `wandb.init(project="project-name")`
- 2. **Groups**: For multiple processes or cross validation folds, log each process as a run and group them together. `wandb.init(group="experiment-1")`
- 3. **Tags**: Add tags to track your current baseline or production model.
- 4. **Notes**: Type notes in the table to track the changes between runs.
- 5. **Reports**: Take quick notes on progress to share with colleagues and make dashboards and snapshots of your ML projects.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Advanced Setup
-
- 1. [Environment variables](https://docs.wandb.ai/models/track/environment-variables): Set API keys in environment variables so you can run training on a managed cluster.
- 2. [Offline mode](https://docs.wandb.ai/models/ref/cli/wandb-offline): Set `WANDB_MODE=offline` to train without syncing, then upload the saved run later with `wandb sync`.
- 3. [Self-managed W&B](https://docs.wandb.ai/guides/hosting/): Run W&B in your own infrastructure, including private-cloud and air-gapped environments.
+ https://docs.coreweave.com/products/wandb/sweeps/visualize-sweep-results
""")
return
From 4433721dacde4ed858a87c0fe02373099b6bd849 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Wed, 14 Oct 2026 09:19:37 -0700
Subject: [PATCH 04/48] wip
---
..._artifacts_time_to_live_ttl_walkthrough.py | 330 +++---------------
1 file changed, 52 insertions(+), 278 deletions(-)
diff --git a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
index 9b859d51..810ea3d4 100644
--- a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
+++ b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
@@ -10,10 +10,9 @@
import marimo
-__generated_with = "0.24.0"
+__generated_with = "0.25.1"
app = marimo.App(width="medium", app_title="W&B Artifact TTL Walkthrough")
-
with app.setup:
import random
import tarfile
@@ -35,39 +34,27 @@ def _():
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py/server)
- W&B Artifacts supports setting time-to-live policies on each version of an Artifact. The following examples show the use of TTL policy in a common Artifact logging workflow. We'll cover:
+ Schedule when artifacts are deleted from Weights & Biases with a W&B Artifact time-to-live (TTL) policy. When you delete an artifact, Weights & Biases marks that artifact as a soft-delete. In other words, the artifact is marked for deletion but files are not immediately deleted from storage.
- - Setting a TTL policy when creating an Artifact
- - Retroactively setting TTL for a specific Artifact alias
- - Using the W&B API to set a TTL for all versions of an Artifact
+ This notebook shows how to:
- TTL applies to user-generated Artifacts. Linking an Artifact version to W&B Registry deactivates its TTL policy, so use the examples below on versions whose lifecycle you intend to manage directly.
- """)
- return
+ - Set a TTL policy when creating an Artifact
+ - Retroactively set TTL policy for a specific Artifact alias
+ - Using Weights & Biases Python SDK to set a TTL for all versions of an Artifact
+ > Linking an Artifact version to Registry deactivates its TTL policy.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
## Setup
Let's do a few things before we get started. Below we will:
- - Connect to W&B
+ - Authenticate
- Download and sample a dataset
The notebook dependencies install the required libraries automatically.
- """)
- return
+ ### Authenticate
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Authentication
-
- Enter your [W&B API key](https://wandb.ai/authorize) and the team entity where you have permission to create runs and Artifacts. You can leave the key blank when this environment already has credentials, such as `WANDB_API_KEY` configured in the marimo Secrets panel. If the entity is blank, W&B uses your default entity.
-
- Changing these fields does nothing until you click **Connect to W&B**. Connecting authenticates and resolves the target path, but it does not create or modify any W&B object.
+ Run the following cell and provide your [Forge API key](https://wandb.ai/authorize) and the name of your team. Then click **Connect to Weights & Biases**.
""")
return
@@ -76,18 +63,18 @@ def _():
def _():
_api_key_input = mo.ui.text(
kind="password",
- label="W&B API key (optional)",
+ label="Weights & Biases API key (optional)",
placeholder="Paste a key or use configured credentials",
full_width=True,
)
_entity_input = mo.ui.text(
- label="W&B entity or team (optional)",
+ label="Weights & Biases entity or team (optional)",
placeholder="Leave blank to use your default entity",
full_width=True,
)
_project_input = mo.ui.text(
value="artifacts-ttl-demo",
- label="W&B project",
+ label="Weights & Biases project",
full_width=True,
)
wandb_login_form = (
@@ -97,7 +84,7 @@ def _():
entity=_entity_input,
project=_project_input,
)
- .form(submit_button_label="Connect to W&B", bordered=True)
+ .form(submit_button_label="Connect to Weights & Biases", bordered=True)
)
wandb_login_form
return (wandb_login_form,)
@@ -108,58 +95,38 @@ def _(wandb_login_form):
mo.stop(
wandb_login_form.value is None,
mo.callout(
- mo.md("Connect to W&B before running a remote Artifact step."),
+ mo.md("Submit the form above to authenticate before creating a sweep."),
kind="info",
),
)
- _api_key = wandb_login_form.value["api_key"].strip()
- _submitted_entity = wandb_login_form.value["entity"].strip()
+ _submitted = wandb_login_form.value
+ _api_key = _submitted["api_key"].strip()
try:
- _login_ok = wandb.login(
- key=_api_key or None,
- relogin=bool(_api_key),
- )
- _login_error = None
- except wandb.errors.Error as _error:
+ _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
+ except (wandb.errors.Error, ValueError):
_login_ok = False
- _login_error = str(_error)
mo.stop(
not _login_ok,
mo.callout(
mo.md(
- "W&B authentication did not complete. Check the API key and "
- f"try again.\n\nW&B reported: `{_login_error or 'unknown error'}`"
+ "W&B authentication did not complete. Check the API key or "
+ "molab Secrets configuration and submit again."
),
kind="danger",
),
)
- entity = _submitted_entity or wandb.Api().default_entity
- mo.stop(
- not entity,
- mo.callout(
- mo.md(
- "W&B did not return a default entity. Enter a team entity in "
- "the form above and reconnect."
- ),
- kind="danger",
- ),
- )
- project = wandb_login_form.value["project"].strip() or "artifacts-ttl-demo"
- wandb_settings = {"entity": entity, "project": project}
- mo.callout(
- mo.md(f"Connected. Remote steps will target `{entity}/{project}`."),
- kind="success",
- )
- return (wandb_settings,)
+ mo.callout(mo.md("Connected to W&B."), kind="success")
+ return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ### Image Sampling
+ ### Download images
+
For the purposes of the walkthrough, we will sample from the Imagenette dataset and organize them into training and validation directories in our notebook session. The block below:
- Creates folders for our sampled images if they don't already exist
@@ -171,44 +138,28 @@ def _():
return
-@app.cell(hide_code=True)
+@app.cell
def _():
- prepare_imagenette = mo.ui.run_button(label="Download and sample Imagenette")
- mo.vstack(
- [
- mo.md(
- "This downloads and extracts Imagenette locally, then keeps a "
- "random 5% sample. It does not contact W&B."
- ),
- prepare_imagenette,
- ]
- )
- return (prepare_imagenette,)
-
-
-@app.cell(hide_code=True)
-def _(prepare_imagenette):
- mo.stop(
- not prepare_imagenette.value,
- mo.callout(
- mo.md("Click the button above when you are ready to prepare the dataset."),
- kind="info",
- ),
- )
imagenette_url = "https://s3.amazonaws.com/fast-ai-imageclas/imagenette2-160.tgz"
+
imagenette_workspace = Path(
tempfile.mkdtemp(prefix="wandb-ttl-imagenette-")
)
- return imagenette_url, imagenette_workspace
-
-@app.cell
-def _(imagenette_url, imagenette_workspace):
imagenette_archive = imagenette_workspace / "imagenette.tgz"
+
urlretrieve(imagenette_url, imagenette_archive)
return (imagenette_archive,)
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ The retrieved photos are saved as a `tar` file. The next cell defines a function that lets us access the tar files.
+ """)
+ return
+
+
@app.function
def untar_file(file_path, dest_path):
destination = Path(dest_path).resolve()
@@ -234,7 +185,7 @@ def _(imagenette_archive):
@app.cell(hide_code=True)
def _():
mo.md(r"""
- We are going to use Imagenette dataset for this example. [Imagenette](https://github.com/fastai/imagenette) is a subset of 10 easily classified classes from Imagenet (tench, English springer, cassette player, chain saw, church, French horn, garbage truck, gas pump, golf ball, parachute). It was created by Jeremy Howard and is a great dataset to experiment with.
+ We are going to use Imagenette dataset for this example. [Imagenette](https://github.com/fastai/imagenette) is a subset of 10 classified classes from **Imagenet** (`tench`, `English springer`, `cassette player`, `chain saw`, `church`, `French horn`, `garbage truck`, `gas pump`, `golf ball`, and `parachute`).
""")
return
@@ -255,8 +206,7 @@ def _(dataset_dir):
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ### Image Preview
- Quick block to view some of the images in the sampled dataset.
+ Let's view some of the images in the sampled dataset:
""")
return
@@ -286,10 +236,10 @@ def _(train_source_dir):
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Setting TTL on New Artifacts
+ ## Setting TTL when you create a new artifact
Below we create two new Artifacts for our real and fake data. Because we have internal retention policies in hypothetical organization we'd like to remove any Artifact that has real data (potentially containing personal data). Below we:
- - Create a W&B Run to track the logging of these raw data Artifacts
+ - Create a Weights & Biases Run to track the logging of these raw data Artifacts
- Set the ttl attribute on the real raw data
- Log our two Artifacts
@@ -298,27 +248,6 @@ def _():
return
-@app.cell(hide_code=True)
-def _(train_source_dir, val_source_dir, wandb_settings):
- log_raw_artifacts_button = mo.ui.run_button(
- label="Log TTL demo Artifact versions"
- )
- mo.vstack(
- [
- mo.md(
- f"This creates a `raw-data` run in "
- f"`{wandb_settings['entity']}/{wandb_settings['project']}`, "
- "logs two distinct `real-raw` versions with a 10-day TTL, "
- "assigns them the `extended` and `compliant` aliases, and "
- "logs `fake-raw` without a custom TTL. The files come from "
- f"`{train_source_dir}` and `{val_source_dir}`."
- ),
- log_raw_artifacts_button,
- ]
- )
- return (log_raw_artifacts_button,)
-
-
@app.function
def log_raw_artifacts(entity, project, train_source_dir, val_source_dir):
with wandb.init(
@@ -370,31 +299,15 @@ def log_raw_artifacts(entity, project, train_source_dir, val_source_dir):
return run_url, alias_paths
-@app.cell(hide_code=True)
-def _(
- log_raw_artifacts_button,
- train_source_dir,
- val_source_dir,
- wandb_settings,
-):
- mo.stop(
- not log_raw_artifacts_button.value,
- mo.callout(
- mo.md("Click the button above when you are ready to create the Artifact versions."),
- kind="info",
- ),
- )
+@app.cell
+def _(train_source_dir, val_source_dir, wandb_settings):
raw_artifacts_run_url, raw_alias_paths = log_raw_artifacts(
wandb_settings["entity"],
wandb_settings["project"],
train_source_dir,
val_source_dir,
)
- mo.callout(
- mo.md(f"Artifacts logged: [open the W&B run]({raw_artifacts_run_url})."),
- kind="success",
- )
- return raw_alias_paths, raw_artifacts_run_url
+ return (raw_alias_paths,)
@app.cell(hide_code=True)
@@ -412,27 +325,6 @@ def _():
return
-@app.cell(hide_code=True)
-def _(raw_alias_paths, raw_artifacts_run_url, wandb_settings):
- update_alias_ttls_button = mo.ui.run_button(
- label="Update TTLs for real-raw:extended and :compliant"
- )
- mo.vstack(
- [
- mo.md(
- f"This reads those two aliases from "
- f"`{wandb_settings['entity']}/{wandb_settings['project']}`. "
- "It saves only TTL values that need to change. The source "
- f"Artifact upload completed in [this run]({raw_artifacts_run_url}). "
- f"The exact inputs are `{raw_alias_paths['extended']}` and "
- f"`{raw_alias_paths['compliant']}`."
- ),
- update_alias_ttls_button,
- ]
- )
- return (update_alias_ttls_button,)
-
-
@app.function
def update_alias_ttls(entity, project, alias_paths):
extended_path = alias_paths["extended"]
@@ -471,28 +363,13 @@ def update_alias_ttls(entity, project, alias_paths):
return changed, run_url
-@app.cell(hide_code=True)
-def _(raw_alias_paths, update_alias_ttls_button, wandb_settings):
- mo.stop(
- not update_alias_ttls_button.value,
- mo.callout(
- mo.md("Click the button above when you are ready to update the aliases."),
- kind="info",
- ),
- )
+@app.cell
+def _(raw_alias_paths, wandb_settings):
updated_aliases, alias_update_run_url = update_alias_ttls(
wandb_settings["entity"],
wandb_settings["project"],
raw_alias_paths,
)
- if updated_aliases:
- _alias_message = (
- f"Updated `{', '.join(updated_aliases)}`. "
- f"[Open the W&B run]({alias_update_run_url})."
- )
- else:
- _alias_message = "Both aliases already had the requested TTL values; no run or write was created."
- mo.callout(mo.md(_alias_message), kind="success")
return
@@ -509,24 +386,6 @@ def _():
return
-@app.cell(hide_code=True)
-def _(raw_artifacts_run_url, wandb_settings):
- clear_fake_raw_ttls_button = mo.ui.run_button(
- label="Clear TTL from every fake-raw version"
- )
- mo.vstack(
- [
- mo.md(
- f"This searches `{wandb_settings['entity']}/{wandb_settings['project']}` "
- "and saves only versions whose TTL is currently set. The "
- f"source upload completed in [this run]({raw_artifacts_run_url})."
- ),
- clear_fake_raw_ttls_button,
- ]
- )
- return (clear_fake_raw_ttls_button,)
-
-
@app.function
def clear_fake_raw_ttls(entity, project):
# Artifact metadata extraction
@@ -565,30 +424,11 @@ def clear_fake_raw_ttls(entity, project):
return unique_versions, versions_to_clear, run_url
-@app.cell(hide_code=True)
-def _(clear_fake_raw_ttls_button, wandb_settings):
- mo.stop(
- not clear_fake_raw_ttls_button.value,
- mo.callout(
- mo.md("Click the button above when you are ready to clear the TTL policies."),
- kind="info",
- ),
- )
+@app.cell
+def _(wandb_settings):
fake_raw_versions, cleared_versions, clear_ttls_run_url = clear_fake_raw_ttls(
wandb_settings["entity"], wandb_settings["project"]
)
- if cleared_versions:
- _clear_message = (
- f"Cleared TTL from {len(cleared_versions)} of "
- f"{len(fake_raw_versions)} discovered versions. "
- f"[Open the W&B run]({clear_ttls_run_url})."
- )
- else:
- _clear_message = (
- f"Found {len(fake_raw_versions)} `fake-raw` versions, all already "
- "without a custom TTL. No run or write was created."
- )
- mo.callout(mo.md(_clear_message), kind="success")
return
@@ -617,26 +457,6 @@ def _():
return
-@app.cell(hide_code=True)
-def _(raw_artifacts_run_url, wandb_settings):
- preprocess_artifact_button = mo.ui.run_button(
- label="Preprocess real-raw:latest and log real-prepro"
- )
- mo.vstack(
- [
- mo.md(
- f"This downloads `real-raw:latest` from "
- f"`{wandb_settings['entity']}/{wandb_settings['project']}`, "
- "resizes its images, and creates a new downstream Artifact "
- "version. Every click intentionally creates a new version. "
- f"The source upload completed in [this run]({raw_artifacts_run_url})."
- ),
- preprocess_artifact_button,
- ]
- )
- return (preprocess_artifact_button,)
-
-
@app.function
def preprocess_image(image_path):
"Resize the image to 64x64"
@@ -678,23 +498,12 @@ def preprocess_and_log_artifact(entity, project):
return run_url
-@app.cell(hide_code=True)
-def _(preprocess_artifact_button, wandb_settings):
- mo.stop(
- not preprocess_artifact_button.value,
- mo.callout(
- mo.md("Click the button above when you are ready to create the downstream Artifact."),
- kind="info",
- ),
- )
+@app.cell
+def _(wandb_settings):
preprocessing_run_url = preprocess_and_log_artifact(
wandb_settings["entity"], wandb_settings["project"]
)
- mo.callout(
- mo.md(f"Downstream Artifact logged: [open the W&B run]({preprocessing_run_url})."),
- kind="success",
- )
- return (preprocessing_run_url,)
+ return
@app.cell(hide_code=True)
@@ -706,26 +515,6 @@ def _():
return
-@app.cell(hide_code=True)
-def _(preprocessing_run_url, wandb_settings):
- set_downstream_ttls_button = mo.ui.run_button(
- label="Assign random TTLs to downstream dataset versions"
- )
- mo.vstack(
- [
- mo.md(
- f"This traverses consumers of `real-raw:latest` in "
- f"`{wandb_settings['entity']}/{wandb_settings['project']}` and "
- "saves a new random 1–100 day TTL on each downstream dataset "
- "version. Every click intentionally changes those policies. "
- f"The preprocessing upload completed in [this run]({preprocessing_run_url})."
- ),
- set_downstream_ttls_button,
- ]
- )
- return (set_downstream_ttls_button,)
-
-
@app.function
def set_downstream_ttls(entity, project):
api = wandb.Api()
@@ -764,26 +553,11 @@ def set_downstream_ttls(entity, project):
return changed_ttls, run_url
-@app.cell(hide_code=True)
-def _(set_downstream_ttls_button, wandb_settings):
- mo.stop(
- not set_downstream_ttls_button.value,
- mo.callout(
- mo.md("Click the button above when you are ready to change downstream TTL policies."),
- kind="info",
- ),
- )
+@app.cell
+def _(wandb_settings):
downstream_ttls, downstream_ttl_run_url = set_downstream_ttls(
wandb_settings["entity"], wandb_settings["project"]
)
- if downstream_ttls:
- _downstream_message = (
- f"Updated {len(downstream_ttls)} downstream dataset versions. "
- f"[Open the W&B run]({downstream_ttl_run_url})."
- )
- else:
- _downstream_message = "No downstream dataset versions were found, so no run or write was created."
- mo.callout(mo.md(_downstream_message), kind="success")
return
From a348c6a728ad7e1463b931e20159c09fa76d225b Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Wed, 14 Oct 2026 10:09:17 -0700
Subject: [PATCH 05/48] wip
---
..._artifacts_time_to_live_ttl_walkthrough.py | 621 ++++++------------
1 file changed, 202 insertions(+), 419 deletions(-)
diff --git a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
index 810ea3d4..39b949e8 100644
--- a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
+++ b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
@@ -15,6 +15,7 @@
with app.setup:
import random
+ import shutil
import tarfile
import tempfile
from datetime import timedelta
@@ -30,534 +31,316 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
- # Weights & Biases Artifacts Time-to-live (TTL) Walkthrough
+ # W&B Artifacts: Time-to-Live (TTL)
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py/server)
- Schedule when artifacts are deleted from Weights & Biases with a W&B Artifact time-to-live (TTL) policy. When you delete an artifact, Weights & Biases marks that artifact as a soft-delete. In other words, the artifact is marked for deletion but files are not immediately deleted from storage.
+ Use artifact TTL policies to schedule data retention. This lesson covers
+ setting a policy before upload, changing a policy on an existing version,
+ updating a collection of versions, and following artifact lineage.
- This notebook shows how to:
+ TTL is measured from an artifact version's creation time. Expiration
+ soft-deletes the version; storage cleanup happens separately. Linking a
+ version to Registry deactivates its TTL.
- - Set a TTL policy when creating an Artifact
- - Retroactively set TTL policy for a specific Artifact alias
- - Using Weights & Biases Python SDK to set a TTL for all versions of an Artifact
+ ## 1. Authenticate and Choose a Project
- > Linking an Artifact version to Registry deactivates its TTL policy.
+ The next cell calls `wandb.login()` and sets the destination for this demo.
+ Use a project for tutorial data and an account with permission to edit TTL
+ policies. Set `entity` to your team name, or leave it as `None` to use your
+ default entity.
- ## Setup
- Let's do a few things before we get started. Below we will:
+ Configure `WANDB_API_KEY` in your environment or the molab Secrets panel
+ before running. You can get a key from [W&B](https://wandb.ai/authorize).
+ In a terminal-backed session, `wandb.login()` can also prompt for a key.
- - Authenticate
- - Download and sample a dataset
-
- The notebook dependencies install the required libraries automatically.
-
- ### Authenticate
-
- Run the following cell and provide your [Forge API key](https://wandb.ai/authorize) and the name of your team. Then click **Connect to Weights & Biases**.
+ Running the code cells downloads Imagenette and uploads sample artifacts.
""")
return
-@app.cell(hide_code=True)
+@app.cell
def _():
- _api_key_input = mo.ui.text(
- kind="password",
- label="Weights & Biases API key (optional)",
- placeholder="Paste a key or use configured credentials",
- full_width=True,
- )
- _entity_input = mo.ui.text(
- label="Weights & Biases entity or team (optional)",
- placeholder="Leave blank to use your default entity",
- full_width=True,
- )
- _project_input = mo.ui.text(
- value="artifacts-ttl-demo",
- label="Weights & Biases project",
- full_width=True,
- )
- wandb_login_form = (
- mo.md("{api_key}\n\n{entity}\n\n{project}")
- .batch(
- api_key=_api_key_input,
- entity=_entity_input,
- project=_project_input,
- )
- .form(submit_button_label="Connect to Weights & Biases", bordered=True)
- )
- wandb_login_form
- return (wandb_login_form,)
-
-
-@app.cell(hide_code=True)
-def _(wandb_login_form):
- mo.stop(
- wandb_login_form.value is None,
- mo.callout(
- mo.md("Submit the form above to authenticate before creating a sweep."),
- kind="info",
- ),
- )
-
- _submitted = wandb_login_form.value
- _api_key = _submitted["api_key"].strip()
- try:
- _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
- except (wandb.errors.Error, ValueError):
- _login_ok = False
-
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md(
- "W&B authentication did not complete. Check the API key or "
- "molab Secrets configuration and submit again."
- ),
- kind="danger",
- ),
- )
-
- mo.callout(mo.md("Connected to W&B."), kind="success")
- return
+ entity = "wandb"
+ project = "artifacts-ttl-demo"
+ authenticated = wandb.login()
+ if not authenticated:
+ raise RuntimeError("Configure W&B credentials before running the lesson.")
+ return entity, project
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ### Download images
-
- For the purposes of the walkthrough, we will sample from the Imagenette dataset and organize them into training and validation directories in our notebook session. The block below:
+ ## 2. Prepare Sample Images
- - Creates folders for our sampled images if they don't already exist
- - Selects a random sample of images from the Imagenette dataset
- - Organizes the samples into training and validation directories
+ [Imagenette](https://github.com/fastai/imagenette) contains images from ten
+ ImageNet classes. The next cell downloads and extracts it into a temporary
+ workspace, then copies 5% of the training and validation images into sample
+ folders. Sampling leaves the extracted dataset intact, so rerunning the cell
+ does not repeatedly shrink it.
- *Note: we overwrite the files every time we execute this so we get new Artifact versions.*
+ We call the training sample "real" and the validation sample "fake" to
+ illustrate different retention policies. Both contain actual photographs;
+ these labels are only part of the example.
""")
return
@app.cell
def _():
- imagenette_url = "https://s3.amazonaws.com/fast-ai-imageclas/imagenette2-160.tgz"
+ workspace = Path(tempfile.mkdtemp(prefix="wandb-ttl-"))
+ archive = workspace / "imagenette.tgz"
- imagenette_workspace = Path(
- tempfile.mkdtemp(prefix="wandb-ttl-imagenette-")
+ urlretrieve(
+ "https://s3.amazonaws.com/fast-ai-imageclas/imagenette2-160.tgz",
+ archive,
)
- imagenette_archive = imagenette_workspace / "imagenette.tgz"
-
- urlretrieve(imagenette_url, imagenette_archive)
- return (imagenette_archive,)
+ # Validate archive entries before extracting downloaded files.
+ with tarfile.open(archive, "r:gz") as tar:
+ members = tar.getmembers()
+ for _member in members:
+ destination = (workspace / _member.name).resolve()
+ if not destination.is_relative_to(workspace.resolve()):
+ raise ValueError(f"Unsafe archive path: {_member.name}")
+ if not (_member.isfile() or _member.isdir()):
+ raise ValueError(f"Unsupported archive entry: {_member.name}")
+ tar.extractall(workspace, members=members)
+
+ train_source_dir = workspace / "sample" / "train"
+ val_source_dir = workspace / "sample" / "val"
+ rng = random.Random(1)
+
+ for split, sample_dir in [("train", train_source_dir), ("val", val_source_dir)]:
+ _images = sorted((workspace / "imagenette2-160" / split).rglob("*.JPEG"))
+ selected = rng.sample(_images, max(1, len(_images) // 20))
+ for _image in selected:
+ target = sample_dir / _image.parent.name / _image.name
+ target.parent.mkdir(parents=True, exist_ok=True)
+ shutil.copy2(_image, target)
+ return train_source_dir, val_source_dir, workspace
@app.cell(hide_code=True)
def _():
mo.md(r"""
- The retrieved photos are saved as a `tar` file. The next cell defines a function that lets us access the tar files.
+ Preview five images from the training sample before uploading them as an
+ artifact. This cell only displays local files.
""")
return
-@app.function
-def untar_file(file_path, dest_path):
- destination = Path(dest_path).resolve()
- destination.mkdir(parents=True, exist_ok=True)
- with tarfile.open(file_path, "r:gz") as tar:
- members = tar.getmembers()
- for member in members:
- member_path = (destination / member.name).resolve()
- if not member_path.is_relative_to(destination):
- raise ValueError(f"Unsafe path in archive: {member.name}")
- if not (member.isfile() or member.isdir()):
- raise ValueError(f"Unsupported archive entry: {member.name}")
- tar.extractall(destination, members=members)
-
-
@app.cell
-def _(imagenette_archive):
- untar_file(imagenette_archive, imagenette_archive.parent)
- dataset_dir = imagenette_archive.parent / "imagenette2-160"
- return (dataset_dir,)
+def _(train_source_dir):
+ _images = sorted(train_source_dir.rglob("*.JPEG"))[:5]
+ figure, axes = plt.subplots(1, len(_images), figsize=(15, 4), squeeze=False)
+ for axis, _image_path in zip(axes[0], _images):
+ with Image.open(_image_path) as _image:
+ axis.imshow(_image)
+ axis.axis("off")
+ figure.tight_layout()
+ plt.close(figure)
+ figure
+ return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- We are going to use Imagenette dataset for this example. [Imagenette](https://github.com/fastai/imagenette) is a subset of 10 classified classes from **Imagenet** (`tench`, `English springer`, `cassette player`, `chain saw`, `church`, `French horn`, `garbage truck`, `gas pump`, `golf ball`, and `parachute`).
- """)
- return
-
-
-@app.cell
-def _(dataset_dir):
- # let's keep 5% of the images
- for image in dataset_dir.rglob("*.JPEG"):
- if random.random() > 0.05:
- image.unlink()
+ ## 3. Set TTL When Creating an Artifact
- # we get two image folders: train and validation
- train_source_dir = dataset_dir / "train"
- val_source_dir = dataset_dir / "val"
- return train_source_dir, val_source_dir
+ The next cell starts a run, creates dataset artifacts with
+ `wandb.Artifact()`, adds files with `add_dir()`, and sets a ten-day TTL
+ before calling `run.log_artifact()`.
+ We create two versions of `real-raw`, with aliases `extended` and
+ `compliant`, so the next example can give them different policies. Different
+ directory names inside their manifests ensure these are distinct versions,
+ even though they contain the same images. Aliases name versions; they do
+ not have separate TTL policies.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Let's view some of the images in the sampled dataset:
+ We also log `fake-raw` with a ten-day TTL for the bulk-update example.
+ `wait()` ensures each upload finishes before later cells fetch it.
""")
return
-@app.function
-def show_sample_images(img_dir, num_images=5):
- images = list(img_dir.rglob("*.JPEG"))[:num_images]
- fig, axes = plt.subplots(1, len(images), figsize=(15, 5), squeeze=False)
-
- # Iterate over the images and display them
- for i, img_path in enumerate(images):
- img = Image.open(img_path)
- axes[0, i].imshow(img)
- axes[0, i].axis("off") # Turn off axis labels
-
- plt.tight_layout()
- return fig
-
-
@app.cell
-def _(train_source_dir):
- sample_figure = show_sample_images(train_source_dir)
- sample_figure
- return
+def _(entity, project, train_source_dir, val_source_dir):
+ with wandb.init(entity=entity, project=project, job_type="raw-data") as _run:
+ extended = wandb.Artifact("real-raw", type="dataset")
+ extended.add_dir(str(train_source_dir), name="extended-snapshot")
+ extended.ttl = timedelta(days=10)
+ logged_extended = _run.log_artifact(extended, aliases=["extended"])
+ logged_extended.wait()
+
+ compliant = wandb.Artifact("real-raw", type="dataset")
+ compliant.add_dir(str(train_source_dir), name="compliant-snapshot")
+ compliant.ttl = timedelta(days=10)
+ logged_compliant = _run.log_artifact(compliant, aliases=["compliant", "latest"])
+ logged_compliant.wait()
+
+ fake = wandb.Artifact("fake-raw", type="dataset")
+ fake.add_dir(str(val_source_dir))
+ fake.ttl = timedelta(days=10)
+ logged_fake = _run.log_artifact(fake)
+ logged_fake.wait()
+
+ project_path = f"{_run.entity}/{_run.project}"
+ raw_alias_paths = {
+ "extended": f"{project_path}/real-raw:extended",
+ "compliant": f"{project_path}/real-raw:compliant",
+ }
+ return project_path, raw_alias_paths
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Setting TTL when you create a new artifact
- Below we create two new Artifacts for our real and fake data. Because we have internal retention policies in hypothetical organization we'd like to remove any Artifact that has real data (potentially containing personal data). Below we:
+ ## 4. Change TTL on Existing Versions
- - Create a Weights & Biases Run to track the logging of these raw data Artifacts
- - Set the ttl attribute on the real raw data
- - Log our two Artifacts
+ Suppose we can now keep one version for a year and another indefinitely.
+ The next cell fetches each version by alias with `wandb.Api().artifact()`,
+ changes its `ttl`, and calls `save()` to persist the change.
- > We will use the train dataset as our real data and the validation dataset as our fake data.
+ A `timedelta` sets the retention duration; `None` deactivates TTL. Changing
+ the duration does not reset the version's creation date. These metadata
+ updates do not require a new run or another file upload.
""")
return
-@app.function
-def log_raw_artifacts(entity, project, train_source_dir, val_source_dir):
- with wandb.init(
- entity=entity,
- project=project,
- job_type="raw-data",
- reinit="create_new",
- ) as run:
- raw_extended_art = wandb.Artifact(
- "real-raw",
- type="dataset",
- description="Raw Imagenette sample approved for extended retention",
- )
- raw_extended_art.add_dir(train_source_dir, name="extended-snapshot")
- raw_extended_art.ttl = timedelta(days=10)
- logged_extended_art = run.log_artifact(
- raw_extended_art,
- aliases=["extended"],
- )
- logged_extended_art.wait()
-
- raw_compliant_art = wandb.Artifact(
- "real-raw",
- type="dataset",
- description="Raw Imagenette sample approved for indefinite retention",
- )
- raw_compliant_art.add_dir(train_source_dir, name="compliant-snapshot")
- raw_compliant_art.ttl = timedelta(days=10)
- logged_compliant_art = run.log_artifact(
- raw_compliant_art,
- aliases=["compliant", "latest"],
- )
- logged_compliant_art.wait()
-
- raw_fake_art = wandb.Artifact(
- "fake-raw",
- type="dataset",
- description="Raw sample from val Imagenette",
- )
-
- raw_fake_art.add_dir(val_source_dir)
- logged_fake_art = run.log_artifact(raw_fake_art)
- logged_fake_art.wait()
- run_url = run.url
- alias_paths = {
- "extended": f"{entity}/{project}/real-raw:extended",
- "compliant": f"{entity}/{project}/real-raw:compliant",
- }
- return run_url, alias_paths
+@app.cell
+def _(raw_alias_paths):
+ _api = wandb.Api()
+ extended_artifact = _api.artifact(raw_alias_paths["extended"])
+ extended_artifact.ttl = timedelta(days=365)
+ extended_artifact.save()
+ compliant_artifact = _api.artifact(raw_alias_paths["compliant"])
+ compliant_artifact.ttl = None
+ compliant_artifact.save()
-@app.cell
-def _(train_source_dir, val_source_dir, wandb_settings):
- raw_artifacts_run_url, raw_alias_paths = log_raw_artifacts(
- wandb_settings["entity"],
- wandb_settings["project"],
- train_source_dir,
- val_source_dir,
- )
- return (raw_alias_paths,)
+ print(f"extended: {_api.artifact(raw_alias_paths['extended']).ttl}")
+ print(f"compliant: {_api.artifact(raw_alias_paths['compliant']).ttl}")
+ return (compliant_artifact,)
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Updating/Retroactively Setting TTL on Artifacts
- In our hypothetical organization we've been given approval to retain a specific version of our data indefinitely. We've also been given approval to extend the retention date of an additional dataset. Below we'll:
+ ## 5. Update All Versions in a Collection
+
+ `wandb.Api().artifacts()` lists the versions in an artifact collection.
+ The next cell queries `fake-raw` directly, then deactivates each version's
+ TTL with the same `ttl = None` and `save()` pattern.
- - Extend the TTL of an Artifact tagged with the `extended` alias
- - Remove the TTL of an Artifact tagged with the `compliant` alias
- - Programmatically check the status of these two Artifacts
+ This applies to every version of `fake-raw` in the selected project,
+ including versions from previous executions of the lesson.
- The preceding logging step creates two distinct `real-raw` versions and assigns these aliases. Retroactive TTL changes take effect when the code calls `artifact.save()`.
+ Team admins can also configure [default TTL policies](https://docs.wandb.ai/models/artifacts/ttl#set-default-ttl-policies-for-a-team)
+ for artifacts without a custom policy.
""")
return
-@app.function
-def update_alias_ttls(entity, project, alias_paths):
- extended_path = alias_paths["extended"]
- compliant_path = alias_paths["compliant"]
- api = wandb.Api()
- extended_current = api.artifact(extended_path)
- compliant_current = api.artifact(compliant_path)
- extended_ttl = timedelta(days=365)
- needs_extended_update = extended_current.ttl != extended_ttl
- needs_compliant_update = compliant_current.ttl is not None
-
- changed = []
- run_url = None
- if needs_extended_update or needs_compliant_update:
- with wandb.init(
- entity=entity,
- project=project,
- job_type="modify-ttl",
- reinit="create_new",
- ) as run:
- extended_art = run.use_artifact(extended_path)
- if needs_extended_update:
- extended_art.ttl = extended_ttl # Delete in a year
- extended_art.save()
- changed.append("real-raw:extended")
-
- compliant_art = run.use_artifact(compliant_path)
- if needs_compliant_update:
- compliant_art.ttl = None
- compliant_art.save()
- changed.append("real-raw:compliant")
-
- print(extended_art.ttl)
- print(compliant_art.ttl)
- run_url = run.url
- return changed, run_url
-
-
@app.cell
-def _(raw_alias_paths, wandb_settings):
- updated_aliases, alias_update_run_url = update_alias_ttls(
- wandb_settings["entity"],
- wandb_settings["project"],
- raw_alias_paths,
- )
+def _(project_path):
+ _api = wandb.Api()
+ cleared_versions = []
+ for _artifact in _api.artifacts(type_name="dataset", name=f"{project_path}/fake-raw"):
+ _artifact.ttl = None
+ _artifact.save()
+ cleared_versions.append(_artifact.qualified_name)
+ print(f"{_artifact.name}: {_artifact.ttl}")
return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Use W&B Import/Export API to Iterate Artifact Versions and Set TTL
- Let's say we've received approval to retain all of the data within a given Artifact and we'd like to remove all TTL policies for every version of an Artifact. Below we:
+ ## 6. Record Lineage During Preprocessing
+
+ The next cell consumes the `compliant` version of `real-raw`, resizes its
+ images to 64 by 64 pixels, and logs a new `real-prepro` artifact.
- - Use the W&B API to get a list of all Runs in a project
- - Get a list of all versions of a specific Artifact (e.g. `fake-raw`)
- - Iterate over each version and remove any existing TTL policy associated with the version
+ `run.use_artifact()` records the input relationship, and
+ `run.log_artifact()` records the output. Together they give W&B a lineage
+ graph connecting the source data, preprocessing run, and processed data.
""")
return
-@app.function
-def clear_fake_raw_ttls(entity, project):
- # Artifact metadata extraction
- api = wandb.Api()
-
- # Define entity and project
- runs = api.runs(entity + "/" + project)
-
- version_names = []
- for run in runs:
- for artifact in iter(run.logged_artifacts()):
- if "fake-raw" in artifact.name:
- # Can be edited to just display individual elements
- version_names.append(artifact.qualified_name)
-
- unique_versions = sorted(set(version_names))
- versions_to_clear = [
- version
- for version in unique_versions
- if api.artifact(version).ttl is not None
- ]
- run_url = None
- if versions_to_clear:
- with wandb.init(
- entity=entity,
- project=project,
- job_type="modify-ttl",
- reinit="create_new",
- ) as run:
- for version in versions_to_clear:
- version_art = run.use_artifact(version)
- version_art.ttl = None
- version_art.save()
- print(version_art.ttl)
- run_url = run.url
- return unique_versions, versions_to_clear, run_url
-
-
@app.cell
-def _(wandb_settings):
- fake_raw_versions, cleared_versions, clear_ttls_run_url = clear_fake_raw_ttls(
- wandb_settings["entity"], wandb_settings["project"]
- )
- return
+def _(compliant_artifact, entity, project, workspace):
+ with tempfile.TemporaryDirectory(dir=workspace) as _data_dir:
+ output_dir = Path(_data_dir) / "processed"
+ output_dir.mkdir()
+ with wandb.init(entity=entity, project=project, job_type="preprocessing") as _run:
+ source = _run.use_artifact(compliant_artifact.qualified_name)
+ source_dir = Path(source.download(root=str(Path(_data_dir) / "raw")))
+ for _image_path in source_dir.rglob("*.JPEG"):
+ _target = output_dir / _image_path.relative_to(source_dir)
+ _target.parent.mkdir(parents=True, exist_ok=True)
+ with Image.open(_image_path) as _image:
+ _image.resize((64, 64)).save(_target)
+
+ processed = wandb.Artifact("real-prepro", type="dataset")
+ processed.add_dir(str(output_dir))
+ processed_artifact = _run.log_artifact(processed)
+ processed_artifact.wait()
+ print(f"View preprocessing run: {_run.url}")
+ return (processed_artifact,)
@app.cell(hide_code=True)
def _():
mo.md(r"""
- > To apply a TTL policy to all artifacts within a team's projects, team admins can set default TTL policies for their team. The default will be applied to both existing and future artifacts logged to projects as long as no custom policies have been set. To learn more about configuring a team default TTL, visit [this](https://docs.wandb.ai/models/artifacts/ttl#set-default-ttl-policies-for-a-team) section of the W&B documentation.
- """)
- return
+ ## 7. Follow Lineage to Set Downstream TTL
+ TTL policies do not automatically propagate to derived artifacts. The next
+ cell fetches our source version and uses `used_by()` to find its consuming
+ runs. For each run, `logged_artifacts()` lists its outputs. We select dataset
+ outputs, then give them a 30-day TTL and save the changes.
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Traverse an Artifact Graph to Set Downstream TTL
- In this last section, we'll do some preprocessing on our images and log those as downstream Artifacts. Once again we'll use the W&B Import/Export API to set a TTL policy on our downstream images for images that originated from our "real" dataset.
+ This walks one hop downstream: source artifact, consuming run, output
+ artifacts. A longer pipeline would repeat this traversal for each output.
""")
return
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Preprocess and log a new Artifact
- """)
- return
-
-
-@app.function
-def preprocess_image(image_path):
- "Resize the image to 64x64"
- return Image.open(image_path).resize((64, 64))
-
-
-@app.function
-def preprocess_and_log_artifact(entity, project):
- with tempfile.TemporaryDirectory() as data_dir:
- real_prepro_dir = Path(data_dir) / "prepro" / "real"
- real_prepro_dir.mkdir(parents=True, exist_ok=True)
-
- with wandb.init(
- entity=entity,
- project=project,
- job_type="preprocessing",
- reinit="create_new",
- ) as run:
- real_art = run.use_artifact(f"{entity}/{project}/real-raw:latest")
- real_images = Path(
- real_art.download(root=Path(data_dir) / "real-raw")
- )
-
- for image_path in real_images.rglob("*.JPEG"):
- print(f"Preprocessing {image_path.name}")
- preprocessed_image = preprocess_image(image_path)
- preprocessed_image.save(real_prepro_dir / image_path.name)
-
- prepro_real_art = wandb.Artifact(
- "real-prepro",
- type="dataset",
- description="Preprocessed images from Imagenette",
- )
-
- prepro_real_art.add_dir(real_prepro_dir)
- logged_prepro_art = run.log_artifact(prepro_real_art)
- logged_prepro_art.wait()
- run_url = run.url
- return run_url
-
-
@app.cell
-def _(wandb_settings):
- preprocessing_run_url = preprocess_and_log_artifact(
- wandb_settings["entity"], wandb_settings["project"]
- )
+def _(compliant_artifact, processed_artifact):
+ # Referencing the uploaded output orders this cell after preprocessing.
+ print(f"Preprocessing complete: {processed_artifact.qualified_name}")
+ _api = wandb.Api()
+ _source = _api.artifact(compliant_artifact.qualified_name)
+ downstream_ttls = {}
+ for consumer in _source.used_by():
+ for _artifact in consumer.logged_artifacts():
+ if _artifact.type == "dataset" and _artifact.qualified_name not in downstream_ttls:
+ _artifact.ttl = timedelta(days=30)
+ _artifact.save()
+ downstream_ttls[_artifact.qualified_name] = _artifact.ttl
+ print(f"{_artifact.qualified_name}: {_artifact.ttl}")
return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- ### Traverse the Artifact Graph and Set TTL
- Let's take a look at the original real dataset and traverse downstream runs and Artifacts to set a TTL policy on anything that originated from the real dataset.
- """)
- return
-
+ ## Inspect the Policies in W&B
-@app.function
-def set_downstream_ttls(entity, project):
- api = wandb.Api()
-
- # For demo purposes we'll just do this on the latest version of the real dataset
- artifact = api.artifact(f"{entity}/{project}/real-raw:latest")
- consumer_runs = artifact.used_by()
-
- # Same pattern from above to get all downstream versions
- version_names = []
- for run in consumer_runs:
- for artifact in iter(run.logged_artifacts()):
- # filter for datasets only
- if artifact.type == "dataset":
- # Can be edited to just display individual elements
- version_names.append(artifact.qualified_name)
-
- unique_versions = sorted(set(version_names))
- changed_ttls = {}
- run_url = None
- if unique_versions:
- with wandb.init(
- entity=entity,
- project=project,
- job_type="modify-ttl",
- reinit="create_new",
- ) as run:
- for version in unique_versions:
- version_art = run.use_artifact(version)
- # set ttl to a random integer so we can see changes in the UI after we run this
- ttl_days = random.randint(1, 100)
- version_art.ttl = timedelta(days=ttl_days)
- version_art.save()
- changed_ttls[version] = ttl_days
- run_url = run.url
- return changed_ttls, run_url
+ Open the project link printed earlier and select **Artifacts**. Check the
+ versions and their TTL policies: `real-raw:extended` has 365 days,
+ `real-raw:compliant` and `fake-raw` have TTL deactivated, and downstream
+ datasets have 30 days. The lineage view shows the preprocessing relationship.
-
-@app.cell
-def _(wandb_settings):
- downstream_ttls, downstream_ttl_run_url = set_downstream_ttls(
- wandb_settings["entity"], wandb_settings["project"]
- )
+ The reusable pattern is to fetch a version, assign `artifact.ttl`, and call
+ `artifact.save()`. See the [TTL documentation](https://docs.wandb.ai/models/artifacts/ttl)
+ for permissions, team defaults, and expiration behavior.
+ """)
return
From a582d42502315d3bc5673dfe93b6ed2b9182550a Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Wed, 14 Oct 2026 11:02:00 -0700
Subject: [PATCH 06/48] Artifact TTL
---
..._artifacts_time_to_live_ttl_walkthrough.py | 40 +++++++++----------
1 file changed, 20 insertions(+), 20 deletions(-)
diff --git a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
index 39b949e8..fd913913 100644
--- a/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
+++ b/marimo/convert/wandb-artifacts-time-to-live-ttl-walkthrough/wandb_artifacts_time_to_live_ttl_walkthrough.py
@@ -61,7 +61,7 @@ def _():
@app.cell
def _():
- entity = "wandb"
+ entity = "your-entity"
project = "artifacts-ttl-demo"
authenticated = wandb.login()
if not authenticated:
@@ -100,12 +100,12 @@ def _():
# Validate archive entries before extracting downloaded files.
with tarfile.open(archive, "r:gz") as tar:
members = tar.getmembers()
- for _member in members:
- destination = (workspace / _member.name).resolve()
+ for member in members:
+ destination = (workspace / member.name).resolve()
if not destination.is_relative_to(workspace.resolve()):
- raise ValueError(f"Unsafe archive path: {_member.name}")
- if not (_member.isfile() or _member.isdir()):
- raise ValueError(f"Unsupported archive entry: {_member.name}")
+ raise ValueError(f"Unsafe archive path: {member.name}")
+ if not (member.isfile() or member.isdir()):
+ raise ValueError(f"Unsupported archive entry: {member.name}")
tar.extractall(workspace, members=members)
train_source_dir = workspace / "sample" / "train"
@@ -152,7 +152,7 @@ def _():
The next cell starts a run, creates dataset artifacts with
`wandb.Artifact()`, adds files with `add_dir()`, and sets a ten-day TTL
- before calling `run.log_artifact()`.
+ before calling `raw_data_run.log_artifact()`.
We create two versions of `real-raw`, with aliases `extended` and
`compliant`, so the next example can give them different policies. Different
@@ -168,26 +168,26 @@ def _():
@app.cell
def _(entity, project, train_source_dir, val_source_dir):
- with wandb.init(entity=entity, project=project, job_type="raw-data") as _run:
+ with wandb.init(entity=entity, project=project, job_type="raw-data") as raw_data_run:
extended = wandb.Artifact("real-raw", type="dataset")
extended.add_dir(str(train_source_dir), name="extended-snapshot")
extended.ttl = timedelta(days=10)
- logged_extended = _run.log_artifact(extended, aliases=["extended"])
+ logged_extended = raw_data_run.log_artifact(extended, aliases=["extended"])
logged_extended.wait()
compliant = wandb.Artifact("real-raw", type="dataset")
compliant.add_dir(str(train_source_dir), name="compliant-snapshot")
compliant.ttl = timedelta(days=10)
- logged_compliant = _run.log_artifact(compliant, aliases=["compliant", "latest"])
+ logged_compliant = raw_data_run.log_artifact(compliant, aliases=["compliant", "latest"])
logged_compliant.wait()
fake = wandb.Artifact("fake-raw", type="dataset")
fake.add_dir(str(val_source_dir))
fake.ttl = timedelta(days=10)
- logged_fake = _run.log_artifact(fake)
+ logged_fake = raw_data_run.log_artifact(fake)
logged_fake.wait()
- project_path = f"{_run.entity}/{_run.project}"
+ project_path = f"{raw_data_run.entity}/{raw_data_run.project}"
raw_alias_paths = {
"extended": f"{project_path}/real-raw:extended",
"compliant": f"{project_path}/real-raw:compliant",
@@ -265,8 +265,8 @@ def _():
The next cell consumes the `compliant` version of `real-raw`, resizes its
images to 64 by 64 pixels, and logs a new `real-prepro` artifact.
- `run.use_artifact()` records the input relationship, and
- `run.log_artifact()` records the output. Together they give W&B a lineage
+ `preprocessing_run.use_artifact()` records the input relationship, and
+ `preprocessing_run.log_artifact()` records the output. Together they give W&B a lineage
graph connecting the source data, preprocessing run, and processed data.
""")
return
@@ -277,8 +277,8 @@ def _(compliant_artifact, entity, project, workspace):
with tempfile.TemporaryDirectory(dir=workspace) as _data_dir:
output_dir = Path(_data_dir) / "processed"
output_dir.mkdir()
- with wandb.init(entity=entity, project=project, job_type="preprocessing") as _run:
- source = _run.use_artifact(compliant_artifact.qualified_name)
+ with wandb.init(entity=entity, project=project, job_type="preprocessing") as preprocessing_run:
+ source = preprocessing_run.use_artifact(compliant_artifact.qualified_name)
source_dir = Path(source.download(root=str(Path(_data_dir) / "raw")))
for _image_path in source_dir.rglob("*.JPEG"):
_target = output_dir / _image_path.relative_to(source_dir)
@@ -288,9 +288,9 @@ def _(compliant_artifact, entity, project, workspace):
processed = wandb.Artifact("real-prepro", type="dataset")
processed.add_dir(str(output_dir))
- processed_artifact = _run.log_artifact(processed)
+ processed_artifact = preprocessing_run.log_artifact(processed)
processed_artifact.wait()
- print(f"View preprocessing run: {_run.url}")
+ print(f"View preprocessing run: {preprocessing_run.url}")
return (processed_artifact,)
@@ -317,8 +317,8 @@ def _(compliant_artifact, processed_artifact):
_api = wandb.Api()
_source = _api.artifact(compliant_artifact.qualified_name)
downstream_ttls = {}
- for consumer in _source.used_by():
- for _artifact in consumer.logged_artifacts():
+ for consumer_run in _source.used_by():
+ for _artifact in consumer_run.logged_artifacts():
if _artifact.type == "dataset" and _artifact.qualified_name not in downstream_ttls:
_artifact.ttl = timedelta(days=30)
_artifact.save()
From 2121b45523cdcd900ff44c0c72a6e44279f01138 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Wed, 14 Oct 2026 11:45:04 -0700
Subject: [PATCH 07/48] tables quickstart
---
.../w_b_tables_quickstart.py | 490 +++++++-----------
1 file changed, 195 insertions(+), 295 deletions(-)
diff --git a/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py b/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
index 70d6e3ca..22e4ac46 100644
--- a/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
+++ b/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
@@ -1,5 +1,7 @@
# /// script
+# requires-python = ">=3.10"
# dependencies = [
+# "marimo>=0.24",
# "torch==2.14.0",
# "torchvision==0.29.0",
# "wandb==0.30.0",
@@ -8,8 +10,8 @@
import marimo
-__generated_with = "0.24.0"
-app = marimo.App(auto_download=["html"])
+__generated_with = "0.25.1"
+app = marimo.App(width="medium", app_title="W&B Tables Quickstart")
with app.setup:
import marimo as mo
@@ -21,8 +23,6 @@
import torchvision.transforms as T
import wandb
- WANDB_PROJECT = "table-quickstart"
-
@app.cell(hide_code=True)
def _():
@@ -30,13 +30,7 @@ def _():
# View & analyze model predictions during training
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py/server)
- """)
- return
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
+ Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ your runtime's environment or **Secrets** panel. Locally, you can also run
+ `wandb login` in a terminal. A hosted runtime needs its own credentials.
- ## Why should I use W&B?
-
-
-
-
- Use Weights & Biases for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-
+ Set `entity` to your Weights & Biases team slug, or leave it as `None` to use your default
+ entity. The slug appears in `wandb.ai//`. Choose a project
+ to group your experiments.
""")
return
-@app.cell(hide_code=True)
+@app.cell
def _():
- mo.md(r"""
- ## Authentication
-
- Enter your [W&B API key](https://wandb.ai/authorize), or leave it blank to use
- `WANDB_API_KEY` from the marimo Secrets panel or credentials already stored
- in this runtime. A fresh molab session does not inherit your local login.
- If needed, [create a free W&B account](https://wandb.ai/signup).
-
- The entity is the team name in your W&B project URL:
- `wandb.ai//`. Leave it blank to use your default entity.
- A blank run name lets W&B generate a name for each experiment.
-
- Submit the form to authenticate, download data and weights, create one W&B
- run, and train the model. The callback streams training and validation metrics to that run.
- """)
- return
+ entity = None
+ project = "intro-keras"
+ wandb.login()
+ return entity, project
@app.cell(hide_code=True)
def _():
- training_form = (
- mo.md(
- """
- {api_key}
-
- {entity}
-
- {project}
-
- {run_name}
-
- ## Hyperparameters
-
- A Python dictionary records these hyperparameters in the W&B run
- config so experiments can be compared and reproduced.
-
- {epochs} {batch_size}
-
- {learning_rate}
- """
- )
- .batch(
- api_key=mo.ui.text(kind="password", label="W&B API key (optional)", full_width=True),
- entity=mo.ui.text(label="W&B entity or team (optional)", full_width=True),
- project=mo.ui.text(value="intro-keras", label="W&B project", full_width=True),
- run_name=mo.ui.text(label="Run name (blank auto-generates)", full_width=True),
- epochs=mo.ui.number(start=1, stop=50, step=1, value=10, label="Epochs"),
- batch_size=mo.ui.dropdown(options=[32, 64, 128, 256], value=64, label="Batch size"),
- learning_rate=mo.ui.number(start=0.00001, stop=0.1, step=0.00001, value=0.001, label="Learning rate"),
- )
- .form(submit_button_label="Download data and train with W&B", bordered=True)
- )
- training_form
- return (training_form,)
-
+ mo.md(r"""
+ ## Hyperparameters
-@app.cell(hide_code=True)
-def _(training_form):
- mo.stop(
- training_form.value is None,
- mo.callout(mo.md("Submit the form above to download data and train."), kind="info"),
- )
- _submitted = training_form.value
- mo.stop(
- not _submitted["project"].strip(),
- mo.callout(mo.md("Enter a W&B project name and submit again."), kind="danger"),
- )
- _api_key = _submitted["api_key"].strip()
- try:
- _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
- except (wandb.errors.Error, ValueError):
- _login_ok = False
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md("W&B authentication did not complete. Check your API key or runtime secret, then submit again."),
- kind="danger",
- ),
- )
- wandb_settings = {
- "project": _submitted["project"].strip(),
- "entity": _submitted["entity"].strip() or None,
- "name": _submitted["run_name"].strip() or None,
- }
- training_request = {
- "epochs": int(_submitted["epochs"]),
- "batch_size": int(_submitted["batch_size"]),
- "learning_rate": float(_submitted["learning_rate"]),
- }
- mo.callout(mo.md("Authenticated. Preparing the submitted training run."), kind="success")
- return training_request, wandb_settings
+ Use a Python dictionary to define the experiment. Passing it to
+ `wandb.init(config=configs)` records these settings with the run, so you
+ can compare experiments and reproduce the model's configuration.
+ """)
+ return
@app.cell
-def _(training_request):
+def _():
configs = dict(
dataset="fashion_mnist",
num_classes=10,
shuffle_buffer=1024,
- batch_size=training_request["batch_size"],
+ batch_size=64,
image_size=28,
image_channels=1,
- learning_rate=training_request["learning_rate"],
- epochs=training_request["epochs"],
+ learning_rate=0.001,
+ epochs=10,
seed=42,
)
return (configs,)
@@ -190,6 +101,8 @@ def _():
pipeline. Labels become one-hot vectors; images keep their 0–255 range
until the model applies MobileNetV2 preprocessing. Validation examples stay
in a fixed order.
+
+ The data-loading helpers are defined at the end of the notebook.
""")
return
@@ -240,8 +153,8 @@ def _():
Adam uses the learning rate recorded in `configs`. Alongside cross-entropy
loss, track accuracy and top-five accuracy on training and validation data.
- The same cell creates and compiles the model so training always receives a
- fresh, compiled model after a new submission.
+ Rerun this cell before each new experiment to start with a fresh model.
+ Rerunning only the training cell continues from the current model weights.
""")
return
@@ -268,7 +181,7 @@ def _():
mo.md(r"""
## Train
- Initialize W&B before constructing `WandbMetricsLogger`, then pass the
+ Initialize Weights & Biases before constructing `WandbMetricsLogger`, then pass the
callback to `model.fit`. `log_freq=10` logs training metrics every ten
batches; epoch and validation metrics are also logged at epoch end. Use
`log_freq="epoch"` for epoch-only logging or `"batch"` for every batch.
@@ -280,41 +193,33 @@ def _():
@app.cell
-def _(configs, model, trainloader, validloader, wandb_settings):
- if wandb.run is not None:
- wandb.run.finish()
-
- # Initialize a W&B run
- with wandb.init(**wandb_settings, config=configs) as training_run:
- wandb_run_url = training_run.url
- # Train your model
- training_history = model.fit(
+def _(configs, entity, model, project, trainloader, validloader):
+ with wandb.init(entity=entity, project=project, config=configs):
+ history = model.fit(
trainloader,
epochs=configs["epochs"],
validation_data=validloader,
shuffle=False, # The tf.data training pipeline already shuffles.
- callbacks=[WandbMetricsLogger(log_freq=10)], # Notice the use of WandbMetricsLogger here
+ callbacks=[WandbMetricsLogger(log_freq=10)],
)
- # Close the W&B run
- training_result = {
- "url": wandb_run_url,
- "epochs": len(training_history.history["loss"]),
- }
- return (training_result,)
+ return
@app.cell(hide_code=True)
-def _(training_result):
- mo.callout(
- mo.md(
- f"Training finished after {training_result['epochs']} epochs. "
- f"[Open the W&B run]({training_result['url']}).\n\n"
- "In the run's Workspace, inspect `epoch/loss`, `epoch/accuracy`, "
- "`epoch/val_loss`, and `epoch/val_accuracy`, then compare the "
- "`batch/*` charts. Check Config for the batch size and learning rate."
- ),
- kind="success",
- )
+def _():
+ mo.md(r"""
+ ## Explore your results
+
+ Open the run link printed by Weights & Biases. In the run's Workspace, inspect
+ `epoch/loss`, `epoch/accuracy`, `epoch/val_loss`, and `epoch/val_accuracy`.
+ Compare these epoch summaries with the more frequent `batch/*` metrics.
+ Check Config for the batch size and learning rate recorded with the run.
+
+ Try a different learning rate in `configs`, rebuild the model with the
+ compile cell, and train again. Compare validation loss and accuracy across
+ the two runs in your project. You can also change `log_freq` to see how
+ logging frequency affects the detail in your training charts.
+ """)
return
@@ -333,7 +238,6 @@ def _():
def parse_data(example, num_classes):
# Get image
image = example["image"]
- # image = tf.image.convert_image_dtype(image, dtype=tf.float32)
image = tf.cast(image, tf.float32)
# Get label
From 2d6542291b400a8a039c44de22fb0c1b461aacee Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 13:34:27 -0700
Subject: [PATCH 25/48] undo markdown cell hidden
---
.../marimo/mnist-registry/mnist_registry.py | 6 ++--
.../alphafold_with_w_b_align_fold_log.py | 14 ++++----
.../convert/configs-in-w-b/configs_in_w_b.py | 16 +++++-----
.../credit_scorecards_with_xgboost_and_w_b.py | 22 ++++++-------
.../custom_progress_callback.py | 30 ++++++++---------
.../huggingface-wandb/huggingface_wandb.py | 12 +++----
...mization_in_tensorflow_using_w_b_sweeps.py | 22 ++++++-------
.../intro_to_weights_biases_keras.py | 18 +++++------
.../intro_to_weights_biases.py | 16 +++++-----
marimo/convert/lcm-diffusers/lcm_diffusers.py | 6 ++--
.../log_a_confusion_matrix_with_w_b.py | 14 ++++----
.../log_almost_anything_with_w_b_media.py | 26 +++++++--------
...hugging_face_models_with_weights_biases.py | 32 +++++++++----------
...ch_lightning_models_with_weights_biases.py | 20 ++++++------
...perparameter_sweeps_in_pytorch_with_w_b.py | 24 +++++++-------
.../plot_roc_curves_with_w_b.py | 10 +++---
.../report_api_quickstart.py | 26 +++++++--------
.../simple_pytorch_integration.py | 26 +++++++--------
.../torchtune_and_wandb.py | 10 +++---
...debug_yolov5_models_with_weights_biases.py | 16 +++++-----
...andbevalcallback_in_your_keras_workflow.py | 18 +++++------
...bmodelcheckpoint_in_your_keras_workflow.py | 18 +++++------
.../using_w_b_sweeps_with_xgboost.py | 6 ++--
.../w_b_tables_quickstart.py | 14 ++++----
..._artifacts_time_to_live_ttl_walkthrough.py | 18 +++++------
25 files changed, 220 insertions(+), 220 deletions(-)
diff --git a/examples/marimo/mnist-registry/mnist_registry.py b/examples/marimo/mnist-registry/mnist_registry.py
index 689100c3..a12b973d 100644
--- a/examples/marimo/mnist-registry/mnist_registry.py
+++ b/examples/marimo/mnist-registry/mnist_registry.py
@@ -50,7 +50,7 @@
device_kind = "warn"
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
# MNIST -> W&B Run -> Registry
@@ -99,7 +99,7 @@ def _():
return
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## Configuration
@@ -523,7 +523,7 @@ def _(collection_name_v, registry_name_v, run):
return
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## Helper functions
diff --git a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
index 8dca612e..350c2d65 100644
--- a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
+++ b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
@@ -35,7 +35,7 @@
import wandb
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
# ColabFold with Weights & Biases: Align, Fold, Log
@@ -99,7 +99,7 @@ def _():
return inference_backend, runtime_ready
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## 2. Authenticate with Weights & Biases
@@ -126,7 +126,7 @@ def _():
return authenticated, entity, project
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## 3. Choose a Protein and Prediction Settings
@@ -252,7 +252,7 @@ def _(SEQUENCES):
)
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## 4. Align and Fold
@@ -359,7 +359,7 @@ def _(
return (fold_result,)
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## 5. Inspect Alignment and Confidence
@@ -523,7 +523,7 @@ def _(prediction_summary):
return
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## 6. Log the Prediction to Weights & Biases
@@ -630,7 +630,7 @@ def _(run_url):
return
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
## References
diff --git a/marimo/convert/configs-in-w-b/configs_in_w_b.py b/marimo/convert/configs-in-w-b/configs_in_w_b.py
index 8117a764..30be12ad 100644
--- a/marimo/convert/configs-in-w-b/configs_in_w_b.py
+++ b/marimo/convert/configs-in-w-b/configs_in_w_b.py
@@ -15,7 +15,7 @@
import wandb
-@app.cell(hide_code=True)
+@app.cell(hide_code=False)
def _():
mo.md(r"""
+ ## Set up your experiment
- ## Why should I use W&B?
+ Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ your runtime's environment or **Secrets** panel. Locally, you can also run
+ `wandb login` in a terminal. A hosted runtime needs its own credentials.
-
-
-
- Use Weights & Biases for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-
+ Set `entity` to your Weights & Biases team slug, or leave it as `None` to use your default
+ entity. The slug appears in `wandb.ai//`. Choose a project
+ to group your experiments.
""")
return
-@app.cell(hide_code=False)
+@app.cell
def _():
- mo.md(r"""
- ## Authentication
-
- Enter your [W&B API key](https://wandb.ai/authorize) and, if needed, your team or entity. You can leave the key blank when this environment already has W&B credentials. If this is your first time using W&B, [create a free account](https://wandb.ai/signup).
- """)
- return
+ entity = None
+ project = "intro-keras"
+ wandb.login()
+ return entity, project
@app.cell(hide_code=True)
-def _():
- _api_key_input = mo.ui.text(
- kind="password",
- label="W&B API key (optional)",
- placeholder="Paste a key or use cached credentials",
- full_width=True,
- )
- _entity_input = mo.ui.text(
- label="W&B entity or team (optional)",
- placeholder="Leave blank to use your default entity",
- full_width=True,
- )
- wandb_login_form = (
- mo.md("{api_key}\n\n{entity}")
- .batch(api_key=_api_key_input, entity=_entity_input)
- .form(submit_button_label="Connect to W&B", bordered=True)
- )
- wandb_login_form
- return (wandb_login_form,)
-
-
-@app.cell(hide_code=True)
-def _(wandb_login_form):
- mo.stop(
- wandb_login_form.value is None,
- mo.callout(
- mo.md("Connect to W&B above before preparing data or training the model."),
- kind="info",
- ),
- )
-
- _api_key = wandb_login_form.value["api_key"].strip()
- _entity = wandb_login_form.value["entity"].strip()
- try:
- _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
- _login_error = None
- except wandb.errors.Error as _error:
- _login_ok = False
- _login_error = str(_error)
-
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md(
- "W&B authentication did not complete. "
- f"Check the API key and try again.\n\nW&B reported: `{_login_error or 'unknown error'}`"
- ),
- kind="danger",
- ),
- )
-
- wandb_settings = {
- "project": "intro-keras",
- "entity": _entity or None,
- }
- mo.callout(mo.md("Connected to W&B."), kind="success")
- return (wandb_settings,)
-
-
-@app.cell(hide_code=False)
def _():
mo.md(r"""
## Hyperparameters
- Use of a proper config system is a recommended best practice for reproducible machine learning. We can track the hyperparameters for every experiment using W&B. In this notebook we use a simple Python `dict` as our config system.
-
- Choose the training values below. Submitting the form downloads Fashion-MNIST and ImageNet weights, starts a W&B run, trains the model, and logs model checkpoints.
+ Use a Python dictionary to define the experiment. Passing it to
+ `wandb.init(config=configs)` records these settings with the run, so you
+ can compare experiments and reproduce the model's configuration.
""")
return
-@app.cell(hide_code=True)
-def _():
- _epochs_input = mo.ui.number(
- start=1,
- stop=50,
- step=1,
- value=10,
- label="Epochs",
- )
- _batch_size_input = mo.ui.number(
- start=16,
- stop=256,
- step=16,
- value=64,
- label="Batch size",
- )
- training_form = (
- mo.md("{epochs}\n\n{batch_size}")
- .batch(epochs=_epochs_input, batch_size=_batch_size_input)
- .form(submit_button_label="Download data and train with W&B", bordered=True)
- )
- training_form
- return (training_form,)
-
-
-@app.cell(hide_code=True)
-def _(training_form, wandb_settings):
- mo.stop(
- training_form.value is None,
- mo.callout(
- mo.md("Choose the hyperparameters and submit the form to continue."),
- kind="info",
- ),
- )
- mo.stop(
- not wandb_settings,
- mo.callout(mo.md("Connect to W&B before training."), kind="info"),
- )
- training_request = dict(training_form.value)
- return (training_request,)
-
-
@app.cell
-def _(training_request):
+def _():
configs = dict(
dataset="fashion_mnist",
num_classes=10,
shuffle_buffer=1024,
- batch_size=int(training_request["batch_size"]),
+ batch_size=64,
image_size=28,
image_channels=1,
- earlystopping_patience=3,
- learning_rate=1e-3,
- epochs=int(training_request["epochs"]),
+ learning_rate=0.001,
+ epochs=10,
+ seed=42,
)
return (configs,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Dataset
- In this notebook, we use the [Fashion-MNIST](https://www.tensorflow.org/datasets/catalog/fashion_mnist) dataset from the TensorFlow Datasets catalog. We aim to build a simple image classification pipeline using TensorFlow/Keras.
+ We use [Fashion-MNIST](https://www.tensorflow.org/datasets/catalog/fashion_mnist)
+ from the TensorFlow Datasets catalog to build a simple image classification
+ pipeline. Labels become one-hot vectors; images keep their 0–255 range
+ until the model applies MobileNetV2 preprocessing. Validation examples stay
+ in a fixed order.
+
+ The data-loading helpers are defined at the end of the notebook.
""")
return
@app.cell
def _(configs):
- train_ds, valid_ds = tfds.load(
- configs["dataset"],
- split=["train", "test"],
- )
- return train_ds, valid_ds
-
-
-@app.cell
-def _(configs):
- AUTOTUNE = tf.data.AUTOTUNE
-
-
- def parse_data(example):
- # Get image
- image = example["image"]
- # image = tf.image.convert_image_dtype(image, dtype=tf.float32)
-
- # Get label
- label = example["label"]
- label = tf.one_hot(label, depth=configs["num_classes"])
-
- return image, label
-
-
- def get_dataloader(ds, configs, dataloader_type="train"):
- dataloader = ds.map(parse_data, num_parallel_calls=AUTOTUNE)
-
- if dataloader_type=="train":
- dataloader = dataloader.shuffle(configs["shuffle_buffer"])
-
- dataloader = (
- dataloader
- .batch(configs["batch_size"])
- .prefetch(AUTOTUNE)
- )
-
- return dataloader
-
- return (get_dataloader,)
-
-
-@app.cell
-def _(configs, get_dataloader, train_ds, valid_ds):
+ train_ds, valid_ds = tfds.load(configs["dataset"], split=["train", "test"])
trainloader = get_dataloader(train_ds, configs)
validloader = get_dataloader(valid_ds, configs, dataloader_type="valid")
return trainloader, validloader
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Model
+
+ A frozen ImageNet MobileNetV2 supplies image features. The model resizes each
+ grayscale image to 32 × 32, learns a three-channel convolution, applies
+ MobileNetV2 preprocessing, and trains a ten-class classification head.
""")
return
@app.function
-def get_model(configs):
- backbone = tf.keras.applications.mobilenet_v2.MobileNetV2(weights='imagenet', include_top=False)
+def get_model(configs, weights="imagenet"):
+ backbone = tf.keras.applications.mobilenet_v2.MobileNetV2(
+ weights=weights, include_top=False
+ )
backbone.trainable = False
- inputs = layers.Input(shape=(configs["image_size"], configs["image_size"], configs["image_channels"]))
+ inputs = layers.Input(
+ shape=(configs["image_size"], configs["image_size"], configs["image_channels"])
+ )
resize = layers.Resizing(32, 32)(inputs)
- neck = layers.Conv2D(3, (3,3), padding="same")(resize)
- preprocess_input = tf.keras.applications.mobilenet.preprocess_input(neck)
- x = backbone(preprocess_input)
+ neck = layers.Conv2D(3, (3, 3), padding="same")(resize)
+ preprocess_input = tf.keras.applications.mobilenet_v2.preprocess_input(neck)
+ x = backbone(preprocess_input, training=False)
x = layers.GlobalAveragePooling2D()(x)
outputs = layers.Dense(configs["num_classes"], activation="softmax")(x)
-
return models.Model(inputs=inputs, outputs=outputs)
-@app.cell
-def _(configs):
- tf.keras.backend.clear_session()
- model = get_model(configs)
- model.summary()
- return (model,)
-
-
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Compile model
+
+ Adam uses the learning rate recorded in `configs`. Alongside cross-entropy
+ loss, track accuracy and top-five accuracy on training and validation data.
+ Rerun this cell before each new experiment to start with a fresh model.
+ Rerunning only the training cell continues from the current model weights.
""")
return
@app.cell
-def _(model):
+def _(configs):
+ tf.keras.utils.set_random_seed(configs["seed"])
+ model = get_model(configs)
model.compile(
- optimizer="adam",
+ optimizer=tf.keras.optimizers.Adam(learning_rate=configs["learning_rate"]),
loss="categorical_crossentropy",
metrics=[
"accuracy",
tf.keras.metrics.TopKCategoricalAccuracy(k=5, name="top@5_accuracy"),
],
)
- compiled_model = model
- return (compiled_model,)
+ model.summary()
+ return (model,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train
- The submitted action creates a W&B run, trains the classifier, logs its metrics, and saves each model checkpoint to W&B Artifacts.
+ Initialize Weights & Biases before constructing the callbacks, then pass
+ them to `model.fit`:
+
+ - `WandbMetricsLogger(log_freq=10)` logs training metrics every ten batches,
+ plus epoch and validation metrics at the end of each epoch.
+ - `WandbModelCheckpoint` saves the full model to `models/model.keras` at
+ the end of each epoch and logs it as a Weights & Biases Artifact of type `model`.
+ The `.keras` file includes the model architecture, weights, and optimizer
+ state, so it can be loaded with `tf.keras.models.load_model`.
+
+ The local file is overwritten each epoch. Weights & Biases versions the checkpoints
+ under the run's model artifact, so you can inspect earlier versions.
+
+ The context manager finishes the run after training, including if training
+ raises an exception.
""")
return
@app.cell
-def _(compiled_model, configs, trainloader, validloader, wandb_settings):
+def _(configs, entity, model, project, trainloader, validloader):
os.makedirs("models", exist_ok=True)
- if wandb.run is not None:
- wandb.finish()
-
- # Initialize a W&B run
- with wandb.init(
- project=wandb_settings["project"],
- entity=wandb_settings["entity"],
- config=configs,
- ) as _run:
- wandb_run_url = _run.url
- mo.output.replace(
- mo.callout(
- mo.md(
- f"[**Open this training run in W&B**]({wandb_run_url})\n\n"
- "Metrics will stream to W&B while the model trains."
- ),
- kind="info",
- title="Training in progress",
- )
- )
-
- # Train your model
- training_history = compiled_model.fit(
+ with wandb.init(entity=entity, project=project, config=configs):
+ history = model.fit(
trainloader,
epochs=configs["epochs"],
validation_data=validloader,
+ shuffle=False, # The tf.data training pipeline already shuffles.
callbacks=[
WandbMetricsLogger(log_freq=10),
- # Notice the use of WandbModelCheckpoint here
- WandbModelCheckpoint(filepath="models/model.keras"),
+ WandbModelCheckpoint(
+ filepath="models/model.keras",
+ save_freq="epoch",
+ ),
],
)
+ return
- mo.output.replace(None)
- return (wandb_run_url,)
+
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ## Explore your results
+
+ Open the run link printed by Weights & Biases. In the run's **Artifacts**
+ tab, find the artifact of type `model` and inspect its versions. Each version
+ contains a `model.keras` checkpoint; the `latest` alias points to the latest
+ version. In the **Workspace**, inspect `epoch/loss`, `epoch/val_loss`, and
+ `epoch/val_accuracy`. Check **Config** for the hyperparameters used to
+ produce these checkpoints.
+
+ To keep a separate local checkpoint for each epoch, change `filepath` to
+ `"models/model-{epoch:02d}.keras"`. Rebuild the model with the compile cell
+ and train again, then compare the local files with the Weights & Biases Artifact versions.
+ """)
+ return
@app.cell(hide_code=True)
-def _(wandb_run_url):
- mo.callout(
- mo.md(f"""
- ### Training complete
+def _():
+ mo.md(r"""
+ ## Helper functions
+
+ The input pipeline maps images and labels, shuffles only training examples,
+ then batches and prefetches them.
+ """)
+ return
- [**Open this training run in W&B**]({wandb_run_url})
- Open the run's **Artifacts** tab to inspect the model checkpoints logged by `WandbModelCheckpoint`.
- """),
- kind="success",
+@app.function
+def parse_data(example, num_classes):
+ # Get image
+ image = example["image"]
+ image = tf.cast(image, tf.float32)
+
+ # Get label
+ label = example["label"]
+ label = tf.one_hot(label, depth=num_classes)
+ return image, label
+
+
+@app.function
+def get_dataloader(ds, configs, dataloader_type="train"):
+ dataloader = ds.map(
+ lambda example: parse_data(example, configs["num_classes"]),
+ num_parallel_calls=tf.data.AUTOTUNE,
)
- return
+ if dataloader_type == "train":
+ dataloader = dataloader.shuffle(configs["shuffle_buffer"], seed=configs["seed"])
+ return dataloader.batch(configs["batch_size"]).prefetch(tf.data.AUTOTUNE)
if __name__ == "__main__":
From b3332b33ab658b107b5867e127990c271b7d3fad Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 18:20:52 -0700
Subject: [PATCH 27/48] using sweeps xgboost
---
.../using_w_b_sweeps_with_xgboost.py | 576 +++++-------------
1 file changed, 150 insertions(+), 426 deletions(-)
diff --git a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
index c622785d..5d36f273 100644
--- a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
+++ b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
@@ -5,23 +5,26 @@
# "numpy>=1.26",
# "scikit-learn>=1.5",
# "wandb>=0.18",
-# "xgboost>=2.1",
+# "xgboost>=2.1,<3.3", # Preserve the tree-versus-linear booster lesson.
# ]
+#
+# [tool.marimo.runtime]
+# on_cell_change = "lazy"
# ///
import marimo
-__generated_with = "0.24.0"
+__generated_with = "0.25.1"
app = marimo.App(width="medium", app_title="W&B Sweeps with XGBoost")
-
-with app.setup():
+with app.setup:
from urllib.request import urlopen
import marimo as mo
from numpy import loadtxt
from sklearn.metrics import accuracy_score
from sklearn.model_selection import train_test_split
+ from xgboost import XGBClassifier
import wandb
DATASET_URL = (
@@ -31,252 +34,65 @@
@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py/server)
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
-
-
- Use Weights & Biases for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- # Using W&B Sweeps with XGBoost
-
- Squeezing the best performance out of tree-based models requires
- [selecting the right hyperparameters](https://blog.cambridgespark.com/hyperparameter-tuning-in-xgboost-4ff9100a3b2f).
- How many `early_stopping_rounds`? What should the `max_depth` of a tree be?
-
- Searching through high dimensional hyperparameter spaces to find the most performant model can get unwieldy very fast.
- Hyperparameter sweeps provide an organized and efficient way to conduct a battle royale of models and crown a winner.
- They enable this by automatically searching through combinations of hyperparameter values to find the most optimal values.
-
- In this tutorial we'll see how you can run sophisticated hyperparameter sweeps on XGBoost models in 3 easy steps using Weights and Biases.
-
- For a teaser, check out the plots below:
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- 
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
- ## Sweeps: An Overview
+ # Using Weights & Biases Sweeps with XGBoost
- Running a hyperparameter sweep with Weights & Biases is very easy. There are just 3 simple steps:
+ [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py/server)
- 1. **Define the sweep:** we do this by creating a dictionary-like object that specifies the sweep: which parameters to search through, which search strategy to use, which metric to optimize.
+ Hyperparameter sweeps search combinations of model settings and record
+ their performance. In this lesson, compare XGBoost's tree and linear
+ boosters while exploring learning rate, tree depth, and row sampling.
- 2. **Initialize the sweep:** with one line of code we initialize the sweep and pass in the dictionary of sweep configurations:
- `sweep_id = wandb.sweep(sweep_config)`
+ There are three steps:
- 3. **Run the sweep agent:** also accomplished with one line of code, we call `wandb.agent()` and pass the `sweep_id` along with a function that defines your model architecture and trains it:
- `wandb.agent(sweep_id, function=train)`
+ 1. **Define the sweep:** choose the search strategy, parameters, and metric.
+ 2. **Initialize the sweep:** register the configuration with `wandb.sweep`.
+ 3. **Run an agent:** call `wandb.agent` with a training function and run count.
- And voila! That's all there is to running a hyperparameter sweep!
+ This notebook runs on a CPU. On macOS, install the OpenMP runtime with
+ `brew install libomp` before starting the notebook if it is not installed.
- In the notebook below, we'll walk through these 3 steps in more detail.
+ ## Set up your experiment
- We highly encourage you to fork this notebook, tweak the parameters, or try the model with your own dataset!
+ Get your [Weights & Biases API key](https://wandb.ai/authorize) and set
+ `WANDB_API_KEY` in your runtime's environment or **Secrets** panel. Locally,
+ you can also run `wandb login` in a terminal. A hosted runtime needs its
+ own credentials.
- ### Resources
- - [Sweeps docs →](https://docs.wandb.com/library/sweeps)
- - [Launching from the command line →](https://www.wandb.com/articles/hyperparameter-tuning-as-easy-as-1-2-3)
+ Set `entity` to your team slug, or leave it as `None` to use your default
+ entity. The slug appears in `wandb.ai//`.
+ This lesson needs an online connection to the Weights & Biases sweep service.
""")
return
-@app.cell(hide_code=False)
+@app.cell
def _():
- mo.md(r"""
- ## Authentication
-
- To run this tutorial, authenticate with W&B and choose where to create the
- sweep. Get an API key from [wandb.ai/authorize](https://wandb.ai/authorize),
- or leave the key blank to use `WANDB_API_KEY` from marimo's Secrets panel,
- an existing W&B settings file, or a prior `wandb login` in this runtime.
-
- If you work in a team, enter its entity slug. You can find it in the URL of
- your team's W&B workspace; leave it blank to use your default entity.
-
- When running locally on macOS, XGBoost also needs the OpenMP runtime. Install
- it once with `brew install libomp`. Hosted Linux environments generally
- provide the required runtime with the XGBoost wheel.
-
- Submitting the form creates a new Sweep Controller and then starts the
- requested number of W&B runs. Editing fields without submitting does not
- create anything in W&B. Editing the `sweep_config` or `train` code below
- resets the form so you can review and submit those changes explicitly.
- Submitting again creates and runs a new sweep.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(sweep_config, train):
- # Check the native XGBoost runtime before creating a Sweep Controller.
- # On macOS, the XGBoost wheel requires libomp from Homebrew.
- try:
- from xgboost import XGBClassifier as _XGBClassifier # noqa: F401
- except (ImportError, OSError, ValueError) as _error:
- _xgboost_error = str(_error)
- else:
- _xgboost_error = None
-
- _macos_help = (
- " On macOS, run `brew install libomp`, then restart this notebook."
- if "libomp.dylib" in (_xgboost_error or "")
- else ""
- )
- mo.stop(
- _xgboost_error is not None,
- mo.callout(
- mo.md(
- "**XGBoost could not load its native runtime.**"
- f"{_macos_help}\n\n"
- "The sweep has not been created, so fixing the runtime and "
- "resubmitting will not leave failed runs behind."
- ),
- kind="danger",
- ),
- )
-
- _api_key_input = mo.ui.text(
- value="",
- kind="password",
- label="W&B API key (blank uses runtime credentials)",
- )
- _entity_input = mo.ui.text(
- value="",
- label="W&B entity (blank uses your default)",
- )
- _project_input = mo.ui.text(value="XGBoost-sweeps", label="W&B project")
- _run_count_input = mo.ui.number(
- start=1,
- stop=50,
- value=25,
- step=1,
- label="Number of sweep runs",
- )
-
- sweep_form = (
- mo.md(
- """
- {api_key}
-
- {entity}
-
- {project}
-
- {run_count}
- """
- )
- .batch(
- api_key=_api_key_input,
- entity=_entity_input,
- project=_project_input,
- run_count=_run_count_input,
- )
- .form(
- submit_button_label="Create sweep and run agent",
- bordered=False,
- )
- )
-
- mo.vstack(
- [
- mo.md(
- f"Ready to submit a `{sweep_config['method']}` sweep using "
- f"the `{train.__name__}` training function."
- ),
- sweep_form,
- ]
- )
- return (sweep_form,)
+ entity = None
+ project = "XGBoost-sweeps"
+ wandb.login()
+ return entity, project
@app.cell(hide_code=True)
-def _(sweep_form):
- mo.stop(
- sweep_form.value is None,
- mo.md(
- "Review the sweep configuration below, then submit the form above "
- "when you are ready to create the Sweep Controller and launch its runs."
- ),
- )
-
- _submitted = sweep_form.value
- _api_key = _submitted["api_key"].strip()
- try:
- _login_ok = wandb.login(
- key=_api_key or None,
- relogin=bool(_api_key),
- )
- _login_error = None
- except wandb.errors.Error as _error:
- _login_ok = False
- _login_error = str(_error)
-
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md(
- "W&B authentication did not complete. "
- f"Check the API key and try again.\n\nW&B reported: `{_login_error or 'unknown error'}`"
- ),
- kind="danger",
- ),
- )
-
- sweep_request = {
- "entity": _submitted["entity"].strip() or None,
- "project": _submitted["project"].strip() or "XGBoost-sweeps",
- "run_count": int(_submitted["run_count"]),
- }
- mo.callout(
- mo.md("Connected to W&B. The submitted sweep will start now."),
- kind="success",
- )
- return (sweep_request,)
-
-
-@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
- ## 1. Define the Sweep
+ ## Define the sweep
- Weights & Biases sweeps give you powerful levers to configure your sweeps exactly how you want them, with just a few lines of code. The sweeps config can be defined as
- [a dictionary or a YAML file](https://docs.wandb.ai/guides/sweeps/configuration).
+ A sweep configuration can be a [Python dictionary or YAML file](https://docs.wandb.ai/models/sweeps/define-sweep-configuration).
+ Here we use a dictionary with three main fields:
- Let's walk through some of them together:
- * **Metric** – This is the metric the sweeps are attempting to optimize. Metrics can take a `name` (this metric should be logged by your training script) and a `goal` (`maximize` or `minimize`).
- * **Search Strategy** – Specified using the `"method"` key. We support several different search strategies with sweeps.
- * **Grid Search** – Iterates over every combination of hyperparameter values.
- * **Random Search** – Iterates over randomly chosen combinations of hyperparameter values.
- * **Bayesian Search** – Creates a probabilistic model that maps hyperparameters to probability of a metric score, and chooses parameters with high probability of improving the metric. The objective of Bayesian optimization is to spend more time in picking the hyperparameter values, but in doing so trying out fewer hyperparameter values.
- * **Parameters** – A dictionary containing the hyperparameter names, and discrete values, a range, or distributions from which to pull their values on each iteration.
+ - **Metric:** the logged metric to optimize and whether to maximize or
+ minimize it. Our training function logs validation accuracy as `accuracy`.
+ - **Method:** `random` samples combinations, `grid` tries every combination,
+ and `bayes` uses previous results to choose promising settings.
+ - **Parameters:** the values, ranges, or distributions to search.
- You can find a list of all configuration options [here](https://docs.wandb.com/library/sweeps/configuration).
+ Both boosters use `learning_rate`. The [tree parameters](https://xgboost.readthedocs.io/en/stable/parameter.html#parameters-for-tree-booster)
+ `max_depth` and `subsample` affect only `gbtree`, so the training function
+ applies them only to tree models. Their sampled values are still recorded
+ in every run's config; filter to tree runs when comparing those parameters.
""")
return
@@ -300,256 +116,164 @@ def _():
@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
- ## 2. Initialize the Sweep
- """)
- return
+ ## Initialize the sweep
+ `wandb.sweep` registers this configuration with Weights & Biases and returns a sweep ID.
+ The sweep service supplies parameter choices to agents and tracks the
+ metrics their runs report.
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- Calling `wandb.sweep` starts a Sweep Controller --
- a centralized process that provides settings of the `parameters` to any who query it
- and expects them to return performance on `metrics` via `wandb` logging.
+ Running this cell creates a new sweep. To add trials to the same sweep,
+ rerun only the agent cell below with the existing `sweep_id`.
""")
return
@app.cell
-def _(sweep_config, sweep_request):
- sweep_id = wandb.sweep(
- sweep=sweep_config,
- entity=sweep_request["entity"],
- project=sweep_request["project"],
- )
+def _(entity, project, sweep_config):
+ sweep_id = wandb.sweep(sweep=sweep_config, entity=entity, project=project)
return (sweep_id,)
@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
- ### Define your training process
- Before we can run the sweep,
- we need to define a function that creates and trains the model --
- the function that takes in hyperparameter values and spits out metrics.
-
- We'll also need `wandb` to be integrated into our script.
- There's three main components:
- * `wandb.init()` – Initialize a new W&B run. Each run is single execution of the training script.
- * `wandb.config` – Save all your hyperparameters in a config object. This lets you use [our app](https://wandb.ai) to sort and compare your runs by hyperparameter values.
- * `wandb.log()` – Logs metrics and custom objects – these can be images, videos, audio files, HTML, plots, point clouds etc.
- """)
- return
+ ### Prepare the dataset
+ Download the Pima Indians Diabetes CSV once and reuse it across trials.
+ The first eight columns are features and the last column is the binary
+ target. Each trial uses the same split seed and held-out fraction so its
+ accuracy can be compared with other trials.
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
- We also need the Pima Indians Diabetes dataset. Each sweep run reads this
- small public CSV directly from its source, so the notebook does not rely on
- a repository checkout or leave a downloaded data file behind.
+ Because the sweep uses this held-out split to select hyperparameters, it
+ serves as validation data. Use a separate test set for a final evaluation.
""")
return
-@app.function
-def train():
- # XGBoost model for Pima Indians dataset
- from xgboost import XGBClassifier
+@app.cell
+def _():
+ with urlopen(DATASET_URL, timeout=30) as dataset_response:
+ dataset = loadtxt(dataset_response, delimiter=",")
+ X, y = dataset[:, :8], dataset[:, 8]
+ return X, y
- if wandb.run is not None:
- wandb.finish()
- config_defaults = {
- "booster": "gbtree",
- "max_depth": 3,
- "learning_rate": 0.1,
- "subsample": 1,
- "seed": 117,
- "test_size": 0.33,
- }
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ### Define the training function
- # The sweep agent overrides these defaults with each sampled configuration.
- with wandb.init(config=config_defaults) as run:
- config = run.config
-
- # Load data and split it into predictors and targets.
- with urlopen(DATASET_URL, timeout=30) as dataset_response:
- dataset = loadtxt(dataset_response, delimiter=",")
- X, y = dataset[:, :8], dataset[:, 8]
-
- # Split data into train and test sets.
- X_train, X_test, y_train, y_test = train_test_split(
- X,
- y,
- test_size=config.test_size,
- random_state=config.seed,
- )
-
- # Fit the model on the training data.
- model = XGBClassifier(
- booster=config.booster,
- max_depth=config.max_depth,
- learning_rate=config.learning_rate,
- subsample=config.subsample,
- )
- model.fit(X_train, y_train)
-
- # Make predictions on the test set.
- y_pred = model.predict(X_test)
- predictions = [round(value) for value in y_pred]
-
- # Evaluate and log the result.
- accuracy = accuracy_score(y_test, predictions)
- print(f"Accuracy: {accuracy:.0%}")
- run.log({"accuracy": accuracy})
+ The agent calls `train()` once per trial. Inside the function:
+ - `wandb.init(config=config_defaults)` starts a run. Values supplied by the
+ sweep override the defaults.
+ - `run.config` provides that trial's hyperparameters.
+ - `run.log({"accuracy": accuracy})` reports the metric named in the sweep
+ configuration.
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- ## 3. Run the Sweep with an agent
+ The context manager finishes each run before the next trial begins.
""")
return
+@app.cell
+def _(X, y):
+ def train():
+ config_defaults = {
+ "booster": "gbtree",
+ "max_depth": 3,
+ "learning_rate": 0.1,
+ "subsample": 1,
+ "seed": 117,
+ "test_size": 0.33,
+ }
+
+ with wandb.init(config=config_defaults) as run:
+ config = run.config
+ X_train, X_valid, y_train, y_valid = train_test_split(
+ X,
+ y,
+ test_size=config.test_size,
+ random_state=config.seed,
+ )
+
+ model_params = {
+ "booster": config.booster,
+ "learning_rate": config.learning_rate,
+ "random_state": config.seed,
+ "n_jobs": 2,
+ }
+ if config.booster == "gbtree":
+ model_params.update(
+ max_depth=config.max_depth,
+ subsample=config.subsample,
+ )
+ model = XGBClassifier(**model_params)
+ model.fit(X_train, y_train)
+
+ predictions = model.predict(X_valid)
+ accuracy = accuracy_score(y_valid, predictions)
+ print(f"Validation accuracy: {accuracy:.1%}")
+ run.log({"accuracy": accuracy})
+
+ return (train,)
+
+
@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
- Now, we call `wandb.agent` to start up our sweep.
+ ## Run the sweep agent
- You can call `wandb.agent` on any machine where you're logged into W&B that has
- - the `sweep_id`,
- - the dataset and `train` function
+ The agent requests hyperparameters from Weights & Biases and calls `train` for each trial.
+ `count` limits how many runs this agent launches; without it, a random sweep
+ can continue indefinitely. Start with a smaller `run_count` for a quick check.
- and that machine will join the sweep!
-
- > _Note_: a `random` sweep will by default run forever,
- trying new parameter combinations until the cows come home --
- or until you [turn the sweep off from the app UI](https://docs.wandb.ai/ref/app/features/sweeps).
- You can prevent this by providing the total `count` of runs you'd like the `agent` to complete.
+ Agents on other machines can join the same sweep using its ID, entity,
+ project, and the same training function and dataset. The count applies to
+ each agent, rather than the whole sweep.
""")
return
@app.cell
-def _(sweep_id, sweep_request):
+def _(entity, project, sweep_id, train):
+ run_count = 25
wandb.agent(
sweep_id,
function=train,
- count=sweep_request["run_count"],
- )
- sweep_complete = {
- "entity": sweep_request["entity"],
- "project": sweep_request["project"],
- "run_count": sweep_request["run_count"],
- "sweep_id": sweep_id,
- }
- return (sweep_complete,)
-
-
-@app.cell(hide_code=True)
-def _(sweep_complete):
- mo.callout(
- mo.md(
- f"**Sweep complete.** Agent `{sweep_complete['sweep_id']}` finished "
- f"{sweep_complete['run_count']} runs in project "
- f"`{sweep_complete['project']}`."
- ),
- kind="success",
+ count=run_count,
+ entity=entity,
+ project=project,
)
return
@app.cell(hide_code=True)
-def _(mo):
+def _():
mo.md(r"""
## Visualize your results
- """)
- return
+ Click on the link returned by Weights & Biases in the previous cell. The link will look similar to the following:
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- Now that your sweep is finished, it's time to look at the results.
+ ```bash
+ 🧹 View sweep at https://wandb.ai/wandb/XGBoost-sweeps/sweeps/wna9genj
+ ```
- Weights & Biases will generate a number of useful plots for you automatically.
- """)
- return
+ Navigate to the **Sweep** panel. By default, Weights & Biases plots [parallel coordinates](https://docs.coreweave.com/products/wandb/app/features/panels/parallel-coordinates#parallel-coordinates), [scatter plot, and a parameter importance plot](https://docs.coreweave.com/products/wandb/sweeps/visualize-sweep-results#scatter-plot-and-parameter-importance).
+ ## Verify and next steps
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- ### Parallel coordinates plot
-
- This plot maps hyperparameter values to model metrics. It’s useful for honing in on combinations of hyperparameters that led to the best model performance.
-
- This plot seems to indicate that using a tree as our learner slightly,
- but not mind-blowingly,
- outperforms using a simple linear model as our learner.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- 
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- ### Hyperparameter importance plot
-
- The hyperparameter importance plot shows which hyperparameter values had the biggest impact
- on your metrics.
-
- We report both the correlation (treating it as a linear predictor)
- and the feature importance (after training a random forest on your results)
- so you can see which parameters had the biggest effect
- and whether that effect was positive or negative.
+ Check that the agent's runs finished and that each run has an `accuracy`
+ value and the sampled parameters in **Config**. Inspect the parallel
+ coordinates and parameter importance panels, filtering to tree runs when
+ evaluating `max_depth` and `subsample`.
- Reading this chart, we see quantitative confirmation
- of the trend we noticed in the parallel coordinates chart above:
- the largest impact on validation accuracy came from the choice of
- learner, and the `gblinear` learners were generally worse than `gbtree` learners.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(mo):
- mo.md(r"""
- 
- """)
- return
-
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
- These visualizations can help you save both time and resources running expensive hyperparameter optimizations by honing in on the parameters (and value ranges) that are the most important, and thereby worthy of further exploration.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _(sweep_complete):
- mo.md(f"""
- ## Verify your sweep
-
- In W&B, open project `{sweep_complete["project"]}` and select the sweep with
- ID `{sweep_complete["sweep_id"]}`. Confirm that it contains
- {sweep_complete["run_count"]} completed runs, then inspect the parallel
- coordinates and hyperparameter importance panels to see which settings had
- the strongest relationship with `accuracy`.
+ Try narrowing the learning-rate values or changing `method` to `bayes`.
+ Run the sweep-creation cell again, then the agent cell, to compare the new
+ sweep with the first one. See the [Sweeps documentation](https://docs.wandb.ai/models/sweeps)
+ for more configuration options.
""")
return
From 2085663ccb0fd821b95068f4ae74f1e053506502 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 18:40:00 -0700
Subject: [PATCH 28/48] plot-roc-curves
---
.../plot_roc_curves_with_w_b.py | 618 ++++++++----------
1 file changed, 264 insertions(+), 354 deletions(-)
diff --git a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
index 0adeb854..8214c4b0 100644
--- a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
+++ b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
@@ -1,8 +1,7 @@
# /// script
# requires-python = ">=3.11,<3.14"
# dependencies = [
-# "fsspec[http]",
-# "marimo>=0.24.0",
+# "marimo>=0.24.2",
# "numpy>=1.26",
# "pandas>=2.2",
# "pillow==12.3.0",
@@ -11,8 +10,10 @@
# "tensorflow==2.21.0",
# "wandb==0.30.0",
# ]
+#
+# [tool.marimo.runtime]
+# on_cell_change = "lazy"
# ///
-"""Fine-tune InceptionV3 and log multiclass ROC curves to W&B."""
import marimo
@@ -24,13 +25,14 @@
import tempfile
import zipfile
from pathlib import Path
+ from urllib.request import urlopen
- import fsspec
import marimo as mo
import numpy as np
+ import pandas as pd
import tensorflow as tf
import wandb
- from tensorflow.keras.applications.inception_v3 import InceptionV3
+ from tensorflow.keras.applications.inception_v3 import InceptionV3, preprocess_input
from tensorflow.keras.callbacks import Callback
from tensorflow.keras.layers import Dense, GlobalAveragePooling2D
from tensorflow.keras.models import Model
@@ -38,454 +40,362 @@
from wandb.integration.keras import WandbMetricsLogger
DATASET_URL = "https://storage.googleapis.com/wandb_datasets/nature_12K.zip"
- PROJECT_NAME = "custom_roc_curve"
RUNTIME_CACHE_ROOT = (
Path(tempfile.gettempdir()) / "wandb-examples" / "inaturalist-12k"
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
# Plot ROC Curves with W&B
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py/server)
- Learn how to log [receiver operating characteristic (ROC) curves](https://scikit-learn.org/stable/modules/model_evaluation.html#receiver-operating-characteristic-roc) backed by [Vega](https://vega.github.io/vega/docs/) in [Weights & Biases](https://wandb.ai). This example fine-tunes InceptionV3 with ImageNet weights to identify 10 types of living things from the [iNaturalist 2017 dataset](https://github.com/visipedia/inat_comp).
+ Learn to log multiclass ROC curves with `wandb.plot.roc_curve()`. This lesson
+ trains a classification head on a frozen, ImageNet-trained InceptionV3 model
+ to identify ten groups of living things from an iNaturalist image sample.
+
+ An ROC curve plots the true-positive rate against the false-positive rate
+ as the decision threshold changes. For multiclass predictions, each curve
+ treats one class as positive and all other classes as negative.
- These simple cases explain the basics; W&B's query editor supports more sophisticated custom charts.
+ 
- 
+ The small training defaults let you try the workflow on a CPU. More data
+ and epochs can improve the curves; a GPU speeds up training.
- The defaults intentionally use few training examples and one epoch so you can exercise the workflow. The original tutorial reports validation accuracy in the low 80s after roughly one epoch on the complete training dataset.
+ ## Set up your experiment
- ## Method: `wandb.plot.roc_curve()`
+ Get your [Weights & Biases API key](https://wandb.ai/authorize) and set
+ `WANDB_API_KEY` in your runtime's environment or **Secrets** panel. Locally,
+ you can also run `wandb login` in a terminal. A hosted runtime needs its own
+ credentials.
- - Read about [ROC curve customization](https://wandb.ai/wandb/plots/reports/Plot-ROC-Curves--VmlldzoyNjk3MDE).
- - Explore more examples in the [Custom Charts project](https://app.wandb.ai/demo-team/custom-charts).
+ Set `entity` to your team slug, or leave it as `None` to use your default
+ entity. The slug appears in `wandb.ai//`.
""")
return
-@app.cell(hide_code=False)
+@app.cell
def _():
- mo.md(r"""
- ## Authentication
-
- Enter a [W&B API key](https://wandb.ai/authorize) and an optional team entity below. Leave the key blank when `WANDB_API_KEY` is configured in the Molab Secrets panel or this runtime already has W&B credentials. If needed, [create a free W&B account](https://wandb.ai/signup).
-
- Your entity is the first path segment after `wandb.ai` when you open a W&B workspace. The API key is used only for `wandb.login()` and is never included in the run configuration or notebook output.
- """)
- return
+ entity = None
+ project = "custom_roc_curve"
+ wandb.login()
+ return entity, project
@app.cell(hide_code=True)
def _():
- _api_key_input = mo.ui.text(
- kind="password",
- label="W&B API key (optional)",
- placeholder="Paste a key or use configured credentials",
- full_width=True,
- )
- _entity_input = mo.ui.text(
- label="W&B entity or team (optional)",
- placeholder="Leave blank to use your default entity",
- full_width=True,
- )
- wandb_login_form = (
- mo.md("{api_key}\n\n{entity}")
- .batch(api_key=_api_key_input, entity=_entity_input)
- .form(submit_button_label="Connect to W&B", bordered=True)
- )
- wandb_login_form
- return (wandb_login_form,)
+ mo.md(r"""
+ ## Experiment configuration
+ Start with 100 training images, 500 validation images, and one epoch. We
+ sample evenly across the ten classes so every class has positive and
+ negative examples for its ROC curve. Keep the seed and validation size
+ fixed when comparing experiments.
-@app.cell(hide_code=True)
-def _(wandb_login_form):
- mo.stop(
- wandb_login_form.value is None,
- mo.callout(
- mo.md("Connect to W&B before configuring the experiment."),
- kind="info",
- ),
- )
+ Passing this dictionary to `wandb.init(config=config)` records the settings
+ with the run. Try increasing `num_train` or `epochs` after your first run.
+ """)
+ return
- _api_key = wandb_login_form.value["api_key"].strip()
- _entity = wandb_login_form.value["entity"].strip()
- try:
- _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
- _login_error = None
- except wandb.errors.Error as _error:
- _login_ok = False
- _login_error = str(_error)
-
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md(
- "W&B authentication did not complete. Check the API key or "
- "Molab Secrets configuration and submit again.\n\n"
- f"W&B reported: `{_login_error or 'unknown error'}`"
- ),
- kind="danger",
- ),
- )
- wandb_settings = {
- "project": PROJECT_NAME,
- "entity": _entity or None,
+@app.cell
+def _():
+ config = {
+ "num_train": 100,
+ "num_val": 500,
+ "num_classes": 10,
+ "fc_size": 1024,
+ "img_width": 299,
+ "img_height": 299,
+ "batch_size": 32,
+ "epochs": 1,
+ "random_seed": 23,
}
- _entity_note = (
- f" Runs will be logged to `{wandb_settings['entity']}`."
- if wandb_settings["entity"]
- else " Runs will use your default W&B entity."
- )
- mo.callout(mo.md(f"Connected to W&B.{_entity_note}"), kind="success")
- return (wandb_settings,)
+ return (config,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Setup: Access the remote dataset
-
- The iNaturalist sample contains 10,000 training images and 2,000 validation images, evenly distributed across 10 classes such as birds, insects, plants, and mammals. **The archive is approximately 3.6 GB, so the first transfer and extraction can take several minutes.**
+ ## Prepare the dataset
- The `dataset_fs` value below exposes the public archive through an `fsspec` reference filesystem, so you can browse it in marimo's data side panel without transferring the whole file.
+ The [iNaturalist sample](https://github.com/visipedia/inat_comp) contains
+ 10,000 training images and 2,000 validation images across ten classes.
+ **The first run downloads and extracts an approximately 3.6 GB archive,**
+ even with the small training defaults. Later runs reuse the temporary
+ runtime cache.
- Training still requires local image directories. The first time you submit the training form, `ensure_dataset()` streams the archive into a temporary runtime cache and extracts it there. Later submissions reuse that cache; no dataset files are written beside the notebook.
+ `sample_images` selects the requested number of files from each split,
+ distributing them across classes. The download and sampling helpers are
+ defined at the end of the notebook.
""")
return
@app.cell
-def _():
- # Expose the remote dataset as a named filesystem so it appears in
- # marimo's data side panel.
- dataset_fs = fsspec.filesystem(
- "reference",
- fo={
- "version": 1,
- "refs": {"nature_12K.zip": [DATASET_URL]},
- },
+def _(config):
+ train_path, validation_path = ensure_dataset()
+ train_samples = sample_images(train_path, config["num_train"], config["random_seed"])
+ validation_samples = sample_images(
+ validation_path, config["num_val"], config["random_seed"]
)
- return (dataset_fs,)
+ class_names = sorted(train_samples["class"].unique())
+ return class_names, train_samples, validation_samples
-@app.function
-def ensure_dataset(dataset_fs):
- """Materialize and extract the remote dataset once, then return its paths."""
- archive_path = RUNTIME_CACHE_ROOT / "nature_12K.zip"
- train_path = RUNTIME_CACHE_ROOT / "inaturalist_12K" / "train"
- validation_path = RUNTIME_CACHE_ROOT / "inaturalist_12K" / "val"
-
- if train_path.is_dir() and validation_path.is_dir():
- return str(train_path), str(validation_path), "Reused the extracted dataset."
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ## Prepare image batches
- RUNTIME_CACHE_ROOT.mkdir(parents=True, exist_ok=True)
- if not archive_path.exists():
- partial_path = archive_path.with_suffix(".zip.part")
- # Keras needs local directories, so stream the remote archive into the
- # runtime cache without loading 3.6 GB into memory.
- with dataset_fs.open("nature_12K.zip", "rb") as source:
- with partial_path.open("wb") as destination:
- shutil.copyfileobj(source, destination)
- partial_path.replace(archive_path)
+ Augment the training images with shear, zoom, and horizontal flips. Both
+ generators use InceptionV3's [preprocessing function](https://keras.io/api/applications/inceptionv3/inception_v3_preprocessing/),
+ which scales pixel values to the range −1 to 1.
- with zipfile.ZipFile(archive_path) as archive:
- archive.extractall(archive_path.parent)
+ Validation images are neither augmented nor shuffled. The same selected
+ images, class IDs, and class order are used for validation and ROC logging
+ at every epoch.
+ """)
+ return
- if not train_path.is_dir() or not validation_path.is_dir():
- raise FileNotFoundError(
- "The archive did not contain inaturalist_12K/train and "
- "inaturalist_12K/val."
- )
- return str(train_path), str(validation_path), "Streamed and extracted the remote dataset."
+@app.cell
+def _(class_names, config, train_samples, validation_samples):
+ train_datagen = ImageDataGenerator(
+ preprocessing_function=preprocess_input,
+ shear_range=0.2,
+ zoom_range=0.2,
+ horizontal_flip=True,
+ )
+ validation_datagen = ImageDataGenerator(preprocessing_function=preprocess_input)
+
+ train_generator = train_datagen.flow_from_dataframe(
+ train_samples,
+ x_col="filename",
+ y_col="class",
+ classes=class_names,
+ target_size=(config["img_height"], config["img_width"]),
+ batch_size=config["batch_size"],
+ class_mode="categorical",
+ shuffle=True,
+ seed=config["random_seed"],
+ )
+ validation_generator = validation_datagen.flow_from_dataframe(
+ validation_samples,
+ x_col="filename",
+ y_col="class",
+ classes=class_names,
+ target_size=(config["img_height"], config["img_width"]),
+ batch_size=config["batch_size"],
+ class_mode="categorical",
+ shuffle=False,
+ )
+ return train_generator, validation_generator
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Training code
+ ## Build and compile the model
- The model freezes the ImageNet-trained InceptionV3 base and trains a new classification head. At the end of each epoch, `ROCCurveLogger` predicts several validation batches and sends the ground-truth class IDs and per-class probabilities to `wandb.plot.roc_curve()`.
-
- Change the number of training examples or epochs in the form to compare ROC curves. The small defaults favor demo speed over accuracy.
+ Freeze the pretrained InceptionV3 base and train a new classification head.
+ The final softmax layer produces one probability per class. Rerun the model
+ creation cell before each new experiment to start with a fresh head;
+ rerunning only the training cell continues from the current model weights.
""")
return
@app.function
def build_model(fc_size, num_classes):
- """Freeze an ImageNet-trained InceptionV3 base and add a classifier head."""
base = InceptionV3(weights="imagenet", include_top=False)
- for layer in base.layers:
- layer.trainable = False
-
- features = base.get_layer("mixed10").output
- features = GlobalAveragePooling2D()(features)
+ base.trainable = False
+ features = GlobalAveragePooling2D()(base.output)
features = Dense(fc_size, activation="relu")(features)
- predictions = Dense(num_classes, activation="softmax")(features)
+ probabilities = Dense(num_classes, activation="softmax")(features)
+ return Model(inputs=base.input, outputs=probabilities)
+
- model = Model(inputs=base.input, outputs=predictions)
+@app.cell
+def _(config):
+ tf.keras.backend.clear_session()
+ tf.keras.utils.set_random_seed(config["random_seed"])
+ model = build_model(config["fc_size"], config["num_classes"])
model.compile(
optimizer="rmsprop",
loss="categorical_crossentropy",
metrics=["accuracy"],
)
- return model
+ model.summary()
+ return (model,)
-@app.function
-def make_roc_curve_logger(run, generator, num_log_batches):
- """Create a Keras callback that logs multiclass ROC curves each epoch."""
-
- class ROCCurveLogger(Callback):
- def __init__(self):
- super().__init__()
- self.generator = generator
- self.num_batches = num_log_batches
- self.class_names = [
- name
- for name, _class_id in sorted(
- generator.class_indices.items(), key=lambda item: item[1]
- )
- ]
-
- def on_epoch_end(self, epoch, logs=None):
- validation_batches = [
- self.generator[index] for index in range(self.num_batches)
- ]
- validation_data = np.vstack(
- [batch_data for batch_data, _batch_labels in validation_batches]
- )
- validation_labels = np.vstack(
- [batch_labels for _batch_data, batch_labels in validation_batches]
- )
-
- validation_probabilities = self.model.predict(
- validation_data, verbose=0
- )
- ground_truth_class_ids = validation_labels.argmax(axis=1)
-
- # Keep this key stable so curves from multiple runs share a panel.
- run.log(
- {
- "roc_curve": wandb.plot.roc_curve(
- ground_truth_class_ids,
- validation_probabilities,
- labels=self.class_names,
- )
- }
- )
-
- return ROCCurveLogger()
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ## Log ROC curves at each epoch
+ The callback passes three values to [`wandb.plot.roc_curve`](https://docs.wandb.ai/models/ref/python/custom-charts/roc_curve):
+
+ - Ground-truth class IDs, with shape `(num_images,)`.
+ - Predicted probabilities, with shape `(num_images, num_classes)`.
+ - Class names in the same order as the probability columns.
+
+ Use the probabilities rather than the predicted class IDs: ROC curves
+ evaluate different thresholds. The callback processes one batch of images
+ at a time and collects only labels and probabilities for the chart.
+
+ Keep the `roc_curve` logging key consistent so runs can share a chart panel.
+ """)
+ return
-@app.function
-def train_and_log(config, wandb_settings, train_path, validation_path):
- """Train the model and complete one W&B run."""
- if wandb.run is not None:
- wandb.finish()
-
- with wandb.init(
- project=wandb_settings["project"],
- entity=wandb_settings["entity"],
- config=config,
- ) as run:
- run_config = run.config
- tf.random.set_seed(run_config.random_seed)
- np.random.seed(run_config.random_seed)
-
- train_datagen = ImageDataGenerator(
- rescale=1.0 / 255,
- shear_range=0.2,
- zoom_range=0.2,
- horizontal_flip=True,
- )
- validation_datagen = ImageDataGenerator(rescale=1.0 / 255)
- train_generator = train_datagen.flow_from_directory(
- train_path,
- target_size=(run_config.img_width, run_config.img_height),
- batch_size=run_config.batch_size,
- class_mode="categorical",
+@app.class_definition
+class ROCCurveLogger(Callback):
+ def __init__(self, run, generator):
+ super().__init__()
+ self.run = run
+ self.generator = generator
+ self.class_names = sorted(
+ generator.class_indices, key=generator.class_indices.get
)
- validation_generator = validation_datagen.flow_from_directory(
- validation_path,
- target_size=(run_config.img_width, run_config.img_height),
- batch_size=run_config.batch_size,
- class_mode="categorical",
- # Shuffle so the validation subset logged to the ROC chart samples
- # every class instead of the first few directory-ordered classes.
- shuffle=True,
- seed=run_config.random_seed,
+
+ def on_epoch_end(self, epoch, logs=None):
+ class_ids = []
+ probabilities = []
+ for index in range(len(self.generator)):
+ images, labels = self.generator[index]
+ class_ids.append(labels.argmax(axis=1))
+ probabilities.append(self.model.predict_on_batch(images))
+
+ self.run.log(
+ {
+ "roc_curve": wandb.plot.roc_curve(
+ np.concatenate(class_ids),
+ np.concatenate(probabilities),
+ labels=self.class_names,
+ )
+ }
)
- model = build_model(run_config.fc_size, run_config.num_classes)
- callbacks = [
- WandbMetricsLogger(),
- make_roc_curve_logger(
- run,
- validation_generator,
- run_config.num_log_batches,
- ),
- ]
+
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ## Train
+
+ Create a W&B run, then pass both callbacks to `model.fit`.
+ `WandbMetricsLogger` records loss and accuracy; `ROCCurveLogger` records
+ per-class ROC curves. Training and validation use all of their selected
+ images, including the final partial batch.
+
+ The context manager finishes the run when training ends.
+ """)
+ return
+
+
+@app.cell
+def _(config, entity, model, project, train_generator, validation_generator):
+ with wandb.init(entity=entity, project=project, config=config) as run:
history = model.fit(
train_generator,
- steps_per_epoch=max(1, run_config.num_train // run_config.batch_size),
- epochs=run_config.pretrain_epochs,
+ epochs=config["epochs"],
validation_data=validation_generator,
- callbacks=callbacks,
- validation_steps=max(1, run_config.num_val // run_config.batch_size),
+ callbacks=[
+ WandbMetricsLogger(),
+ ROCCurveLogger(run, validation_generator),
+ ],
)
+ return (history,)
- final_validation_accuracy = history.history.get("val_accuracy", [None])[-1]
- result = {
- "run_url": run.url,
- "final_validation_accuracy": (
- float(final_validation_accuracy)
- if final_validation_accuracy is not None
- else None
- ),
- }
- return result
-
-
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Run the experiment
+ ## Explore your results
+
+ Open the run link printed by Weights & Biases and find the `roc_curve`
+ custom chart. Check that it contains all ten class names. Compare curves
+ across epochs and runs: a curve closer to the upper-left corner indicates
+ better separation of that class from the others.
- After connecting to W&B above, submit this training form to materialize the remote dataset in the runtime cache if necessary, download the InceptionV3 weights if necessary, train the model, and create one run in the `custom_roc_curve` project. A later submission finishes any prior active run before it starts another.
+ Inspect `epoch/loss`, `epoch/val_loss`, and `epoch/val_accuracy` alongside
+ the curves. Increase `num_train` or `epochs`, rebuild the model, and train
+ again while keeping the validation sample fixed.
+
+ See [ROC chart customization](https://wandb.ai/wandb/plots/reports/Plot-ROC-Curves--VmlldzoyNjk3MDE)
+ and the [Custom Charts project](https://app.wandb.ai/demo-team/custom-charts)
+ for more examples.
""")
return
@app.cell(hide_code=True)
-def _(wandb_settings):
- _workflow_ready = callable(ensure_dataset) and callable(train_and_log)
- _num_train_input = mo.ui.number(
- start=32,
- stop=10_000,
- step=1,
- value=100,
- label="Training examples",
- )
- _num_epochs_input = mo.ui.number(
- start=1,
- stop=20,
- step=1,
- value=1,
- label="Epochs",
- )
- training_form = (
- mo.md("{num_train}\n\n{num_epochs}")
- .batch(
- num_train=_num_train_input,
- num_epochs=_num_epochs_input,
- )
- .form(
- submit_button_label="Prepare data, train, and log to W&B",
- submit_button_disabled=not _workflow_ready,
- bordered=True,
- )
- )
- _destination = (
- f"`{wandb_settings['entity']}/{wandb_settings['project']}`"
- if wandb_settings["entity"]
- else f"`{wandb_settings['project']}` in your default entity"
- )
- mo.vstack(
- [
- mo.md(f"This run will be created in {_destination}."),
- training_form,
- ]
- )
- return (training_form,)
-
+def _():
+ mo.md(r"""
+ ## Helper functions
-@app.cell(hide_code=True)
-def _(training_form, wandb_settings):
- mo.stop(
- training_form.value is None,
- mo.callout(
- mo.md("Review the workflow above, then submit the form to begin."),
- kind="info",
- ),
- )
+ Cache the archive and extracted directories, then select a reproducible
+ sample of images from each class. Use at least ten images per split to
+ include every class, up to 10,000 for training and 2,000 for validation.
+ """)
+ return
- training_request = {
- "wandb_settings": dict(wandb_settings),
- "num_train": int(training_form.value["num_train"]),
- "num_epochs": int(training_form.value["num_epochs"]),
- }
- return (training_request,)
+@app.function
+def ensure_dataset():
+ """Materialize and extract the remote dataset once, then return its paths."""
+ archive_path = RUNTIME_CACHE_ROOT / "nature_12K.zip"
+ train_path = RUNTIME_CACHE_ROOT / "inaturalist_12K" / "train"
+ validation_path = RUNTIME_CACHE_ROOT / "inaturalist_12K" / "val"
-@app.cell
-def _(training_request):
- # Experiment configuration saved to W&B.
- config_defaults = {
- "num_train": training_request["num_train"],
- "num_val": 500,
- "num_classes": 10,
- "fc_size": 1024,
- "img_width": 299,
- "img_height": 299,
- "batch_size": 32,
- "pretrain_epochs": training_request["num_epochs"],
- "num_log_batches": 15,
- "random_seed": 23,
- }
- config_defaults
- return (config_defaults,)
+ if train_path.is_dir() and validation_path.is_dir():
+ return str(train_path), str(validation_path)
+ RUNTIME_CACHE_ROOT.mkdir(parents=True, exist_ok=True)
+ if not archive_path.exists():
+ partial_path = archive_path.with_suffix(".zip.part")
+ # Keras needs local directories, so stream the remote archive into the
+ # runtime cache without loading 3.6 GB into memory.
+ with urlopen(DATASET_URL, timeout=60) as source:
+ with partial_path.open("wb") as destination:
+ shutil.copyfileobj(source, destination)
+ partial_path.replace(archive_path)
-@app.cell(hide_code=True)
-def _(config_defaults, dataset_fs):
- train_path, validation_path, dataset_status = ensure_dataset(dataset_fs)
- mo.callout(
- mo.md(
- f"{dataset_status} Training will use "
- f"{config_defaults['num_train']:,} images per epoch."
- ),
- kind="success",
- )
- return train_path, validation_path
+ with zipfile.ZipFile(archive_path) as archive:
+ archive.extractall(archive_path.parent)
+ if not train_path.is_dir() or not validation_path.is_dir():
+ raise FileNotFoundError(
+ "The archive did not contain inaturalist_12K/train and "
+ "inaturalist_12K/val."
+ )
-@app.cell
-def _(config_defaults, train_path, training_request, validation_path):
- experiment_result = train_and_log(
- config=config_defaults,
- wandb_settings=training_request["wandb_settings"],
- train_path=train_path,
- validation_path=validation_path,
- )
- return (experiment_result,)
+ return str(train_path), str(validation_path)
-@app.cell(hide_code=True)
-def _(experiment_result):
- _accuracy = experiment_result["final_validation_accuracy"]
- _accuracy_note = (
- f" The final validation accuracy was `{_accuracy:.3f}`."
- if _accuracy is not None
- else ""
- )
- mo.callout(
- mo.md(
- f"Training finished.{_accuracy_note} "
- f"[Open the run in W&B]({experiment_result['run_url']}) and find "
- "`roc_curve` under **Custom Charts** to inspect the ROC curves."
- ),
- kind="success",
- )
- return
+@app.function
+def sample_images(directory, num_images, seed):
+ class_dirs = sorted(path for path in Path(directory).iterdir() if path.is_dir())
+ if num_images < len(class_dirs):
+ raise ValueError("Choose at least one image per class.")
+ per_class, remainder = divmod(num_images, len(class_dirs))
+ samples = []
+ for index, class_dir in enumerate(class_dirs):
+ filenames = sorted(
+ str(path)
+ for path in class_dir.iterdir()
+ if path.suffix.lower() in {".jpg", ".jpeg", ".png"}
+ )
+ class_images = pd.DataFrame({"filename": filenames, "class": class_dir.name})
+ samples.append(
+ class_images.sample(n=per_class + (index < remainder), random_state=seed)
+ )
+ return pd.concat(samples, ignore_index=True)
if __name__ == "__main__":
From 159c01fb127b64c1aebf24f5066dbccf8bf3f20d Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 18:40:34 -0700
Subject: [PATCH 29/48] re hide
---
.../alphafold_with_w_b_align_fold_log.py | 19 +++++++++----------
1 file changed, 9 insertions(+), 10 deletions(-)
diff --git a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
index 350c2d65..7de9cf03 100644
--- a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
+++ b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
@@ -35,7 +35,7 @@
import wandb
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
# ColabFold with Weights & Biases: Align, Fold, Log
@@ -99,7 +99,7 @@ def _():
return inference_backend, runtime_ready
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 2. Authenticate with Weights & Biases
@@ -126,7 +126,7 @@ def _():
return authenticated, entity, project
-@app.cell(hide_code=False)
+@app.cell
def _():
mo.md(r"""
## 3. Choose a Protein and Prediction Settings
@@ -252,7 +252,7 @@ def _(SEQUENCES):
)
-@app.cell(hide_code=False)
+@app.cell
def _():
mo.md(r"""
## 4. Align and Fold
@@ -359,7 +359,7 @@ def _(
return (fold_result,)
-@app.cell(hide_code=False)
+@app.cell
def _():
mo.md(r"""
## 5. Inspect Alignment and Confidence
@@ -523,7 +523,7 @@ def _(prediction_summary):
return
-@app.cell(hide_code=False)
+@app.cell
def _():
mo.md(r"""
## 6. Log the Prediction to Weights & Biases
@@ -606,12 +606,11 @@ def _(entity, prediction_summary, project):
if pae_plot is not None:
log_payload["predicted_aligned_error"] = pae_plot
prediction_run.log(log_payload)
-
- return
+ return
@app.cell(hide_code=True)
-def _(run_url):
+def _():
mo.md(f"""
## 7. Compare Predictions
@@ -630,7 +629,7 @@ def _(run_url):
return
-@app.cell(hide_code=False)
+@app.cell
def _():
mo.md(r"""
## References
From 2c41af4a82ca5d7d4a8158675663339f56e59f61 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 18:45:55 -0700
Subject: [PATCH 30/48] remove some mention of wb api key
---
.../plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py | 2 +-
.../train_and_debug_yolov5_models_with_weights_biases.py | 2 +-
.../use_wandbevalcallback_in_your_keras_workflow.py | 2 +-
.../use_wandbmetriclogger_in_your_keras_workflow.py | 2 +-
.../use_wandbmodelcheckpoint_in_your_keras_workflow.py | 2 +-
.../using_w_b_sweeps_with_xgboost.py | 2 +-
6 files changed, 6 insertions(+), 6 deletions(-)
diff --git a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
index 8214c4b0..04d0888b 100644
--- a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
+++ b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
@@ -67,7 +67,7 @@ def _():
## Set up your experiment
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set
+ Get your [Forge API key](https://wandb.ai/authorize) and set
`WANDB_API_KEY` in your runtime's environment or **Secrets** panel. Locally,
you can also run `wandb login` in a terminal. A hosted runtime needs its own
credentials.
diff --git a/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py b/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
index 55908704..5e6f4ae2 100644
--- a/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
+++ b/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
@@ -83,7 +83,7 @@ def _():
mo.md(r"""
## Set up your experiment and log in
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ Get your [Forge API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
your runtime's environment or **Secrets** panel. Locally, you can also run
`wandb login` in a terminal. A hosted runtime needs its own credentials.
diff --git a/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py b/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
index 9c2251ce..a3f7ce6a 100644
--- a/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
@@ -55,7 +55,7 @@ def _():
mo.md(r"""
## Set up your experiment and log in
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ Get your [Forge API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
your runtime's environment or **Secrets** panel. Locally, you can also run
`wandb login` in a terminal. A hosted runtime needs its own credentials.
diff --git a/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py b/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
index 97166796..6f3c7d04 100644
--- a/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
@@ -44,7 +44,7 @@ def _():
## Set up your experiment
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ Get your [Forge API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
your runtime's environment or **Secrets** panel. Locally, you can also run
`wandb login` in a terminal. A hosted runtime needs its own credentials.
diff --git a/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py b/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
index 18264b7b..6481e7f5 100644
--- a/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
@@ -48,7 +48,7 @@ def _():
## Set up your experiment
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
+ Get your [Forge API key](https://wandb.ai/authorize) and set `WANDB_API_KEY` in
your runtime's environment or **Secrets** panel. Locally, you can also run
`wandb login` in a terminal. A hosted runtime needs its own credentials.
diff --git a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
index 5d36f273..21f94d68 100644
--- a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
+++ b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
@@ -55,7 +55,7 @@ def _():
## Set up your experiment
- Get your [Weights & Biases API key](https://wandb.ai/authorize) and set
+ Get your [Forge API key](https://wandb.ai/authorize) and set
`WANDB_API_KEY` in your runtime's environment or **Secrets** panel. Locally,
you can also run `wandb login` in a terminal. A hosted runtime needs its
own credentials.
From 1f598c388003fa2733df7f26bb9050047f0d6686 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 18:46:32 -0700
Subject: [PATCH 31/48] more wb key mentions
---
.../custom-progress-callback/custom_progress_callback.py | 2 +-
marimo/convert/lcm-diffusers/lcm_diffusers.py | 4 ++--
2 files changed, 3 insertions(+), 3 deletions(-)
diff --git a/marimo/convert/custom-progress-callback/custom_progress_callback.py b/marimo/convert/custom-progress-callback/custom_progress_callback.py
index ef8ba299..13b56d91 100644
--- a/marimo/convert/custom-progress-callback/custom_progress_callback.py
+++ b/marimo/convert/custom-progress-callback/custom_progress_callback.py
@@ -104,7 +104,7 @@ def _():
@app.cell(hide_code=True)
def _():
wandb_login_form = mo.md("{api_key}\n\n{entity}").batch(
- api_key=mo.ui.text(kind="password", label="W&B API key (optional)", full_width=True),
+ api_key=mo.ui.text(kind="password", label="Forge API key (optional)", full_width=True),
entity=mo.ui.text(label="W&B entity or team (optional)", full_width=True),
).form(submit_button_label="Connect to W&B", bordered=True)
wandb_login_form
diff --git a/marimo/convert/lcm-diffusers/lcm_diffusers.py b/marimo/convert/lcm-diffusers/lcm_diffusers.py
index 41b7783e..af1f9978 100644
--- a/marimo/convert/lcm-diffusers/lcm_diffusers.py
+++ b/marimo/convert/lcm-diffusers/lcm_diffusers.py
@@ -50,7 +50,7 @@ def _():
mo.md(r"""
## Authentication
- Enter your [W&B API key](https://wandb.ai/authorize) and, if needed, your team or entity. You can leave the key blank when this environment already has W&B credentials. If this is your first time using W&B, [create a free account](https://wandb.ai/signup).
+ Enter your [Forge API key](https://wandb.ai/authorize) and, if needed, your team or entity. You can leave the key blank when this environment already has W&B credentials. If this is your first time using W&B, [create a free account](https://wandb.ai/signup).
A [Hugging Face token](https://huggingface.co/settings/tokens) is optional. Supplying one avoids anonymous Hub rate limits and can make the initial model download more reliable.
""")
@@ -61,7 +61,7 @@ def _():
def _():
_api_key_input = mo.ui.text(
kind="password",
- label="W&B API key (optional)",
+ label="Forge API key (optional)",
placeholder="Paste a key or use cached credentials",
full_width=True,
)
From df4cc10fc16dc2334166afe0036768379124e77a Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 19:19:17 -0700
Subject: [PATCH 32/48] renaming W&B
---
.../alphafold_with_w_b_align_fold_log.py | 10 +-
.../convert/configs-in-w-b/configs_in_w_b.py | 242 ++++++--------
.../credit_scorecards_with_xgboost_and_w_b.py | 162 ++++++----
.../custom_progress_callback.py | 36 +--
.../huggingface-wandb/huggingface_wandb.py | 303 +++++++-----------
...mization_in_tensorflow_using_w_b_sweeps.py | 50 +--
.../intro_to_weights_biases_keras.py | 4 +-
marimo/convert/lcm-diffusers/lcm_diffusers.py | 32 +-
.../log_a_confusion_matrix_with_w_b.py | 4 +-
.../log_almost_anything_with_w_b_media.py | 7 +-
.../openai_api_autologger_quickstart.py | 10 +-
...ch_lightning_models_with_weights_biases.py | 2 +-
...perparameter_sweeps_in_pytorch_with_w_b.py | 4 +-
.../pipeline_versioning_with_w_b_artifacts.py | 2 +-
.../plot_roc_curves_with_w_b.py | 8 +-
.../report_api_quickstart.py | 2 +-
.../simple_pytorch_integration.py | 18 +-
.../torchtune_and_wandb.py | 2 +-
...debug_yolov5_models_with_weights_biases.py | 2 +-
...andbevalcallback_in_your_keras_workflow.py | 2 +-
...andbmetriclogger_in_your_keras_workflow.py | 2 +-
...bmodelcheckpoint_in_your_keras_workflow.py | 2 +-
.../using_w_b_sweeps_with_xgboost.py | 2 +-
.../w_b_tables_quickstart.py | 28 +-
..._artifacts_time_to_live_ttl_walkthrough.py | 12 +-
marimo/convert/zoo-wandb/zoo_wandb.py | 28 +-
26 files changed, 443 insertions(+), 533 deletions(-)
diff --git a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
index 7de9cf03..ed545fd7 100644
--- a/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
+++ b/marimo/convert/alphafold-with-w-b-align-fold-log/alphafold_with_w_b_align_fold_log.py
@@ -126,7 +126,7 @@ def _():
return authenticated, entity, project
-@app.cell
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 3. Choose a Protein and Prediction Settings
@@ -252,7 +252,7 @@ def _(SEQUENCES):
)
-@app.cell
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 4. Align and Fold
@@ -359,7 +359,7 @@ def _(
return (fold_result,)
-@app.cell
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 5. Inspect Alignment and Confidence
@@ -523,7 +523,7 @@ def _(prediction_summary):
return
-@app.cell
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 6. Log the Prediction to Weights & Biases
@@ -629,7 +629,7 @@ def _():
return
-@app.cell
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## References
diff --git a/marimo/convert/configs-in-w-b/configs_in_w_b.py b/marimo/convert/configs-in-w-b/configs_in_w_b.py
index 30be12ad..73948c44 100644
--- a/marimo/convert/configs-in-w-b/configs_in_w_b.py
+++ b/marimo/convert/configs-in-w-b/configs_in_w_b.py
@@ -1,7 +1,12 @@
# /// script
+# requires-python = ">=3.11,<3.14"
# dependencies = [
+# "marimo>=0.24.2",
# "wandb==0.30.0",
# ]
+#
+# [tool.marimo.runtime]
+# on_cell_change = "lazy"
# ///
import marimo
@@ -15,7 +20,7 @@
import wandb
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- By the end of the notebook, your sweep dashboard will look conceptually like
- this example:
+
+
- 
- """)
- return
+ # Tune a TensorFlow model with Weights & Biases Sweeps
+ [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/hyperparameter-optimization-in-tensorflow-using-w-b-sweeps/hyperparameter_optimization_in_tensorflow_using_w_b_sweeps.py/server)
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
- [Weights & Biases Sweeps](https://docs.coreweave.com/products/wandb/sweeps)
- automate hyperparameter search and visualize rich, interactive experiment
- tracking. They support search methods such as random search, grid search, and
- Bayesian optimization, and they can scale from this single-notebook example to
- agents running on many machines.
+ A sweep is a collection of experiments that explores a hyperparameter search
+ space. Here, each trial trains the same MNIST digit classifier with a
+ different batch size and learning rate. Weights & Biases selects the settings, and its
+ Keras integration logs the metrics used to compare trials.
- ## What this notebook covers
+ The workflow has three parts: define the search space, write a function that
+ trains one model using `run.config`, and start an agent to run the trials.
+ This example launches up to ten trials with two epochs each.
- The cells below walk through the core Weights & Biases Sweeps pattern:
+ ## Choose your Weights & Biases project and log in
- * Authenticate with Weights & Biases.
- * Prepare a small TensorFlow image-classification problem.
- * Log training and validation metrics from Keras.
- * Define a sweep configuration for batch size and learning rate.
- * Launch a Weights & Biases agent that runs multiple trials and reports results.
+ Set `entity` to your username or team, or leave it as `None` to use your
+ default entity. The same `project` is used for the sweep, agent, and runs.
+ `wandb.login()` uses existing credentials or prompts for an
+ [API key](https://wandb.ai/authorize). In a hosted notebook, you can also
+ supply the key through the `WANDB_API_KEY` secret.
""")
return
-@app.cell(hide_code=False)
+@app.cell
def _():
- mo.md(r"""
- ## Step 1: Import Weights & Biases and log in
+ entity = None
+ project = "sweeps-tensorflow"
- The next two cells collect your Weights & Biases credentials and call `wandb.login()`.
- Weights & Biases needs an authenticated session before it can create a sweep or sync
- training metrics.
-
- Run the following cell and provide your [Forge API key](https://wandb.ai/authorize) and the name of your team. Then click **Connect to Weights & Biases**.
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- wandb_login_form = (
- mo.md("{api_key}\n\n{entity}")
- .batch(
- api_key=mo.ui.text(
- kind="password",
- label="Forge API key (optional)",
- placeholder="Paste a key or use configured credentials",
- full_width=True,
- ),
- entity=mo.ui.text(
- label="Forge team name (optional)",
- placeholder="Leave blank to use your default entity",
- full_width=True,
- ),
- )
- .form(submit_button_label="Connect to Weights & Biases", bordered=True)
- )
- wandb_login_form
- return (wandb_login_form,)
+ wandb.login()
+ return entity, project
@app.cell(hide_code=True)
-def _(wandb_login_form):
- mo.stop(
- wandb_login_form.value is None,
- mo.callout(
- mo.md("Submit the form above to authenticate before creating a sweep."),
- kind="info",
- ),
- )
-
- _submitted = wandb_login_form.value
- _api_key = _submitted["api_key"].strip()
- try:
- _login_ok = wandb.login(key=_api_key or None, relogin=bool(_api_key))
- except (wandb.errors.Error, ValueError):
- _login_ok = False
-
- mo.stop(
- not _login_ok,
- mo.callout(
- mo.md(
- "Weights & Biases authentication did not complete. Check the API key or "
- "molab Secrets configuration and submit again."
- ),
- kind="danger",
- ),
- )
-
- mo.callout(mo.md("Connected to Weights & Biases."), kind="success")
- return
-
-
-@app.cell(hide_code=False)
def _():
mo.md(r"""
- ## Step 2: Prepare the Dataset
+ ## Prepare data shared by every trial
- The following function loads MNIST, normalizes pixel values, flattens each
- image into a 784-feature vector, and returns `tf.data.Dataset` objects for
- training and validation.
+ MNIST contains 28 × 28 grayscale images with integer labels from 0 to 9.
+ Flatten each image to 784 features and convert pixel values from 0–255 to
+ floating-point values from 0–1.
- The function accepts `batch_size` because the sweep will tune that value. Each
- Weights & Biases trial can therefore build datasets that match the hyperparameters chosen
- for that run.
+ Load and normalize the data once. Use the first 50,000 training examples
+ for fitting and the remaining 10,000 for validation, keeping that split
+ fixed across trials. The official test set is reserved for evaluating the
+ model after hyperparameter selection.
""")
return
-@app.function
-def prepare_datasets(batch_size):
- # Prepare the training dataset
- (x_train, y_train), (x_test, y_test) = keras.datasets.mnist.load_data()
-
- x_train = x_train / 255.0
- x_test = x_test / 255.0
- x_train = np.reshape(x_train, (-1, 784))
- x_test = np.reshape(x_test, (-1, 784))
-
- # build input pipeline using tf.data
- train_dataset = tf.data.Dataset.from_tensor_slices((x_train, y_train))
- train_dataset = (
- train_dataset.shuffle(buffer_size=1024)
- .batch(batch_size)
- .prefetch(buffer_size=tf.data.AUTOTUNE)
- )
-
- val_dataset = tf.data.Dataset.from_tensor_slices((x_test, y_test))
- val_dataset = val_dataset.batch(batch_size).prefetch(buffer_size=tf.data.AUTOTUNE)
- return train_dataset, val_dataset
-
-
-@app.cell(hide_code=False)
+@app.cell
def _():
- mo.md(r"""
- ## Step 3: Define the Model and Training Workflow
-
- The next function builds the TensorFlow model that every sweep trial will
- train. We keep the architecture fixed so the sweep can focus on two
- hyperparameters: batch size and learning rate.
- """)
- return
+ (images, labels), _ = keras.datasets.mnist.load_data()
+ images = images.reshape(-1, 784).astype(np.float32) / 255.0
+ train_images, train_labels = images[:-10000], labels[:-10000]
+ val_images, val_labels = images[-10000:], labels[-10000:]
+ return train_images, train_labels, val_images, val_labels
-@app.function
-def Model():
- inputs = keras.Input(shape=(784,), name="digits")
- x1 = keras.layers.Dense(64, activation="relu")(inputs)
- x2 = keras.layers.Dense(64, activation="relu")(x1)
- outputs = keras.layers.Dense(10, name="predictions")(x2)
- return keras.Model(inputs=inputs, outputs=outputs)
-
-
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 4: Log metrics with `WandbMetricsLogger`
+ ## Keep the model architecture fixed
- The next function wraps `model.fit()` and attaches Weights & Biases's Keras metrics
- logger. `WandbMetricsLogger` receives the training and validation metrics
- produced by Keras and sends them to the active Weights & Biases run.
+ Each trial creates a fresh multilayer perceptron with two hidden layers of
+ 64 ReLU units. The ten outputs are class scores, or logits. The training
+ function will use a loss with `from_logits=True`, so the final layer does
+ not apply softmax.
- With `log_freq=20`, it logs batch metrics every 20 batches and epoch metrics
- at the end of each epoch. Those logged values are what the sweep dashboard
- uses to compare trials.
+ Keeping the architecture fixed lets us compare the effect of the two
+ hyperparameters in the search space.
""")
return
@app.function
-def train(
- train_dataset,
- val_dataset,
- model,
- epochs=10,
- log_step=200,
-):
- # 3️⃣ log metrics using WandbMetricsLogger
- return model.fit(
- train_dataset,
- validation_data=val_dataset,
- epochs=epochs,
- callbacks=[WandbMetricsLogger(log_freq=log_step)],
- verbose=2,
- )
+def build_model():
+ inputs = keras.Input(shape=(784,), name="digits")
+ hidden = keras.layers.Dense(64, activation="relu")(inputs)
+ hidden = keras.layers.Dense(64, activation="relu")(hidden)
+ outputs = keras.layers.Dense(10, name="predictions")(hidden)
+ return keras.Model(inputs=inputs, outputs=outputs)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 5: Configure the Sweep
-
- The next cell defines the sweep configuration dictionary. This is the contract
- between your training code and Weights & Biases: it tells Weights & Biases which hyperparameters to try,
- how to sample them, which metric to optimize, and when to stop weaker runs
- early.
-
- * Define the hyperparameters you're sweeping over.
- * Choose a hyperparameter search method. Weights & Biases supports `random`, `grid`, and `bayes`.
- * Provide an objective metric; here we minimize `epoch/val_loss`, the validation-loss key logged by `WandbMetricsLogger`.
- * Use `hyperband` for early termination of poorly-performing runs.
+ ## Define the search space and objective
+
+ `method="random"` samples a batch size and learning rate from the listed
+ values for each trial. The objective is to minimize `epoch/val_loss`.
+ That exact key is logged by `WandbMetricsLogger` at the end of each epoch;
+ the sweep metric name must match the logged name.
+
+ Hyperband can stop weaker trials early. Its `min_iter=1` sets the first
+ comparison point after one report of the objective metric, which here
+ corresponds to one epoch. Checks happen asynchronously, so these short
+ two-epoch trials may finish before they can be stopped. Longer trials
+ provide more opportunity for early termination.
""")
return
@@ -267,134 +157,157 @@ def _():
def _():
sweep_config = {
"method": "random",
- "metric": {
- "name": "epoch/val_loss",
- "goal": "minimize",
- },
- "early_terminate": {
- "type": "hyperband",
- # Trials run for two epochs, so pruning must be allowed after epoch one.
- "min_iter": 1,
- },
+ "metric": {"name": "epoch/val_loss", "goal": "minimize"},
+ "early_terminate": {"type": "hyperband", "min_iter": 1},
"parameters": {
- "batch_size": {
- "values": [32, 64, 128, 256],
- },
- "learning_rate": {
- "values": [0.01, 0.005, 0.001, 0.0005, 0.0001],
- },
+ "batch_size": {"values": [32, 64, 128, 256]},
+ "learning_rate": {"values": [0.01, 0.005, 0.001, 0.0005, 0.0001]},
},
}
return (sweep_config,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 6: Wrap the Training Workflow
-
- A Weights & Biases agent needs a zero-argument training function. The next function,
- `sweep_train`, is one complete trial: it starts a Weights & Biases run, reads the
- hyperparameters selected for that run from `run.config`, prepares data,
- builds and compiles the model, trains it, and lets Weights & Biases collect metrics.
-
- The defaults passed to `wandb.init()` make the function runnable on its own,
- while sweep-selected values override `batch_size` and `learning_rate` during
- agent runs.
+ ## Define one complete trial
+
+ The agent calls a function with no arguments. Inside `sweep_train`,
+ `wandb.init()` starts the run and supplies default settings; the sweep's
+ selected batch size and learning rate override those defaults in
+ `run.config`. The context manager finishes the run when training ends.
+
+ Each trial resets Keras and uses the same random seed before building a
+ fresh model. The selected batch size controls the `tf.data` pipelines, and
+ the selected learning rate configures SGD. The training dataset shuffles
+ before batching; `model.fit(shuffle=False)` leaves that order to the
+ pipeline. Validation data uses the same examples and order for every trial.
+
+ `WandbMetricsLogger(log_freq=20)` logs batch metrics every 20 batches and
+ training and validation metrics after each epoch. In addition to the
+ optimized `epoch/val_loss`, inspect `epoch/acc` and `epoch/val_acc` for digit
+ classification accuracy. To change the training budget, edit `epochs` in
+ the defaults below.
""")
return
-@app.function
-def sweep_train():
- # Set default values
- config_defaults = {
- "batch_size": 64,
- "learning_rate": 0.01,
- # Specify the other hyperparameters to the configuration, if any
- "epochs": 2,
- "log_step": 20,
- "architecture_name": "MLP",
- "dataset_name": "MNIST",
- }
-
- # Initialize wandb with a sample project name
- # Sweep values overwrite these defaults.
- with wandb.init(config=config_defaults) as run:
- config = run.config
-
- train_dataset, val_dataset = prepare_datasets(config.batch_size)
+@app.cell
+def _(entity, project, train_images, train_labels, val_images, val_labels):
+ def sweep_train():
+ config_defaults = {
+ "batch_size": 64,
+ "learning_rate": 0.01,
+ "epochs": 2,
+ "log_step": 20,
+ "seed": 42,
+ "architecture_name": "MLP",
+ "dataset_name": "MNIST",
+ }
+
+ with wandb.init(entity=entity, project=project, config=config_defaults) as run:
+ config = run.config
+ keras.backend.clear_session()
+ keras.utils.set_random_seed(config.seed)
+
+ train_dataset = (
+ tf.data.Dataset.from_tensor_slices((train_images, train_labels))
+ .shuffle(buffer_size=1024, seed=config.seed)
+ .batch(config.batch_size)
+ .prefetch(tf.data.AUTOTUNE)
+ )
+ val_dataset = (
+ tf.data.Dataset.from_tensor_slices((val_images, val_labels))
+ .batch(config.batch_size)
+ .prefetch(tf.data.AUTOTUNE)
+ )
+
+ model = build_model()
+ model.compile(
+ optimizer=keras.optimizers.SGD(learning_rate=config.learning_rate),
+ loss=keras.losses.SparseCategoricalCrossentropy(from_logits=True),
+ metrics=[keras.metrics.SparseCategoricalAccuracy(name="acc")],
+ )
+ return model.fit(
+ train_dataset,
+ validation_data=val_dataset,
+ epochs=config.epochs,
+ callbacks=[WandbMetricsLogger(log_freq=config.log_step)],
+ shuffle=False,
+ verbose=2,
+ )
+
+ return (sweep_train,)
- # initialize model
- tf.keras.backend.clear_session()
- model = Model()
- # Instantiate an optimizer to train the model.
- optimizer = keras.optimizers.SGD(learning_rate=config.learning_rate)
- # Instantiate a loss function.
- loss_fn = keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ## Register the sweep
- # Prepare the metrics.
- metrics = [keras.metrics.SparseCategoricalAccuracy(name="acc")]
+ `wandb.sweep()` sends the search configuration to Weights & Biases and returns the
+ sweep's ID. This creates the sweep in your chosen entity and project;
+ training begins when an agent starts. Weights & Biases prints a link to the sweep
+ dashboard. Rerunning this cell creates a new sweep.
+ """)
+ return
- model.compile(optimizer=optimizer, loss=loss_fn, metrics=metrics)
- training_history = train(
- train_dataset,
- val_dataset,
- model,
- epochs=config.epochs,
- log_step=config.log_step,
- )
- run_url = run.url
- return {"url": run_url, "epochs": len(training_history.history["loss"])}
+@app.cell
+def _(entity, project, sweep_config):
+ sweep_id = wandb.sweep(sweep_config, entity=entity, project=project)
+ return (sweep_id,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Step 7: Initialize the Sweep and Run an Agent
+ ## Start an agent
- The next cell registers the sweep with Weights & Biases and stores the returned
- `sweep_id`. The cell after that starts a local sweep agent.
+ The agent requests hyperparameters from Weights & Biases and calls `sweep_train` for
+ each trial. `count=10` limits how many trials this agent starts; lower it
+ for a quicker experiment. The call waits while trials run.
- The agent asks Weights & Biases for hyperparameter values, calls `sweep_train` for each
- trial, and repeats until it reaches `count=10`. You can lower `count` while
- experimenting if you want a faster run.
+ To add trials to an existing sweep, use its ID as `sweep_id` and run the
+ agent cell again, keeping the same entity and project. Sweep coordination
+ requires a connection to your Weights & Biases server.
""")
return
@app.cell
-def _(sweep_config):
- sweep_id = wandb.sweep(sweep_config, project="sweeps-tensorflow")
- return (sweep_id,)
-
-
-@app.cell
-def _(sweep_id):
- wandb.agent(sweep_id, function=sweep_train, count=10)
+def _(entity, project, sweep_id, sweep_train):
+ wandb.agent(
+ sweep_id,
+ function=sweep_train,
+ count=10,
+ entity=entity,
+ project=project,
+ )
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Visualize Results
+ ## Verify and compare results
- After the sweep starts, Weights & Biases prints links to the project and sweep dashboards
- in the notebook output. Open those links to watch trials arrive live and
- compare their metrics.
+ Open the sweep link printed during registration. In the runs table, check
+ that `batch_size` and `learning_rate` vary between trials. Each run's config
+ also records the fixed epoch budget, seed, architecture, and dataset.
- ```
- View project at:
- ```
+ Compare `epoch/val_loss` across runs and inspect the corresponding
+ `epoch/val_acc` curves. Use the parallel-coordinates plot to connect
+ hyperparameter choices to validation loss. Parameter importance becomes
+ more informative as you collect more trials. This reference dashboard
+ illustrates the views to look for:
- In the Weights & Biases UI, compare parallel coordinates, parameter importance, and the
- `epoch/val_loss` chart to understand which batch sizes and learning rates
- worked best.
+ 
- https://docs.coreweave.com/products/wandb/sweeps/visualize-sweep-results
+ Try `method="bayes"` or expand the search space, then register a new sweep
+ and compare the results. After selecting hyperparameters, evaluate the
+ chosen model on the reserved test set to estimate performance on unseen
+ data.
""")
return
diff --git a/marimo/convert/intro-to-weights-biases-keras/intro_to_weights_biases_keras.py b/marimo/convert/intro-to-weights-biases-keras/intro_to_weights_biases_keras.py
index d7eb406e..3343604d 100644
--- a/marimo/convert/intro-to-weights-biases-keras/intro_to_weights_biases_keras.py
+++ b/marimo/convert/intro-to-weights-biases-keras/intro_to_weights_biases_keras.py
@@ -5,13 +5,19 @@
# "tensorflow>=2.16,<3",
# "wandb>=0.18,<1",
# ]
+#
+# [tool.marimo.runtime]
+# on_cell_change = "lazy"
# ///
"""Learn the Weights & Biases experiment-tracking workflow with simulated and Keras runs."""
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Introduction to Weights & Biases with Keras")
+app = marimo.App(
+ width="medium",
+ app_title="Introduction to Weights & Biases with Keras",
+)
with app.setup:
from pathlib import Path
@@ -26,15 +32,30 @@
from wandb.integration.keras import WandbMetricsLogger, WandbModelCheckpoint
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Introduction to Weights & Biases with Keras
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/intro-to-weights-biases-keras/intro_to_weights_biases_keras.py/server)
-
-
Use [Weights & Biases](https://wandb.ai/site?utm_source=keras_intro_colab&utm_medium=code&utm_campaign=keras_intro)
for experiment tracking, model checkpointing, and collaboration. This
tutorial starts with simulated metrics, then trains a small Keras classifier,
@@ -46,42 +67,32 @@ def _():
## A shared dashboard for your experiments
- With just a few lines of code, you can create rich, interactive, shareable
+ With few lines of code, you can create rich, interactive, shareable
dashboards like this [example Weights & Biases project](https://wandb.ai/wandb/wandb_example).

- ## Data and privacy
+ ## Authenticate to Weights & Biases
- Weights & Biases encrypts data in transit and at rest. Organizations that need to keep
- data in their own environment can use
- [Weights & Biases Self-Managed](https://docs.wandb.ai/platform/hosting/hosting-options/self-managed).
- You can also query and export logged data with the
- [Weights & Biases Public API](https://docs.wandb.ai/models/ref/python/public-api/).
-
- ## Connect to Weights & Biases
-
- Configure `WANDB_API_KEY` in your environment or molab Secrets, then run
- `wandb.login()` below. Get a key from [Weights & Biases](https://wandb.ai/authorize).
- Terminal-backed sessions can also prompt for a key. A new molab session
- does not inherit credentials from your computer.
-
- Set `entity` to your team name, or keep `None` for your default entity. The two projects separate simulated metrics from real Keras training.
+ Set `entity` to your Weights & Biases team name, or leave it as `None` to use your
+ default entity. `wandb.login()` uses
+ your saved credentials or prompts for an [API key](https://wandb.ai/authorize).
+ In a locally hosted notebook, you can also set the `WANDB_API_KEY` secret.
""")
return
@app.cell
def _():
- entity = "wandb"
+ entity = None
simulation_project = "basic-intro"
training_project = "keras-intro"
- if not wandb.login():
- raise RuntimeError("Configure Weights & Biases credentials before running the lesson.")
+
+ wandb.login()
return entity, simulation_project, training_project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Run simulated experiments
@@ -124,36 +135,28 @@ def _(entity, simulation_project):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## Train a simple Keras classifier
+ ## Train a Keras classifier
This example downloads MNIST, trains a small dense classifier, and streams
- metrics to Weights & Biases. It uses the current dedicated callbacks:
+ metrics to Weights & Biases. Two callbacks handle the logging:
- `WandbMetricsLogger` records Keras training and validation metrics.
- `WandbModelCheckpoint` saves each epoch's model and logs it as a Weights & Biases Artifact.
- The former all-in-one `WandbCallback` is
- [legacy](https://docs.wandb.ai/models/integrations/keras); new workflows
- should select the dedicated callback for each behavior they need.
-
Checkpoints are written to a temporary directory and removed after Weights & Biases has
finished the run, so rerunning this notebook does not leave model files in
the repository.
- """)
- return
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
### Configure the experiments
- Edit the settings below to control training time. We train five fresh models
- with different, reproducibly sampled dropout rates. Weights & Biases records each model's
- settings so you can compare dropout against validation loss and accuracy.
+ The dictionary below defines the model's layers, optimizer, and training
+ settings. We train five fresh models with reproducibly sampled dropout
+ rates. Weights & Biases records each model's settings so you can compare
+ dropout against validation loss and accuracy. Reduce `experiment_count`
+ or `epochs` for a quicker run.
""")
return
@@ -179,7 +182,7 @@ def _():
return dropout_values, training_config
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Prepare MNIST once
@@ -202,7 +205,7 @@ def _():
return x_train, x_validation, y_train, y_validation
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Train and log with Keras callbacks
@@ -270,7 +273,7 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Inspect your results
@@ -284,7 +287,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Try Weights & Biases Alerts
@@ -294,48 +297,34 @@ def _():
trying this section, enable **Scriptable run alerts** and configure a
destination in your Weights & Biases user settings.
- The demo logs synthetic accuracy values and calls `alert_run.alert()` on the
- first value at or below the threshold. Edit the Python settings below, then
- click **Run demo and send alert if triggered**. This creates one run and may
- send a real Slack or email notification. It is independent of the MNIST results.
+ The next cell logs synthetic accuracy values between zero and one. The
+ first value at or below `accuracy_threshold` triggers `alert_run.alert()`
+ and ends the loop. These values are independent of the MNIST results.
+
+ Set the threshold and random seed below, then run the cell to create an
+ alert-demo run. With notifications configured, this can send a real Slack
+ or email alert. `wait_duration=300` limits repeated alerts with the same
+ title to one every five minutes.
""")
return
@app.cell
-def _():
+def _(entity, training_project):
accuracy_threshold = 0.3
max_alert_steps = 1000
alert_seed = 7
- return accuracy_threshold, alert_seed, max_alert_steps
-
-@app.cell
-def _():
- send_alert = mo.ui.run_button(label="Run demo and send alert if triggered")
- send_alert
- return (send_alert,)
-
-
-@app.cell
-def _(
- accuracy_threshold,
- alert_seed,
- entity,
- max_alert_steps,
- send_alert,
- training_project,
-):
- mo.stop(not send_alert.value)
alert_rng = random.Random(alert_seed)
with wandb.init(
entity=entity,
project=training_project,
name="keras-low-accuracy-alert-demo",
job_type="alert-demo",
+ config={"accuracy_threshold": accuracy_threshold, "seed": alert_seed},
) as alert_run:
for alert_step in range(max_alert_steps):
- alert_accuracy = round(alert_rng.random() + alert_rng.random(), 3)
+ alert_accuracy = round(alert_rng.random(), 3)
alert_run.log({"step": alert_step, "accuracy": alert_accuracy})
if alert_accuracy <= accuracy_threshold:
alert_run.alert(
@@ -354,10 +343,21 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## What's next?
+ ## Verify and next steps
+
+ In your W&B workspace, check:
+
+ - **`basic-intro`**: each simulation has eight logged accuracy and loss values.
+ - **`keras-intro`**: compare `dropout` in each training run's config with
+ `epoch/val_loss`, `epoch/val_accuracy`, and `final_validation_accuracy`.
+ Open a training run's **Artifacts** tab to find its per-epoch Keras models.
+ - **Alert demo**: inspect the accuracy history in the run named
+ `keras-low-accuracy-alert-demo`. With the default seed, the second value
+ crosses the threshold. Check your configured notification destination
+ for the warning.
Continue with
[Organizing hyperparameter sweeps in PyTorch](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py/server)
diff --git a/marimo/convert/intro-to-weights-biases/intro_to_weights_biases.py b/marimo/convert/intro-to-weights-biases/intro_to_weights_biases.py
index 6ad7976c..b09faf72 100644
--- a/marimo/convert/intro-to-weights-biases/intro_to_weights_biases.py
+++ b/marimo/convert/intro-to-weights-biases/intro_to_weights_biases.py
@@ -6,6 +6,9 @@
# "torchvision>=0.16",
# "wandb>=0.18",
# ]
+#
+# [tool.marimo.runtime]
+# on_cell_change = "lazy"
# ///
import marimo
@@ -31,14 +34,29 @@
]
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- # Intro to Weights & Biases
+
+
+
+
-
+ # Introduction to Weights & Biases
+
+ [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/intro-to-weights-biases/intro_to_weights_biases.py/server)
A Weights & Biases run records one experiment's configuration, metrics, and outputs.
This lesson starts with simulated metrics, then tracks real PyTorch training,
@@ -47,23 +65,14 @@ def _():
## 1. Authenticate
- Open the notebook with its declared dependencies:
-
- ```bash
- uvx marimo edit --sandbox intro_to_weights_biases.py
- ```
-
- The next cell calls `wandb.login()` and selects the projects used by the
- two examples. Set `entity` to your team name, or use `None` for your
- default entity.
-
- Configure `WANDB_API_KEY` in your environment or molab Secrets. Get a key
- from [Weights & Biases](https://wandb.ai/authorize), or
- [create an account](https://wandb.ai/signup). Terminal-backed sessions can
- also prompt for a key.
+ Set `entity` to your Weights & Biases team name, or leave it as `None` to use your
+ default entity. `wandb.login()` uses
+ your saved credentials or prompts for an [API key](https://wandb.ai/authorize).
+ In a locally hosted notebook, you can also set the `WANDB_API_KEY` secret.
Running the code cells creates experiment runs, downloads MNIST, and uploads
- metrics and checkpoints. The optional alert requires a separate click.
+ metrics and checkpoints. The optional alert has its own Python setting
+ near the end of the lesson.
""")
return
@@ -73,12 +82,12 @@ def _():
entity = None
simulation_project = "basic-intro"
training_project = "pytorch-intro"
- if not wandb.login():
- raise RuntimeError("Configure Weights & Biases credentials before running the lesson.")
+
+ wandb.login()
return entity, simulation_project, training_project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 2. Track Simulated Experiments
@@ -96,7 +105,6 @@ def _():
@app.cell
def _(entity, simulation_project):
- simulation_run_urls = []
for experiment_index in range(5):
simulation_config = {"epochs": 10, "seed": experiment_index, "dataset": "synthetic"}
simulation_rng = random.Random(simulation_config["seed"])
@@ -115,16 +123,18 @@ def _(entity, simulation_project):
"acc": simulated_accuracy,
"loss": simulated_loss,
})
- simulation_run_urls.append(simulation_run.url)
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 3. Compare runs in your project
- Open any run returned as stdout in the previous cell. [Compare accuracy and loss across experiments](https://docs.coreweave.com/products/wandb/runs/compare-runs). Each run has its own configuration and metric history.
+ Open a run link printed by Weights & Biases in the previous cell. In the `basic-intro`
+ project, select the five simulation runs and compare their `acc` and `loss`
+ curves. Choose `epoch` as the horizontal axis to compare the same training
+ point across runs. Inspect each run's config to see its seed and epoch count.
Next, we apply the same logging pattern to a real MNIST classifier.
@@ -157,101 +167,118 @@ def _():
return device, dropout_values, training_config
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- ## 5. Define the Data, Model, and Evaluation Helpers
-
- The following helpers contain ordinary PyTorch code. They load sampled
- MNIST batches, build an MLP, and evaluate loss and accuracy.
+ ## 5. Load MNIST batches
- Validation also returns the first batch's images, predictions, labels, and
- class probabilities for a Weights & Biases prediction table. Its order stays fixed across
- runs. We use `num_workers=0` for compatibility with notebook runtimes.
+ `get_dataloader()` loads MNIST into temporary storage and selects every
+ `sample_stride`-th image. `ToTensor()` converts each grayscale image to a
+ tensor with pixel values between 0 and 1.
- Defining these helpers does not download data or train a model.
+ Training batches are shuffled; validation batches retain the same order
+ across runs so we can compare predictions on the same images. Calling
+ this helper downloads missing data. `num_workers=0` works across notebook
+ runtimes, and pinned memory helps transfer batches to CUDA when available.
""")
return
-@app.cell
-def get_dataloader(device):
- def get_dataloader(is_train, batch_size, sample_stride):
- dataset = MNIST(
- root=Path(tempfile.gettempdir()) / "wandb-intro-mnist",
- train=is_train,
- transform=T.ToTensor(),
- download=True,
- )
- sampled_dataset = torch.utils.data.Subset(
- dataset, indices=range(0, len(dataset), sample_stride),
- )
- return torch.utils.data.DataLoader(
- sampled_dataset,
- batch_size=batch_size,
- shuffle=is_train,
- pin_memory=device.startswith("cuda"),
- num_workers=0,
- )
+@app.function
+def get_dataloader(is_train, batch_size, sample_stride):
+ dataset = MNIST(
+ root=Path(tempfile.gettempdir()) / "wandb-intro-mnist",
+ train=is_train,
+ transform=T.ToTensor(),
+ download=True,
+ )
+ sampled_dataset = torch.utils.data.Subset(
+ dataset, indices=range(0, len(dataset), sample_stride),
+ )
+ return torch.utils.data.DataLoader(
+ sampled_dataset,
+ batch_size=batch_size,
+ shuffle=is_train,
+ pin_memory=torch.cuda.is_available(),
+ num_workers=0,
+ )
- return (get_dataloader,)
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ### Build a classifier to compare dropout rates
-@app.cell
-def get_model(device):
- def get_model(dropout):
- return nn.Sequential(
- nn.Flatten(),
- nn.Linear(28 * 28, 256),
- nn.BatchNorm1d(256),
- nn.ReLU(),
- nn.Dropout(dropout),
- nn.Linear(256, 10),
- ).to(device)
+ The MLP flattens each 28-by-28 image, learns 256 hidden features, and outputs
+ ten logits, one per digit. Cross-entropy loss accepts these logits directly.
+ `dropout` controls how many hidden activations are randomly zeroed during
+ training. Each call creates a fresh model on the selected device.
+ """)
+ return
- return (get_model,)
+@app.function
+def get_model(dropout, device):
+ return nn.Sequential(
+ nn.Flatten(),
+ nn.Linear(28 * 28, 256),
+ nn.BatchNorm1d(256),
+ nn.ReLU(),
+ nn.Dropout(dropout),
+ nn.Linear(256, 10),
+ ).to(device)
+
+
+@app.cell(hide_code=True)
+def _():
+ mo.md(r"""
+ ### Evaluate on the held-out images
-@app.cell
-def evaluate_model(device):
- def evaluate_model(model, validation_loader, loss_function):
- model.eval()
- loss_sum = 0.0
- correct = 0
- prediction_batch = None
- with torch.inference_mode():
- for batch_index, (images, labels) in enumerate(validation_loader):
- images, labels = images.to(device), labels.to(device)
- outputs = model(images)
- predictions = outputs.argmax(dim=1)
- loss_sum += loss_function(outputs, labels).item() * len(labels)
- correct += (predictions == labels).sum().item()
- if batch_index == 0:
- prediction_batch = (
- images.cpu(), predictions.cpu(), labels.cpu(),
- outputs.softmax(dim=1).cpu(),
- )
- return (
- loss_sum / len(validation_loader.dataset),
- correct / len(validation_loader.dataset),
- prediction_batch,
- )
+ `model.eval()` turns off dropout and uses batch normalization's learned
+ statistics. `torch.inference_mode()` avoids tracking gradients during
+ validation. The helper averages loss by image count, so a smaller final
+ batch contributes the correct weight, and computes accuracy across the
+ entire validation subset.
- return (evaluate_model,)
+ It also returns the first batch's images, predictions, labels, and softmax
+ probabilities on the CPU. We will use that fixed batch to build a Weights & Biases Table.
+ """)
+ return
+
+
+@app.function
+def evaluate_model(model, validation_loader, loss_function, device):
+ model.eval()
+ loss_sum = 0.0
+ correct = 0
+ prediction_batch = None
+ with torch.inference_mode():
+ for batch_index, (images, labels) in enumerate(validation_loader):
+ images, labels = images.to(device), labels.to(device)
+ outputs = model(images)
+ predictions = outputs.argmax(dim=1)
+ loss_sum += loss_function(outputs, labels).item() * len(labels)
+ correct += (predictions == labels).sum().item()
+ if batch_index == 0:
+ prediction_batch = (
+ images.cpu(), predictions.cpu(), labels.cpu(),
+ outputs.softmax(dim=1).cpu(),
+ )
+ return (
+ loss_sum / len(validation_loader.dataset),
+ correct / len(validation_loader.dataset),
+ prediction_batch,
+ )
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 6. Build a Prediction Table
- The next helper creates a `wandb.Table` with one row per image. Each row
+ The next helper functions creates a `wandb.Table` with one row per image. Each row
contains a viewable `wandb.Image`, the predicted digit, the true label,
and ten class probabilities.
-
- This function builds the table; the training cell logs it to the active run
- after the final validation pass. In Weights & Biases, filter rows where `pred != target`
- to inspect mistakes.
""")
return
@@ -263,7 +290,7 @@ def make_prediction_table(images, predictions, labels, probabilities):
)
for image, prediction, label, scores in zip(images, predictions, labels, probabilities):
prediction_table.add_data(
- wandb.Image(image[0].numpy() * 255),
+ wandb.Image(image),
prediction.item(),
label.item(),
*scores.tolist(),
@@ -271,7 +298,7 @@ def make_prediction_table(images, predictions, labels, probabilities):
return prediction_table
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 7. Train, Log Metrics, and Save Checkpoints
@@ -283,7 +310,8 @@ def _():
epoch, and a prediction table after the final epoch. The scalar summary
`final_validation_accuracy` makes the final result easy to compare across runs.
- At each epoch, `torch.save(model.state_dict(), ...)` saves model weights.
+ At each epoch, `torch.save(model.state_dict(), ...)` saves model weights
+ to a separate file so later epochs cannot overwrite an earlier checkpoint.
`training_run.log_model()` uploads that checkpoint as a model Artifact with
an epoch alias. The model architecture and dropout are recorded in the run
configuration; recreate that architecture before loading its weights.
@@ -294,16 +322,7 @@ def _():
@app.cell
-def _(
- device,
- dropout_values,
- entity,
- evaluate_model,
- get_dataloader,
- get_model,
- training_config,
- training_project,
-):
+def _(device, dropout_values, entity, training_config, training_project):
for dropout in dropout_values:
torch.manual_seed(training_config["seed"])
with tempfile.TemporaryDirectory(prefix="wandb-mnist-checkpoints-") as checkpoint_directory:
@@ -315,7 +334,7 @@ def _(
run_config = training_run.config
train_loader = get_dataloader(True, run_config.batch_size, run_config.sample_stride)
validation_loader = get_dataloader(False, 2 * run_config.batch_size, run_config.sample_stride)
- model = get_model(run_config.dropout)
+ model = get_model(run_config.dropout, device)
loss_function = nn.CrossEntropyLoss()
optimizer = torch.optim.Adam(model.parameters(), lr=run_config.lr)
example_count = 0
@@ -337,7 +356,7 @@ def _(
})
validation_loss, validation_accuracy, prediction_batch = evaluate_model(
- model, validation_loader, loss_function,
+ model, validation_loader, loss_function, device,
)
validation_metrics = {
"epoch": epoch + 1,
@@ -348,7 +367,7 @@ def _(
validation_metrics["predictions_table"] = make_prediction_table(*prediction_batch)
training_run.log(validation_metrics)
- checkpoint_path = Path(checkpoint_directory) / "model_weights.pt"
+ checkpoint_path = Path(checkpoint_directory) / f"model_weights_epoch_{epoch + 1}.pt"
torch.save(model.state_dict(), checkpoint_path)
training_run.log_model(
str(checkpoint_path),
@@ -364,48 +383,53 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 8. Inspect Metrics, Predictions, and Models
- Compare dropout settings against validation loss and accuracy in your project.
- Open a run's `predictions_table` to inspect images and class scores.
- In **Artifacts**, find its saved model weights and epoch aliases.
-
- Each run also records terminal output and available system metrics, which
- can help explain differences in runtime.
+ In the `pytorch-intro` project, compare the three runs' `val/val_loss` and
+ `val/val_accuracy` curves. Use the config column `dropout` to identify each
+ experiment and `final_validation_accuracy` to compare their final results.
+ Open a run's `predictions_table` and filter `pred != target` to inspect
+ mistakes alongside the ten class probabilities. In **Artifacts**, open its
+ `mnist-` model collection and inspect the versions with `epoch-1`,
+ `epoch-2`, and later aliases.
## 9. Optional: Send an Alert
- The next two cells demonstrate `alert_run.alert()`. Enable notifications
- in your [Weights & Biases user settings](https://wandb.ai/settings), then click
- **Send example alert** to create a separate run and test the notification.
+ The next cell demonstrates `alert_run.alert()`. To try it, enable notifications
+ in your [Weights & Biases user settings](https://wandb.ai/settings) and change
+ `send_example_alert` to `True`. This creates a separate run and can send a
+ real notification through the email or Slack settings you configured.
We log three synthetic accuracy values. The final value crosses a threshold
of 0.3 and triggers an alert. This is independent of the MNIST results and
- can send a real email or Slack notification through your Weights & Biases settings.
+ does not run until you opt in with the Python setting below.
""")
return
@app.cell
def _(entity, training_project):
- with wandb.init(project=training_project, entity=entity, job_type="alert-demo") as alert_run:
- accuracy_threshold = 0.3
- for alert_step, alert_accuracy in enumerate([0.8, 0.65, 0.25]):
- alert_run.log({"step": alert_step, "accuracy": alert_accuracy})
- if alert_accuracy < accuracy_threshold:
- alert_run.alert(
- title="Low accuracy",
- text=f"Demo accuracy {alert_accuracy} is below {accuracy_threshold} at step {alert_step}.",
- )
- print(f"Alert triggered: {alert_run.url}")
- break
+ send_example_alert = False
+
+ if send_example_alert:
+ with wandb.init(project=training_project, entity=entity, job_type="alert-demo") as alert_run:
+ accuracy_threshold = 0.3
+ for alert_step, alert_accuracy in enumerate([0.8, 0.65, 0.25]):
+ alert_run.log({"step": alert_step, "accuracy": alert_accuracy})
+ if alert_accuracy < accuracy_threshold:
+ alert_run.alert(
+ title="Low accuracy",
+ text=f"Demo accuracy {alert_accuracy} is below {accuracy_threshold} at step {alert_step}.",
+ )
+ print(f"Alert triggered: {alert_run.url}")
+ break
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Next Steps
From 5ca65a8e5a0871925310ee22bcb3c46b4126a034 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Mon, 19 Oct 2026 21:34:29 -0700
Subject: [PATCH 35/48] update wb and cw image
---
.../credit_scorecards_with_xgboost_and_w_b.py | 19 +++-
.../custom_progress_callback.py | 17 ++++
.../huggingface-wandb/huggingface_wandb.py | 17 ++++
marimo/convert/lcm-diffusers/lcm_diffusers.py | 6 +-
.../log_a_confusion_matrix_with_w_b.py | 36 ++++++--
.../log_almost_anything_with_w_b_media.py | 26 +++---
...hugging_face_models_with_weights_biases.py | 91 +++++++------------
...ch_lightning_models_with_weights_biases.py | 42 ++++++---
...perparameter_sweeps_in_pytorch_with_w_b.py | 43 ++++++---
.../pipeline_versioning_with_w_b_artifacts.py | 19 +++-
.../plot_roc_curves_with_w_b.py | 26 +++++-
.../report_api_quickstart.py | 50 ++++++----
.../convert/run-quickstart/run_quickstart.py | 17 ++++
.../simple_pytorch_integration.py | 43 ++++++---
.../torchtune_and_wandb.py | 34 +++++--
...debug_yolov5_models_with_weights_biases.py | 33 +++++--
...andbevalcallback_in_your_keras_workflow.py | 40 ++++++--
...andbmetriclogger_in_your_keras_workflow.py | 22 ++++-
...bmodelcheckpoint_in_your_keras_workflow.py | 22 ++++-
.../using_w_b_sweeps_with_xgboost.py | 22 ++++-
.../w_b_tables_quickstart.py | 32 +++----
..._artifacts_time_to_live_ttl_walkthrough.py | 27 ++++--
22 files changed, 483 insertions(+), 201 deletions(-)
diff --git a/marimo/convert/credit-scorecards-with-xgboost-and-w-b/credit_scorecards_with_xgboost_and_w_b.py b/marimo/convert/credit-scorecards-with-xgboost-and-w-b/credit_scorecards_with_xgboost_and_w_b.py
index 019b01e5..c0996dd6 100644
--- a/marimo/convert/credit-scorecards-with-xgboost-and-w-b/credit_scorecards_with_xgboost_and_w_b.py
+++ b/marimo/convert/credit-scorecards-with-xgboost-and-w-b/credit_scorecards_with_xgboost_and_w_b.py
@@ -41,12 +41,27 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Vehicle Loan Default Prediction with XGBoost and Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/credit-scorecards-with-xgboost-and-w-b/credit_scorecards_with_xgboost_and_w_b.py/server)
-
-
This lesson tracks a classification pipeline from raw data to trained model.
We use Weights & Biases Artifacts to record dataset lineage, Tables to inspect sample rows,
the XGBoost callback to log training, and Sweeps to compare hyperparameters.
diff --git a/marimo/convert/custom-progress-callback/custom_progress_callback.py b/marimo/convert/custom-progress-callback/custom_progress_callback.py
index d93d870b..c1b7f021 100644
--- a/marimo/convert/custom-progress-callback/custom_progress_callback.py
+++ b/marimo/convert/custom-progress-callback/custom_progress_callback.py
@@ -43,6 +43,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Visualize LLM training progress with Weights & Biases Tables
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/custom-progress-callback/custom_progress_callback.py/server)
diff --git a/marimo/convert/huggingface-wandb/huggingface_wandb.py b/marimo/convert/huggingface-wandb/huggingface_wandb.py
index 48bbb60d..cfd50f1a 100644
--- a/marimo/convert/huggingface-wandb/huggingface_wandb.py
+++ b/marimo/convert/huggingface-wandb/huggingface_wandb.py
@@ -38,6 +38,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Hugging Face + Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/huggingface-wandb/huggingface_wandb.py/server)
diff --git a/marimo/convert/lcm-diffusers/lcm_diffusers.py b/marimo/convert/lcm-diffusers/lcm_diffusers.py
index 81c8383b..37a8563f 100644
--- a/marimo/convert/lcm-diffusers/lcm_diffusers.py
+++ b/marimo/convert/lcm-diffusers/lcm_diffusers.py
@@ -27,7 +27,7 @@
MODEL_ID = "SimianLuo/LCM_Dreamshaper_v7"
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
# Image Generation with Consistency Models using Diffusers
@@ -45,7 +45,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Authentication
@@ -128,7 +128,7 @@ def _(wandb_login_form):
return hf_token, wandb_settings
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Generate and log images
diff --git a/marimo/convert/log-a-confusion-matrix-with-w-b/log_a_confusion_matrix_with_w_b.py b/marimo/convert/log-a-confusion-matrix-with-w-b/log_a_confusion_matrix_with_w_b.py
index 25da7014..48f2317c 100644
--- a/marimo/convert/log-a-confusion-matrix-with-w-b/log_a_confusion_matrix_with_w_b.py
+++ b/marimo/convert/log-a-confusion-matrix-with-w-b/log_a_confusion_matrix_with_w_b.py
@@ -17,7 +17,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Plot a Confusion Matrix with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="Plot a Confusion Matrix with Weights & Biases",
+)
with app.setup:
import shutil
@@ -44,9 +47,26 @@
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Plot a Confusion Matrix with Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/log-a-confusion-matrix-with-w-b/log_a_confusion_matrix_with_w_b.py/server)
@@ -79,7 +99,7 @@ def _():
return (entity,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Configure the experiment
@@ -115,7 +135,7 @@ def _():
return entity, project, training_config
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Prepare the iNaturalist sample
@@ -179,7 +199,7 @@ def _(dataset_fs):
return train_data, val_data
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Build the data generators and model
@@ -256,7 +276,7 @@ def build_model(fc_size, num_classes):
return model
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Log a confusion matrix after each epoch
@@ -302,7 +322,7 @@ def on_epoch_end(self, epoch, logs=None):
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train and save the results to Weights & Biases
@@ -371,7 +391,7 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Open the run in Weights & Biases App UI and find `conf_mat` in the **Custom Charts** panel.
diff --git a/marimo/convert/log-almost-anything-with-w-b-media/log_almost_anything_with_w_b_media.py b/marimo/convert/log-almost-anything-with-w-b-media/log_almost_anything_with_w_b_media.py
index 96d81ae8..5c9832dc 100644
--- a/marimo/convert/log-almost-anything-with-w-b-media/log_almost_anything_with_w_b_media.py
+++ b/marimo/convert/log-almost-anything-with-w-b-media/log_almost_anything_with_w_b_media.py
@@ -27,7 +27,7 @@
import wandb
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
- # Optimize Hugging Face models with Weights & Biases
- """)
- return
+
+
+ [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/optimize-hugging-face-models-with-weights-biases/optimize_hugging_face_models_with_weights_biases.py/server)
+
+ # Optimize Hugging Face models with Weights & Biases
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
[Hugging Face](https://huggingface.co/) provides tools to quickly train neural networks for NLP (Natural Language Processing) on any task (classification, translation, question answering, etc) and any dataset with PyTorch and TensorFlow 2.0.
Coupled with [Weights & Biases integration](https://docs.wandb.ai/models/integrations/huggingface_transformers), you can quickly train and monitor models for full traceability and reproducibility without any extra line of code! The notebook metadata provides the libraries; configure Weights & Biases credentials below before starting an experiment.
**Note**: To enable logging to Weights & Biases, set `report_to` to `wandb` in your `TrainingArguments` or script.
- """)
- return
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
Weights & Biases integration with 🤗 Hugging Face can automatically:
* log your configuration parameters
* log your losses and metrics
@@ -90,23 +87,6 @@ def _():
* log your model
* keep track of your code
* log your system metrics (GPU, CPU, memory, temperature, etc)
- """)
- return
-
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
- ## Here's what the Weights & Biases interactive dashboard will look like:
-
- 
- """)
- return
-
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
## Installation and set-up
We need the following 🤗 Hugging Face libraries:
@@ -122,7 +102,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Configure Weights & Biases and authenticate
@@ -137,9 +117,8 @@ def _():
`WANDB_WATCH="all"` enables gradient and parameter histograms. Both examples
enable metrics with `report_to="wandb"` and give the run a descriptive name.
- Running the quick example downloads BERT and MRPC, then starts a 300-step
- training run. The custom example downloads Yahoo! Answers and DistilBERT;
- its 30,000-step training run has a separate action button.
+ > Note: Running this notebook downloads BERT and MRPC, then starts a 300-step
+ training run. The custom example downloads Yahoo! Answers and DistilBERT.
""")
return
@@ -155,7 +134,7 @@ def _():
return entity, project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train with an existing Hugging Face script
@@ -246,24 +225,16 @@ def _(
check=True,
)
quick_training_complete = quick_training_process.returncode == 0
- return (quick_training_complete,)
+ return
@app.cell(hide_code=True)
-def _(quick_training_complete):
- mo.md(f"""
- Quick training completed: **{quick_training_complete}**.
-
+def _():
+ mo.md(r"""
Open the Weights & Biases run link printed by the script to inspect training loss, MRPC
evaluation metrics, and system telemetry. Open the run's **Artifacts** tab
to find the saved model and its evaluation metadata.
- """)
- return
-
-@app.cell(hide_code=False)
-def _():
- mo.md(r"""
## Advanced usage: customize a Trainer workflow
Now build a topic classifier with DistilBERT and Yahoo! Answers. This path
@@ -302,7 +273,7 @@ def _():
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Load and inspect the dataset
@@ -338,7 +309,7 @@ def _(dataset):
return label_names, num_labels
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Rename `topic` to `labels`, the target column expected by `Trainer`. Keep the
@@ -354,7 +325,7 @@ def _(dataset):
return (labeled_dataset,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Tokenize the text
@@ -395,7 +366,7 @@ def _(labeled_dataset, tokenizer):
return (tokenized_dataset,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Load a model and inspect an initial prediction
@@ -443,7 +414,7 @@ def _(tokenizer, untrained_model):
return initial_topic_prediction, sample_sentence
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Define an evaluation metric
@@ -463,7 +434,7 @@ def compute_metrics(eval_pred):
return {"accuracy": float(np.mean(predictions == labels))}
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Configure training and Weights & Biases logging
@@ -555,7 +526,7 @@ def _(
return (trained_model,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Predict with the trained model
diff --git a/marimo/convert/optimize-pytorch-lightning-models-with-weights-biases/optimize_pytorch_lightning_models_with_weights_biases.py b/marimo/convert/optimize-pytorch-lightning-models-with-weights-biases/optimize_pytorch_lightning_models_with_weights_biases.py
index 070b22b1..0ca566bc 100644
--- a/marimo/convert/optimize-pytorch-lightning-models-with-weights-biases/optimize_pytorch_lightning_models_with_weights_biases.py
+++ b/marimo/convert/optimize-pytorch-lightning-models-with-weights-biases/optimize_pytorch_lightning_models_with_weights_biases.py
@@ -13,7 +13,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="PyTorch Lightning with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="PyTorch Lightning with Weights & Biases",
+)
with app.setup:
from pathlib import Path
@@ -33,9 +36,26 @@
from torchvision.datasets import MNIST
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# PyTorch Lightning models with Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/optimize-pytorch-lightning-models-with-weights-biases/optimize_pytorch_lightning_models_with_weights_biases.py/server)
@@ -63,7 +83,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Configure the experiment and authenticate
@@ -94,7 +114,7 @@ def _():
return batch_size, entity, epochs, project, run_name, seed
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Set up the dataloaders
@@ -128,7 +148,7 @@ def _(batch_size, seed):
return training_loader, validation_loader
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Defining the Model
@@ -226,7 +246,7 @@ def _get_preds_loss_accuracy(self, batch):
return preds, loss, acc
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Save Model Checkpoints
@@ -257,7 +277,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Using WandbLogger to log Images, Text and More
@@ -315,7 +335,7 @@ def on_validation_batch_end(
wandb_logger.log_table(key="sample_table", columns=columns, data=data)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train the model and log to Weights & Biases
@@ -386,7 +406,7 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify and next steps
@@ -405,7 +425,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
We can monitor losses, metrics, gradients, parameters and sample predictions as the model trains.
@@ -415,7 +435,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Resources
diff --git a/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py b/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py
index d0a7bd60..a57e2102 100644
--- a/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py
+++ b/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py
@@ -41,19 +41,34 @@
data_root = Path(tempfile.gettempdir()) / "wandb-pytorch-sweeps-mnist"
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Organizing Hyperparameter Sweeps in PyTorch with Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/organizing-hyperparameter-sweeps-in-pytorch-with-w-b/organizing_hyperparameter_sweeps_in_pytorch_with_w_b.py/server)
-
-
""")
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Finding a machine learning model that meets your desired metric (such as model accuracy) is normally a redundant task that can take multiple iterations. To make matters worse, it might be unclear which hyperparameter combinations to use for a given training run.
@@ -79,7 +94,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Authenticate and choose a project
@@ -107,7 +122,7 @@ def _():
return entity, project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Step 1: Define a sweep
@@ -162,7 +177,7 @@ def _():
return (sweep_config,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Step 2: Initialize the sweep
@@ -184,7 +199,7 @@ def _(entity, project, sweep_config):
return (sweep_id,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Step 3: Define the PyTorch training code
@@ -263,7 +278,7 @@ def train_epoch(sweep_run, network, loader, optimizer):
return total_loss / total_examples
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Connect one trial to Weights & Biases
@@ -297,7 +312,7 @@ def train():
sweep_run.log({"loss": avg_loss, "epoch": epoch})
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Step 4: Run a sweep agent
@@ -333,7 +348,7 @@ def _(entity, project, sweep_id, trial_count):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify and visualize sweep results
@@ -347,7 +362,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Parallel Coordinates Plot
@@ -358,7 +373,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Hyperparameter Importance Plot
@@ -372,7 +387,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Learn more about Weights & Biases Sweeps
diff --git a/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py b/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py
index 873c6b02..0bea9fc2 100644
--- a/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py
+++ b/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py
@@ -35,9 +35,24 @@ def _():
@app.cell(hide_code=True)
def _(mo):
mo.md(r"""
- [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py/server)
+
+
+
+
+
+ [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/pipeline-versioning-with-w-b-artifacts/pipeline_versioning_with_w_b_artifacts.py/server)
# Pipeline Versioning with Weights & Biases Artifacts
diff --git a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
index 5f307b5d..0df9f66d 100644
--- a/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
+++ b/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py
@@ -17,8 +17,11 @@
import marimo
-__generated_with = "0.24.2"
-app = marimo.App(width="medium", app_title="Plot ROC Curves with Weights & Biases")
+__generated_with = "0.25.1"
+app = marimo.App(
+ width="medium",
+ app_title="Plot ROC Curves with Weights & Biases",
+)
with app.setup:
import shutil
@@ -48,6 +51,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Plot ROC Curves with Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/plot-roc-curves-with-w-b/plot_roc_curves_with_w_b.py/server)
@@ -310,7 +330,7 @@ def _(config, entity, model, project, train_generator, validation_generator):
ROCCurveLogger(run, validation_generator),
],
)
- return (history,)
+ return
@app.cell(hide_code=True)
diff --git a/marimo/convert/report-api-quickstart/report_api_quickstart.py b/marimo/convert/report-api-quickstart/report_api_quickstart.py
index 6f8276f8..3488084a 100644
--- a/marimo/convert/report-api-quickstart/report_api_quickstart.py
+++ b/marimo/convert/report-api-quickstart/report_api_quickstart.py
@@ -12,7 +12,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Weights & Biases Report API Quickstart")
+app = marimo.App(
+ width="medium",
+ app_title="Weights & Biases Report API Quickstart",
+)
with app.setup:
import math
@@ -26,15 +29,30 @@
from PIL import Image
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Weights & Biases Report API Quickstart
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/report-api-quickstart/report_api_quickstart.py/server)
-
-
Use Workspaces and Reports API ([wandb-workspaces](https://github.com/wandb/wandb-workspaces)) to create and
customize Weights & Biases Reports. A report combines narrative **blocks** with **panel grids**:
runsets select experiment data, and panels visualize that data.
@@ -57,7 +75,7 @@ def _():
return entity, project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 2. Create data for the panels
@@ -82,7 +100,7 @@ def _():
return demo_colors, demo_rng, demo_run_colors, demo_run_names
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
The next cell initializes three different loops:
@@ -167,7 +185,7 @@ def _(demo_colors, demo_rng, demo_run_colors, demo_run_names, entity, project):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Now that you have logged some runs, lets create a report.
@@ -195,7 +213,7 @@ def _():
return (text_blocks,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Panel grids and run colors
@@ -233,7 +251,7 @@ def _(demo_run_colors, entity, project):
return artifact_lineage, panel_grid
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Assemble, save, load, and update
@@ -267,7 +285,7 @@ def _(artifact_lineage, entity, panel_grid, project, text_blocks):
return (quickstart_report,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 4. FAQ examples: build more local drafts
@@ -312,7 +330,7 @@ def _(entity, project):
return (resize_report,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Block gallery
@@ -367,7 +385,7 @@ def _(entity, project):
return (block_gallery_report,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Panel gallery
@@ -439,7 +457,7 @@ def _(entity, project):
return (panel_gallery_report,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Related Reports, grouped colors, and combined blocks
@@ -521,7 +539,7 @@ def _(entity, project, related_report_one, related_report_two):
return (combined_report,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
### Publish the FAQ examples
@@ -574,7 +592,7 @@ def _(
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 5. Update lists of blocks explicitly
@@ -600,7 +618,7 @@ def _(entity, project):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify the saved Reports
diff --git a/marimo/convert/run-quickstart/run_quickstart.py b/marimo/convert/run-quickstart/run_quickstart.py
index a6c8beba..60387579 100644
--- a/marimo/convert/run-quickstart/run_quickstart.py
+++ b/marimo/convert/run-quickstart/run_quickstart.py
@@ -21,6 +21,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Weights & Biases Run Quickstart
A Weights & Biases run represents one experiment. It records your configuration, metrics,
diff --git a/marimo/convert/simple-pytorch-integration/simple_pytorch_integration.py b/marimo/convert/simple-pytorch-integration/simple_pytorch_integration.py
index 3f3441c3..fd9e0249 100644
--- a/marimo/convert/simple-pytorch-integration/simple_pytorch_integration.py
+++ b/marimo/convert/simple-pytorch-integration/simple_pytorch_integration.py
@@ -41,9 +41,26 @@
device = torch.device("cpu")
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Weights & Biases + PyTorch
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/simple-pytorch-integration/simple_pytorch_integration.py/server)
@@ -79,7 +96,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Follow along with a [video tutorial](https://wandb.me/pytorch-video)!
@@ -88,7 +105,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Setup and authentication
@@ -126,7 +143,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Define the Experiment and Pipeline
@@ -167,7 +184,7 @@ def _():
return (config,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Now, let's define the overall pipeline,
@@ -204,7 +221,7 @@ def model_pipeline(hyperparameters):
return model
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
The only difference here from a standard pipeline
@@ -247,7 +264,7 @@ def make(config):
return model, train_loader, test_loader, criterion, optimizer
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Define the Data Loading and Model
@@ -288,7 +305,7 @@ def make_loader(dataset, batch_size, shuffle):
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
Defining the model is normally the fun part!
@@ -327,7 +344,7 @@ def forward(self, x):
return out
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Define Training Logic
@@ -388,7 +405,7 @@ def train(model, loader, criterion, optimizer, config, run):
print(f"Loss after {str(example_ct).zfill(5)} examples: {loss:.3f}")
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
The only difference is in the logging code:
@@ -446,7 +463,7 @@ def evaluate(model, test_loader, run):
run.save(str(model_path), base_path=run.dir, policy="now")
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Run training and watch your metrics
@@ -481,7 +498,7 @@ def _(config):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify your experiment
@@ -506,7 +523,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Helper functions
diff --git a/marimo/convert/torchtune-and-wandb/torchtune_and_wandb.py b/marimo/convert/torchtune-and-wandb/torchtune_and_wandb.py
index 64ae2f78..ff4fb7d4 100644
--- a/marimo/convert/torchtune-and-wandb/torchtune_and_wandb.py
+++ b/marimo/convert/torchtune-and-wandb/torchtune_and_wandb.py
@@ -17,7 +17,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="LoRA fine-tuning with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="LoRA fine-tuning with Weights & Biases",
+)
with app.setup:
import tempfile
@@ -32,15 +35,30 @@
from trl import SFTConfig, SFTTrainer
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Fine-tune SmolLM2 with LoRA and Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/torchtune-and-wandb/torchtune_and_wandb.py/server)
-
-
This lesson uses [Transformers](https://huggingface.co/docs/transformers),
[TRL](https://huggingface.co/docs/trl), and
[PEFT](https://huggingface.co/docs/peft) to fine-tune a small language model
@@ -90,7 +108,7 @@ def _():
return authenticated, entity, project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 2. Choose the Device and Training Settings
@@ -146,7 +164,7 @@ def _():
)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 3. Stream Conversational Training Data
@@ -176,7 +194,7 @@ def _(authenticated, cache_dir, dataset_id, sample_count):
return (train_dataset,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 4. Configure LoRA
@@ -204,7 +222,7 @@ def _():
return (lora_config,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## 5. Fine-tune and Track the Experiment
diff --git a/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py b/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
index 9a07ea30..09abae48 100644
--- a/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
+++ b/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py
@@ -53,9 +53,26 @@
device = "cpu"
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/train-and-debug-yolov5-models-with-weights-biases/train_and_debug_yolov5_models_with_weights_biases.py/server)
# Train and Debug Ultralytics YOLO Models with Weights & Biases
@@ -78,7 +95,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Set up your experiment and log in
@@ -115,7 +132,7 @@ def _():
return config, entity, project, run_name
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Detect objects with a pretrained model
@@ -146,7 +163,7 @@ def _(config):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Prepare the chess-piece dataset
@@ -172,7 +189,7 @@ def _():
return data_yaml_path, dataset_root
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Fine-tune the detector and track the experiment
@@ -231,7 +248,7 @@ def _(config, data_yaml_path, dataset_root, entity, project, run_name):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify and compare your experiments
@@ -254,7 +271,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Resume interrupted training
@@ -279,7 +296,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Dataset helper
diff --git a/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py b/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
index 8138c76f..00a9ba36 100644
--- a/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py
@@ -16,7 +16,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Keras evaluation with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="Keras evaluation with Weights & Biases",
+)
with app.setup:
import marimo as mo
@@ -29,9 +32,26 @@
from wandb.integration.keras import WandbEvalCallback, WandbMetricsLogger
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Using Keras Evaluation Callbacks with Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/use-wandbevalcallback-in-your-keras-workflow/use_wandbevalcallback_in_your_keras_workflow.py/server)
@@ -50,7 +70,7 @@ def _():
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Set up your experiment and log in
@@ -78,7 +98,7 @@ def _():
return entity, project
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Hyperparameters
@@ -106,7 +126,7 @@ def _():
return (configs,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Dataset
@@ -130,7 +150,7 @@ def _(configs):
return trainloader, validloader
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Model
@@ -161,7 +181,7 @@ def get_model(configs, weights="imagenet"):
return models.Model(inputs=inputs, outputs=outputs)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Compile model
@@ -191,7 +211,7 @@ def _(configs):
return (model,)
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## `WandbEvalCallback`
@@ -247,7 +267,7 @@ def _inference(self):
return preds
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Train
@@ -281,7 +301,7 @@ def _(configs, entity, model, project, trainloader, validloader):
return
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
## Verify and next steps
diff --git a/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py b/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
index 78d13359..68327b59 100644
--- a/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py
@@ -15,7 +15,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Keras metrics with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="Keras metrics with Weights & Biases",
+)
with app.setup:
import marimo as mo
@@ -31,6 +34,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Using WandbMetricsLogger in your Keras workflow
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/use-wandbmetriclogger-in-your-keras-workflow/use_wandbmetriclogger_in_your_keras_workflow.py/server)
diff --git a/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py b/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
index 1deaa52b..42ea387f 100644
--- a/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
+++ b/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py
@@ -15,7 +15,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Keras checkpoints with Weights & Biases")
+app = marimo.App(
+ width="medium",
+ app_title="Keras checkpoints with Weights & Biases",
+)
with app.setup:
import marimo as mo
@@ -32,6 +35,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Using WandbModelCheckpoint in your Keras workflow
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/use-wandbmodelcheckpoint-in-your-keras-workflow/use_wandbmodelcheckpoint_in_your_keras_workflow.py/server)
diff --git a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
index a4777768..cf4bb36e 100644
--- a/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
+++ b/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py
@@ -15,7 +15,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Weights & Biases Sweeps with XGBoost")
+app = marimo.App(
+ width="medium",
+ app_title="Weights & Biases Sweeps with XGBoost",
+)
with app.setup:
from urllib.request import urlopen
@@ -36,6 +39,23 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
+
+
+
+
+
# Using Weights & Biases Sweeps with XGBoost
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/using-w-b-sweeps-with-xgboost/using_w_b_sweeps_with_xgboost.py/server)
diff --git a/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py b/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
index 24913108..38603b89 100644
--- a/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
+++ b/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py
@@ -11,7 +11,10 @@
import marimo
__generated_with = "0.25.1"
-app = marimo.App(width="medium", app_title="Weights & Biases Tables Quickstart")
+app = marimo.App(
+ width="medium",
+ app_title="Weights & Biases Tables Quickstart",
+)
with app.setup:
import marimo as mo
@@ -24,13 +27,9 @@
import wandb
-@app.cell(hide_code=False)
+@app.cell(hide_code=True)
def _():
mo.md(r"""
- # View & analyze model predictions during training
-
- [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/w-b-tables-quickstart/w_b_tables_quickstart.py/server)
-
 + [](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/configs-in-w-b/configs_in_w_b.py/server)
+
## Quickstart
Use [Weights & Biases](https://wandb.ai)
- for machine learning experiment tracking, dataset versioning, and project collaboration.
+ for machine learning experiment tracking, dataset versioning, visualizations, and project collaboration.
-
 - """)
+ config=config,
+ ) as config_run:
+ config_run_url = config_run.url
return
@app.cell(hide_code=True)
def _():
mo.md(r"""
- You give us a (possibly nested) dictionary as your `config`, and we'll flatten the names using dots in our backend.
+ The previous cell returns a link to [run's](https://docs.coreweave.com/products/wandb/runs) **Overview** page in the W&B App UI.
- > _Side Note_: We recommend that you avoid using dots in your config variable names, and use a dash or underscore instead. Once you've created your `config` dictionary, if your script accesses `wandb.config` keys below the root, use the dictionary access syntax, `["key"]["foo"]`, instead of the attribute access syntax, `config.key.foo`.
+ Select the link and navigate to the **Config** section. If you ran the previous cell as is, it should look similar to the following:
""")
return
-@app.cell(hide_code=True)
-def _():
- add_config_parameters = mo.ui.run_button(
- label="Add parameters to the W&B config"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Adding to the `config` by hand
- You can add more parameters to the `config` later if you want:
- """),
- add_config_parameters,
- ]
- )
- return (add_config_parameters,)
-
-
-@app.cell
-def _(add_config_parameters, config_run):
- mo.stop(
- not add_config_parameters.value,
- mo.callout(
- mo.md(
- "Click the button above to add `epochs` and `batch_size` to "
- "this run's config."
- ),
- kind="info",
- ),
- )
-
- config_run.config.epochs = 4
- config_run.config["batch_size"] = 32
-
- manual_config_update = True
- dict(config_run.config)
- return
-
-
@app.cell(hide_code=True)
def _():
mo.md(r"""
- Now, your Config section on the dashboard has been updated:
+
 + > Use dashes (-) or underscores (_) instead of periods (.) in your config variable names. For more information, see [Configure experiments](https://docs.coreweave.com/products/wandb/track/config).
""")
return
@app.cell(hide_code=True)
def _():
- add_argparse_parameters = mo.ui.run_button(
- label="Add argparse parameters to the W&B config"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Adding to the `config` with `argparse`
-
- `config` is a dictionary-like object, and it can be built from lots of dictionary-like objects.
-
- For example, you can pass in the arguments object produced by `argparse`.
- [`argparse`](https://docs.python.org/3/library/argparse.html), short for `arg`ument `parse`r, is a standard library module in Python 3.2 and above that makes it easy to write scripts that take advantage of all the flexibility and power of command line arguments. And it's Pythonic!
-
- This is especially convenient for tracking results from scripts that are launched from the command line.
- """),
- add_argparse_parameters,
- ]
- )
- return (add_argparse_parameters,)
+ mo.md(r"""
+ ## Example: Update an existing config
+ Use the [W&B Public API](https://docs.coreweave.com/products/wandb/ref/python/public-api) to update a completed run’s config.
+ You must provide the API with your team entity, the name of the project the run was logged to, and the [run’s ID](https://docs.coreweave.com/products/wandb/runs/run-identifiers#run-id).
-@app.cell
-def _(add_argparse_parameters, config_run):
- mo.stop(
- not add_argparse_parameters.value,
- mo.callout(
- mo.md("Click the button above to add the parsed arguments to this run's config."),
- kind="info",
- ),
- )
- parser = argparse.ArgumentParser()
- parser.add_argument('-b', '--batch_per_gpu', type=int, default=8,
- help='input batch size for training (default: 8)')
- parser.add_argument('-wd', '--weight_decay', type=float, default=0.1,
- help='weight decay (default: 0.1)')
+ ```
+ wandb: setting up run
+ ```
- args = parser.parse_args(args=[])
- config_run.config.update(args)
- return
+ This is the run's ID. Copy it and replace "run_id" in the following cell.
+ > You can also find a [run's ID programmatically or with the W&B App](https://docs.coreweave.com/products/wandb/runs/run-identifiers#find-a-run%E2%80%99s-id).
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Here's the updated Config panel:
+ The following cell adds a new config value (`bar`) to your existing run object.
""")
return
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
-
 - """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- update_config_with_api = mo.ui.run_button(
- label="Update the W&B config with the Public API"
- )
- mo.vstack(
- [
- mo.md(r"""
- ### Updating the `config` with the API
-
- What if your run has finished, but you realized you forgot to log something?
-
- Never fear, you can always use the
- [public API](https://docs.wandb.ai/ref/python/public-api)
- to update your `config`
- (or anything else about your run!)
- at any time. You just need to know the details of the `run` you want to update.
- """),
- update_config_with_api,
- ]
- )
- return (update_config_with_api,)
-
-
@app.cell
-def _(config_run, update_config_with_api):
- mo.stop(
- not update_config_with_api.value,
- mo.callout(
- mo.md("Click the button above to add `bar` through the W&B Public API."),
- kind="info",
- ),
- )
+def _(wandb_settings):
+ run_id = "iomdo1ui" # replace with the run ID you want to update
api = wandb.Api()
+ api_run = api.run(f"{wandb_settings["entity"]}/{wandb_settings["project"]}/{run_id}")
- # pulling the relevant info automatically from the run object
- # this can also be found on the website
- username = config_run.entity
- project = config_run.project
- run_id = config_run.id
- api_run = api.run(f"{username}/{project}/{run_id}")
- api_run.config["bar"] = 32
+ api_run.config["epochs"] = 4
+ api_run.config['batch_size'] = 32
api_run.update()
return
-@app.cell
-def _():
- mo.md(r"""
- Here's what the final Config panel looks like:
- """)
- return
-
-
@app.cell(hide_code=True)
def _():
mo.md(r"""
-
 - """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ## Using `config` for great good!
- The `config` parameters are useful for performing grouping, filtering, and aggregating on your experiments and their results.
-
- ### The examples below come from the project [here](https://wandb.ai/wandb/DistHyperOpt).
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Filtering Runs
- Filter tab allows you to display the runs that quality one or more conditions. These conditions can be formed by applying relational operators to any of the parameters logged in the `config` file.
-
- [Our example project](https://wandb.ai/wandb/DistHyperOpt) compares various hyper-parameter tuning methods and has more than 80 runs. Each run has a "Job Type" logged in the `config` which corresponds
-
- Let's say you want to visualize only the ones that are generated by a particular tuning algorithm, like Population Based Traing (`pbt`). You can do that by applying a filter on "Job Type".
-
- Run the cell below to see this in action!
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.Html(r"""
-
-
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Grouping Runs
- You can group your experiments in the dashboard of your project based on a particular column from `config`. A common use case for this would be grouping sub-experiments within a larger project.
-
- Our runs are grouped based on "Job Type". The Group tab is located next to the Filter Tab. You can group your runs by any parameter present in the config.
-
- 
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- ### Parallel Coordinates Chart
-
- Often, the main thing we want to do with a group of Runs is make comparisons.
-
- The W&B Dashboard includes a Chart type for exactly this purpose:
- the Parallel Coordinates chart.
+ ## Next steps:
- A Parallel Coordinates chart represents each Run in the group as a line.
- This line passes through as many of the `config` values
- or logged metrics as you like,
- and is colored by its value on a single metric.
- This lets you take in, at a glance,
- which hyperparameter configurations were most and least successful.
- See the example below.
+ There are more ways to create, update, and mange config values for your experiments. Read the [Configure experiments documentation](https://docs.coreweave.com/products/wandb/track/config) to learn more.
- Head to a [group of Runs in this project](https://wandb.ai/wandb/DistHyperOpt/groups/dcgan_train)
- and build a Parallel Coordinates chart like the one pictured below
- by
- 1. clicking the + sign in the top-right corner, aligned with "Charts",
- 2. selecting "Parallel Coordinates" from the available Charts, and
- 3. adding the columns in the image, in order.
- 
+ For a live demo, explore this example [CoreWeave Project](https://wandb.ai/wandb/DistHyperOpt) to experiment with.
""")
return
From ccc971e53716e9e21b35277d1aa7f015428ddbd8 Mon Sep 17 00:00:00 2001
From: Noah Luna <15202580+ngrayluna@users.noreply.github.com>
Date: Fri, 2 Oct 2026 16:55:24 -0700
Subject: [PATCH 02/48] update hugging face example
---
.../huggingface-wandb/huggingface_wandb.py | 233 +++++++-----------
1 file changed, 91 insertions(+), 142 deletions(-)
diff --git a/marimo/convert/huggingface-wandb/huggingface_wandb.py b/marimo/convert/huggingface-wandb/huggingface_wandb.py
index 7c13e88c..47facd69 100644
--- a/marimo/convert/huggingface-wandb/huggingface_wandb.py
+++ b/marimo/convert/huggingface-wandb/huggingface_wandb.py
@@ -4,6 +4,10 @@
# "datasets",
# "evaluate",
# "fsspec[http]==2026.6.0",
+# "marimo",
+# "scikit-learn==1.9.1",
+# "scipy==1.18.1",
+# "torch==2.14.1",
# "transformers @ git+https://github.com/huggingface/transformers",
# "wandb==0.29.0",
# ]
@@ -11,7 +15,7 @@
import marimo
-__generated_with = "0.24.0"
+__generated_with = "0.25.1"
app = marimo.App(auto_download=["html"])
with app.setup:
@@ -24,6 +28,8 @@
import torch
import wandb
import fsspec
+ import sklearn
+ import scipy
# Optional: log both gradients and parameters
os.environ['WANDB_WATCH'] = 'all'
@@ -32,95 +38,27 @@
@app.cell(hide_code=True)
def _():
mo.md(r"""
- # Hugging Face + W&B
+ # Hugging Face + Weights & Biases
[](https://molab.marimo.io/github/wandb/examples/blob/main/marimo/convert/huggingface-wandb/huggingface_wandb.py/server)
- """)
- return
-
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
- Visualize your [Hugging Face](https://github.com/huggingface/transformers) model's performance quickly with a seamless [W&B](https://wandb.ai/site) integration.
-
- Compare hyperparameters, output metrics, and system stats like GPU utilization across your models.
-
-
 - """)
- return
-
-@app.cell(hide_code=True)
-def _():
- mo.md(r"""
-
- ## Why should I use W&B?
-
- Use [Weights & Biases](https://wandb.com) for machine learning experiment tracking, dataset versioning, and project collaboration.
-
-